


什么是MCP-Client?
MCP-Client是Model Context Protocol(模型上下文协议)架构中的一个重要组件,用于连接AI模型(如Claude、GPT等大型语言模型)与外部数据源、工具和服务的桥梁。
MCP(Model Context Protocol)是由Anthropic公司在2024年底首次提出并开源的一种开放标准协议,旨在解决大语言模型(LLM)与外部世界的连接问题。这一协议的核心价值在于打破了AI模型的"信息孤岛"限制,使模型能够以标准化的方式访问和处理实时数据,显著扩展了大模型的应用场景。
在MCP架构中,有三个关键组件:
- MCP服务器(
Server):轻量级服务程序,负责对接具体数据源或工具(如数据库、API等),并按照MCP规范提供标准化的功能接口。每个MCP服务器封装了特定的能力,如文件检索、数据库查询等。 - MCP客户端(
Client):嵌入在AI应用中的连接器,与MCP服务器建立一对一连接,充当模型与服务器之间的桥梁。它负责发现可用服务、发送调用请求、获取结果,并将这些信息传递给AI模型。 - 宿主应用(
Host):运行LLM的应用程序或环境,如Claude桌面应用、Cursor IDE等。宿主通过集成MCP客户端,使其内部的模型能够调用外部MCP服务器的能力。
MCP-Client的工作原理是基于JSON-RPC 2.0协议,通过标准化的接口与MCP服务器进行通信。它能够自动发现可用的MCP服务器及其提供的工具,并将这些信息以结构化的方式提供给大语言模型,使模型能够理解可用的工具及其功能,从而根据用户需求决定何时何地调用这些工具。
为什么要自写MCP-Client?
自主开发MCP-Client有几个重要的原因和优势:
- 定制化需求:市场上的通用
MCP客户端(例如:ClaudeDesktop、Cursor、Cline等等)可能无法满足特定业务场景的需求。通过自主开发,可以根据企业或个人的具体需求进行定制,比如添加特定的安全验证、数据过滤、或针对特定领域的优化。 - 系统集成:将
MCP-Client与现有系统无缝集成。自主开发的MCP-Client可以更好地适配已有的技术栈和架构,减少兼容性问题,提高开发效率。 - 数据隐私与安全:对于敏感数据或内部系统,自主开发的
MCP-Client可以实现更严格的权限控制和数据保护措施,确保敏感信息不会被未授权访问或泄露。 - 性能优化:针对特定用例优化性能。例如,对于需要高频率、低延迟访问的场景,可以通过定制
MCP-Client来减少通信开销,提高响应速度。 - 扩展功能:实现标准
MCP协议之外的增强功能。比如添加高级缓存机制、请求队列管理、负载均衡,或针对特定AI模型优化的上下文处理逻辑。 - 控制和可维护性:对于依赖
AI能力的核心业务,自主开发的MCP-Client意味着更好的控制能力和可维护性。当需求变化或出现问题时,可以快速进行调整和修复,而不必依赖第三方供应商。 - 适配多种AI模型:自主开发的
MCP-Client可以设计为同时支持多种不同的大语言模型(如Claude、GPT等),根据任务需求动态选择最适合的模型,提高系统灵活性。 - 特殊协议支持:对于需要使用特殊通信协议或数据格式的场景,自主开发可以实现这些非标准需求。
- 降低依赖风险:减少对第三方服务的依赖,增强系统的独立性和韧性。如果第三方服务发生变更或中断,自主开发的系统可以更快地适应和调整。
- 专业知识沉淀:通过自主开发
MCP-Client,团队可以积累AI与外部系统集成的专业知识和经验,这对于长期的AI战略和能力建设非常有价值。
实际上,随着AI应用的深入和普及,越来越多的组织开始认识到,AI基础设施(包括MCP-Client)是一种战略性资产。自主开发这些组件不仅可以获得更好的技术匹配度,还能在竞争中获得差异化优势,尤其是在AI技术对业务至关重要的领域。
MCP协议的开放性恰恰为自主开发MCP-Client提供了可能,使得组织和开发者能够在标准化框架下创建适合自己需求的定制解决方案,同时仍然保持与整个生态系统的互操作性。通过自写MCP-Client,开发者可以充分利用AI大模型的能力,同时保持对系统架构和数据流的完全控制。
MCP-Client编写
工程搭建
在本节实验中,需要大家自己准备一个适配openai协议的大模型API,例如:deepseek V3,Qwen系列,Moonshot月之暗面等等。
为了编写MCP Client,在这里我们直接使用上一节(从0开始实现MCP-Server)中,创建好的工程。
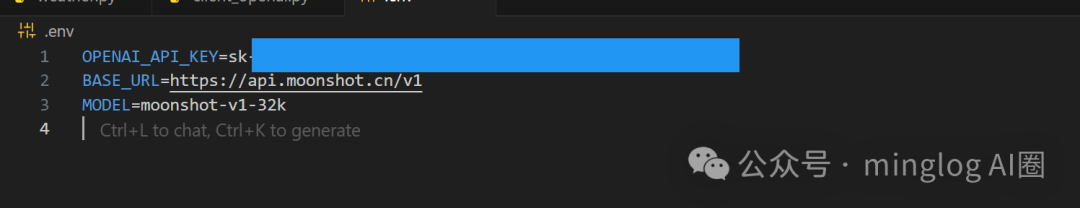
首先创建环境变量.env文件,在该文件中我们放入自己的大模型相关信息:
主要包含3个字段:
OPENAI_API_KEY:大模型的API KEYBASE_URL:大模型请求地址MODEL:模型名称
“
这里对模型的种类不限,我使用的是
moonshot,大家使用其他大模型均可。
MCP-Prompt
目前支持或深度集成MCP协议的大模型,主要包括:Claude系列和GPT系列等。
国内的大模型供应商对于MCP协议基本上没有做针对性的集成训练,所以在国内使用MCP协议,必须编写结构化的MCP-Prompt,通过system prompt的方式让国内的大模型具备适配MCP协议。
为了编写这个提示词,我使用cloudflare对大模型进行代理,然后对Cursor的MCP请求进行截获并将MCP提示词相关内容保留,其他无关内容删除,得到以下提示词,当然大家也可以自行对这个提示词进行修改,实现自己的定制化。
在工程中创建文件MCP_Prompt.txt,将以下内容放入文件中。
You are an AI assistant, you can help users solve problems, including but not limited to programming, editing files, browsing websites, etc.

====

TOOL USE

You have access to a set of tools that are executed upon the user's approval. You can use one tool per message, and will receive the result of that tool use in the user's response. You use tools step-by-step to accomplish a given task, with each tool use informed by the result of the previous tool use.

# Tool Use Formatting

Tool use is formatted using XML-style tags. The tool name is enclosed in opening and closing tags, and each parameter is similarly enclosed within its own set of tags. Here's the structure:

<tool_name>
<parameter1_name>value1</parameter1_name>
<parameter2_name>value2</parameter2_name>
...
</tool_name>

For example:

<read_file>
<path>src/main.js</path>
</read_file>

Always adhere to this format for the tool use to ensure proper parsing and execution.

# Tools
## use_mcp_tool
Description: Request to use a tool provided by a connected MCP server. Each MCP server can provide multiple tools with different capabilities. Tools have defined input schemas that specify required and optional parameters.
Parameters:
- server_name: (required) The name of the MCP server providing the tool
- tool_name: (required) The name of the tool to execute
- arguments: (required) A JSON object containing the tool's input parameters, following the tool's input schema
Usage:
<use_mcp_tool>
<server_name>server name here</server_name>
<tool_name>tool name here</tool_name>
<arguments>
{
  "param1": "value1",
  "param2": "value2"
}
</arguments>
</use_mcp_tool>

# Tool Use Examples
## Example 1: Requesting to use an MCP tool

<use_mcp_tool>
<server_name>weather-server</server_name>
<tool_name>get_forecast</tool_name>
<arguments>
{
  "city": "San Francisco",
  "days": 5
}
</arguments>
</use_mcp_tool>

## Example 2: Another example of using an MCP tool (where the server name is a unique identifier such as a URL)

<use_mcp_tool>
<server_name>github.com/modelcontextprotocol/servers/tree/main/src/github</server_name>
<tool_name>create_issue</tool_name>
<arguments>
{
  "owner": "octocat",
  "repo": "hello-world",
  "title": "Found a bug",
  "body": "I'm having a problem with this.",
  "labels": ["bug", "help wanted"],
  "assignees": ["octocat"]
}
</arguments>
</use_mcp_tool>

===

MCP SERVERS

The Model Context Protocol (MCP) enables communication between the system and locally running MCP servers that provide additional tools and resources to extend your capabilities.

# Connected MCP Servers

When a server is connected, you can use the server's tools via the `use_mcp_tool` tool, and access the server's resources via the `access_mcp_resource` tool.
<$MCP_INFO$>

===

CAPABILITIES
- You have access to MCP servers that may provide additional tools and resources. Each server may provide different capabilities that you can use to accomplish tasks more effectively.

====

RULES
- MCP operations should be used one at a time, similar to other tool usage. Wait for confirmation of success before proceeding with additional operations.

====

OBJECTIVE

You accomplish a given task iteratively, breaking it down into clear steps and working through them methodically.

1. Analyze the user's task and set clear, achievable goals to accomplish it. Prioritize these goals in a logical order.
2. Work through these goals sequentially, utilizing available tools one at a time as necessary. Each goal should correspond to a distinct step in your problem-solving process. You will be informed on the work completed and what's remaining as you go.
3. Once you've completed the user's task, you must use the attempt_completion tool to present the result of the task to the user.
4. The user may provide feedback, which you can use to make improvements and try again. But DO NOT continue in pointless back and forth conversations, i.e. don't end your responses with questions or offers for further assistance."
“
在这个提示词中,我设置了一个特殊的标记符
<$MCP_INFO$>,该标记符用于后期载入MCP Server及MCP Tool相关工具的描述信息。
Stdio通信协议
stdio 传输方式是最简单的通信方式,通常在本地工具之间进行消息传递时使用。它利用标准输入输出(stdin/stdout)作为数据传输通道,适用于本地进程间的交互。
在这里我们首先以上一节(从0开始实现MCP-Server)中构建的weather MCP Server为例,编写MCP Client向MCP Server进行请求。
编写mcp_client_stdio.py代码如下所示:
import asyncio
from typing import Optional
from contextlib import AsyncExitStack
import json

from mcp import ClientSession, StdioServerParameters
from mcp.client.stdio import stdio_client
from mcp.client.sse import sse_client

from dotenv import load_dotenv
import os, re
from openai import OpenAI
from lxml import etree

load_dotenv()  # 加载.env文件内容到环境变量中

class MCPClient:
    def __init__(self):
        # Initialize session and client objects
        self.session: Optional[ClientSession] = None
        self.exit_stack = AsyncExitStack()
        # 需要提前在.env文件中设置相关环境变量
        self.API_KEY = os.getenv("API_KEY")
        self.BASE_URL = os.getenv("BASE_URL")
        self.MODEL = os.getenv("MODEL")
        # 创建LLM client
        self.client = OpenAI(api_key=self.API_KEY, base_url=self.BASE_URL)
        # 存储历史消息
        self.messages = []
        # 读取提示词模板
        with open("./MCP_Prompt.txt", "r", encoding="utf-8") as file:
            self.system_prompt = file.read()

    async def connect_to_stdio_server(self, mcp_name, command: str, args: list[str], env: dict[str, str]={}):
        """Connect to an MCP server

        Args:
            server_script_path: Path to the server script (.py or .js)
        """
        server_params = StdioServerParameters(
            command=command,
            args=args,
            env=env
        )

        stdio_transport = await self.exit_stack.enter_async_context(stdio_client(server_params))
        self.stdio, self.write = stdio_transport
        self.session = await self.exit_stack.enter_async_context(ClientSession(self.stdio, self.write))

        await self.session.initialize()
        # 将MCP信息添加到system_prompt
        response = await self.session.list_tools()
        available_tools = ['##' + mcp_name + '\n### Available Tools\n- ' + tool.name + "\n" + tool.description + "\n" + json.dumps(tool.inputSchema) for tool in response.tools]
        self.system_prompt = self.system_prompt.replace("<$MCP_INFO$>", "\n".join(available_tools)+"\n<$MCP_INFO$>")
        tools = response.tools
        print(f"Successfully connected to {mcp_name} server with tools:", [tool.name for tool in tools])

    async def process_query(self, query: str) -> str:
        """Process a query using Claude and available tools"""
        self.messages.append(
            {
                "role": "system",
                "content": self.system_prompt
            }
        )
        self.messages.append(
            {
                "role": "user",
                "content": query
            }
        )

        # Initial Claude API call
        response = self.client.chat.completions.create(
            model=self.MODEL,
            max_tokens=1024,
            messages=self.messages,
        )

        # Process response and handle tool calls
        final_text = []
        content = response.choices[0].message.content
        if'<use_mcp_tool>'notin content:
            final_text.append(content)
        else:
            # 解析tool_string
            server_name, tool_name, tool_args = self.parse_tool_string(content)

            # 执行工具调用
            result = await self.session.call_tool(tool_name, tool_args)
            print(f"[Calling tool {tool_name} with args {tool_args}]")
            print("-"*40)
            print("Server:", server_name)
            print("Tool:", tool_name)
            print("Args:", tool_args)
            print("-"*40)
            print("Result:", result.content[0].text)
            print("-"*40)
            self.messages.append({
                "role": "assistant",
                "content": content
            })
            self.messages.append({
                "role": "user",
                "content": f"[Tool {tool_name} \n returned: {result}]"
            })

            response = self.client.chat.completions.create(
                model=self.MODEL,
                max_tokens=1024,
                messages=self.messages
            )
            final_text.append(response.choices[0].message.content)
        return"\n".join(final_text)

    def parse_tool_string(self, tool_string: str) -> tuple[str, str, dict]:
        """
        解析大模型工具调用返回的字符串
        """
        tool_string = re.findall("(<use_mcp_tool>.*?</use_mcp_tool>)", tool_string, re.S)[0]
        root = etree.fromstring(tool_string)
        server_name = root.find('server_name').text
        tool_name = root.find('tool_name').text
        try:
            tool_args = json.loads(root.find('arguments').text)
        except json.JSONDecodeError:
            raise ValueError("Invalid tool arguments")
        return server_name, tool_name, tool_args

    async def chat_loop(self):
        """Run an interactive chat loop"""
        print("\nMCP Client Started!")
        print("Type your queries or 'quit' to exit.")
        self.messages = []
        whileTrue:
            try:
                query = input("\nQuery: ").strip()

                if query.lower() == 'quit':
                    break
                if query.strip() == '':
                    print("Please enter a query.")
                    continue
                response = await self.process_query(query)
                print(response)

            except Exception as e:
                print(f"\nError: {str(e)}")

    async def cleanup(self):
        """Clean up resources"""
        await self.exit_stack.aclose()

async def main():
    client = MCPClient()
    try:
        await client.connect_to_stdio_server('weather', 'python', ['weather.py'])
        await client.chat_loop()
    finally:
        await client.cleanup()

if __name__ == "__main__":
    asyncio.run(main())
“
注意:这里调用的是上一节中编写的
weather MCP Server,所以weather.py文件应该和mcp_client_stdio.py文件在同一目录下。
代码执行效果演示:
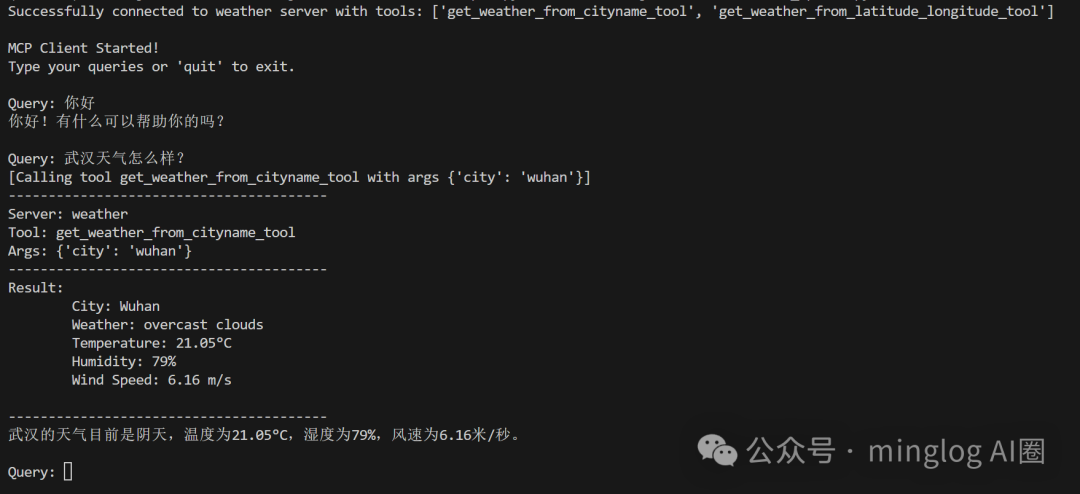
MCP Server调用成功!
SSE通信协议
SSE 是基于 HTTP 协议的流式传输机制,它允许服务器通过 HTTP 单向推送事件到客户端。SSE 适用于客户端需要接收服务器推送的场景,通常用于实时数据更新。
在这里同样可以以上一节中,我们在公网中搭建的weather MCP SSE Server。
编写代码mcp_client_sse.py如下所示:
import asyncio
from typing import Optional
from contextlib import AsyncExitStack
import json

from mcp import ClientSession, StdioServerParameters
from mcp.client.stdio import stdio_client
from mcp.client.sse import sse_client

from dotenv import load_dotenv
import os, re
from openai import OpenAI
from lxml import etree

load_dotenv()  # 加载.env文件内容到环境变量中

class MCPClient:
    def __init__(self):
        # Initialize session and client objects
        self.session: Optional[ClientSession] = None
        self.exit_stack = AsyncExitStack()
        # 需要提前在.env文件中设置相关环境变量
        self.API_KEY = os.getenv("API_KEY")
        self.BASE_URL = os.getenv("BASE_URL")
        self.MODEL = os.getenv("MODEL")
        # 创建LLM client
        self.client = OpenAI(api_key=self.API_KEY, base_url=self.BASE_URL)
        # 存储历史消息
        self.messages = []
        # 读取提示词模板
        with open("./MCP_Prompt.txt", "r", encoding="utf-8") as file:
            self.system_prompt = file.read()

    async def connect_to_sse_server(self, mcp_name, server_url: str):
        stdio_transport = await self.exit_stack.enter_async_context(sse_client(server_url))
        self.sse, self.write = stdio_transport
        self.session = await self.exit_stack.enter_async_context(ClientSession(self.sse, self.write))

        await self.session.initialize()
        # List available tools
        response = await self.session.list_tools()
        available_tools = ['##' + mcp_name + '\n### Available Tools\n- ' + tool.name + "\n" + tool.description + "\n" + json.dumps(tool.inputSchema) for tool in response.tools]
        self.system_prompt = self.system_prompt.replace("<$MCP_INFO$>", "\n".join(available_tools)+"\n<$MCP_INFO$>\n")
        tools = response.tools
        print(f"Successfully connected to {mcp_name} server with tools:", [tool.name for tool in tools])

    async def process_query(self, query: str) -> str:
        """Process a query using Claude and available tools"""
        self.messages.append(
            {
                "role": "system",
                "content": self.system_prompt
            }
        )
        self.messages.append(
            {
                "role": "user",
                "content": query
            }
        )

        # Initial Claude API call
        response = self.client.chat.completions.create(
            model=self.MODEL,
            max_tokens=1024,
            messages=self.messages,
        )

        # Process response and handle tool calls
        final_text = []
        content = response.choices[0].message.content
        if'<use_mcp_tool>'notin content:
            final_text.append(content)
        else:
            # 解析tool_string
            server_name, tool_name, tool_args = self.parse_tool_string(content)

            # 执行工具调用
            result = await self.session.call_tool(tool_name, tool_args)
            print(f"[Calling tool {tool_name} with args {tool_args}]")
            print("-"*40)
            print("Server:", server_name)
            print("Tool:", tool_name)
            print("Args:", tool_args)
            print("-"*40)
            print("Result:", result.content[0].text)
            print("-"*40)
            self.messages.append({
                "role": "assistant",
                "content": content
            })
            self.messages.append({
                "role": "user",
                "content": f"[Tool {tool_name} \n returned: {result}]"
            })

            response = self.client.chat.completions.create(
                model=self.MODEL,
                max_tokens=1024,
                messages=self.messages
            )
            final_text.append(response.choices[0].message.content)
        return"\n".join(final_text)

    def parse_tool_string(self, tool_string: str) -> tuple[str, str, dict]:
        """
        解析大模型工具调用返回的字符串
        """
        tool_string = re.findall("(<use_mcp_tool>.*?</use_mcp_tool>)", tool_string, re.S)[0]
        root = etree.fromstring(tool_string)
        server_name = root.find('server_name').text
        tool_name = root.find('tool_name').text
        try:
            tool_args = json.loads(root.find('arguments').text)
        except json.JSONDecodeError:
            raise ValueError("Invalid tool arguments")
        return server_name, tool_name, tool_args

    async def chat_loop(self):
        """Run an interactive chat loop"""
        print("\nMCP Client Started!")
        print("Type your queries or 'quit' to exit.")
        self.messages = []
        whileTrue:
            try:
                query = input("\nQuery: ").strip()

                if query.lower() == 'quit':
                    break
                if query.strip() == '':
                    print("Please enter a query.")
                    continue
                response = await self.process_query(query)
                print(response)

            except Exception as e:
                print(f"\nError: {str(e)}")

    async def cleanup(self):
        """Clean up resources"""
        await self.exit_stack.aclose()

async def main():
    client = MCPClient()
    try:
         await client.connect_to_sse_server('weather_sse', 'http://47.113.225.16:8000/sse')
        await client.chat_loop()
    finally:
        await client.cleanup()

if __name__ == "__main__":
    asyncio.run(main())
执行效果演示:
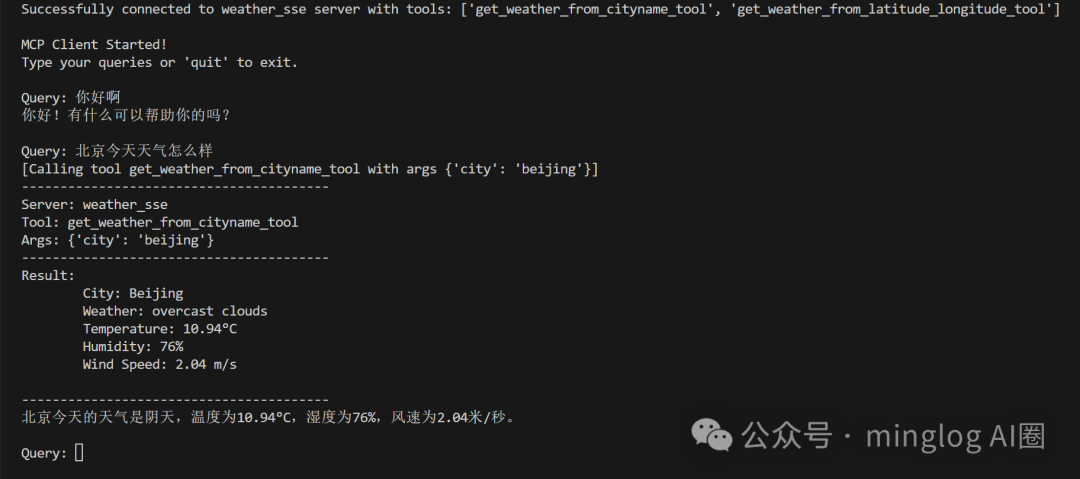
同样可以成功调用MCP SSE Server。
“
大家可以直接调用我部署好的
MCP SSE Server,为了方便大家学习,这里可以直接使用的部署好的服务
http://47.113.225.16:8000/sse来进行测试。当然也鼓励大家换成其他的服务尝试。
采用配置文件进行加载
经过前面的实验,我们现在已经可以通过自己编写的MCP Client连接任意MCP Server,包括stdio和sse通信协议,但是都只连接了一个MCP Server。用过Cursor或其他MCP Client应用的同学应该很清楚,他们是通过一个JSON配置文件去加载多个MCP Server,那么我们自己编写的MCP Client能否达到这个效果呢?
当然可以,接下来的实验我们就一起来编写相关代码,实现这个需求。
首先,我们定义自己的JSON文件协议,例如:
{
    "mcpServers": {
      "weather-sse": {
        "isActive": true,
        "type": "stdio",
        "command": "python",
        "args": [
          "weather.py"
        ],
        "name": "weather-sse",
        "env": {}
      },
      "amap-amap-sse": {
        "isActive": true,
        "type": "sse",
        "url": "https://mcp.amap.com/sse?key={高德API KEY}",
        "name": "amap-amap-sse"
      }
    }
  }
“
注意:
{高德API KEY}大家可以去高德官网注册账号,可以免费获取。
字段意义如下所示:
-
公共字段:
-
isActive:用于控制该MCP Server是否被激活。type:MCP Server的类型,取值为stdio或ssename:MCP Server别名。
-
stdio相关字段: -
command:命令名称。args:参数列表env:环境变量字典
-
sse相关参数: -
url:SSE MCP Server服务地址。
编写mcp_client_mix.py文件,内容如下所示:
import asyncio
from typing import Optional
from contextlib import AsyncExitStack
import json

from mcp import ClientSession, StdioServerParameters
from mcp.client.stdio import stdio_client
from mcp.client.sse import sse_client

from dotenv import load_dotenv
import os, re
from openai import OpenAI
from lxml import etree

load_dotenv()  # load environment variables from .env

class MCPClient:
    def __init__(self):
        # Initialize session and client objects
        self.session: Optional[ClientSession] = None
        self.exit_stack = AsyncExitStack()
        # 需要提前在.env文件中设置相关环境变量
        self.API_KEY = os.getenv("API_KEY")
        self.BASE_URL = os.getenv("BASE_URL")
        self.MODEL = os.getenv("MODEL")
        self.client = OpenAI(api_key=self.API_KEY, base_url=self.BASE_URL)
        self.sessions = {}
        self.messages = []
        with open("./MCP_Prompt.txt", "r", encoding="utf-8") as file:
            self.system_prompt = file.read()

    async def mcp_json_config(self, mcp_json_file):
        try:
            with open(mcp_json_file, 'r') as f:
                mcp_config: dict = json.load(f)
        except json.JSONDecodeError:
            raise ValueError("Invalid MCP config")
        servers_config: dict = mcp_config.get('mcpServers', {})
        for k, v in servers_config.items():
            try:
                print('-'*50)
                if v.get('isActive', False) == False:
                    continue
                mcp_name = v.get('name', k)
                mcp_type: str = v.get('type', 'stdio')
                if mcp_type.lower() == 'stdio':
                    command = v.get('command', None)
                    args = v.get('args', [])
                    env = v.get('env', {})
                    if command isNone:
                        raise ValueError(f'{mcp_name} command is empty.')
                    if args == []:
                        raise ValueError(f'{mcp_name} args is empty.')
                    await self.connect_to_stdio_server(mcp_name, command, args, env)
                elif mcp_type.lower() == 'sse':
                    server_url = v.get('url', None)
                    if server_url isNone:
                        raise ValueError(f'{mcp_name} server_url is empty.')
                    await self.connect_to_sse_server(mcp_name, server_url)
                else:
                    raise ValueError(f'{mcp_name} mcp type must in [stdio, sse].')
            except Exception as e:
                print(f"Error connecting to {mcp_name}: {e}")

    async def connect_to_stdio_server(self, mcp_name, command: str, args: list[str], env: dict[str, str]={}):
        """Connect to an MCP server

        Args:
            server_script_path: Path to the server script (.py or .js)
        """
        server_params = StdioServerParameters(
            command=command,
            args=args,
            env=env
        )

        stdio_transport = await self.exit_stack.enter_async_context(stdio_client(server_params))
        self.stdio, self.write = stdio_transport
        self.session = await self.exit_stack.enter_async_context(ClientSession(self.stdio, self.write))
        self.sessions[mcp_name] = self.session

        await self.session.initialize()
        # 将MCP信息添加到system_prompt
        response = await self.session.list_tools()
        available_tools = ['##' + mcp_name + '\n### Available Tools\n- ' + tool.name + "\n" + tool.description + "\n" + json.dumps(tool.inputSchema) for tool in response.tools]
        self.system_prompt = self.system_prompt.replace("<$MCP_INFO$>", "\n".join(available_tools)+"\n<$MCP_INFO$>")
        tools = response.tools
        print(f"Successfully connected to {mcp_name} server with tools:", [tool.name for tool in tools])

    async def connect_to_sse_server(self, mcp_name, server_url: str):
        """Connect to an MCP server

        Args:
            server_script_path: Path to the server script (.py or .js)
        """
        stdio_transport = await self.exit_stack.enter_async_context(sse_client(server_url))
        self.sse, self.write = stdio_transport
        self.session = await self.exit_stack.enter_async_context(ClientSession(self.sse, self.write))
        self.sessions[mcp_name] = self.session

        await self.session.initialize()
        # List available tools
        response = await self.session.list_tools()
        available_tools = ['##' + mcp_name + '\n### Available Tools\n- ' + tool.name + "\n" + tool.description + "\n" + json.dumps(tool.inputSchema) for tool in response.tools]
        self.system_prompt = self.system_prompt.replace("<$MCP_INFO$>", "\n".join(available_tools)+"\n<$MCP_INFO$>\n")
        tools = response.tools
        print(f"Successfully connected to {mcp_name} server with tools:", [tool.name for tool in tools])

    async def process_query(self, query: str) -> str:
        """Process a query using Claude and available tools"""
        self.messages.append(
            {
                "role": "system",
                "content": self.system_prompt
            }
        )
        self.messages.append(
            {
                "role": "user",
                "content": query
            }
        )

        # Initial Claude API call
        response = self.client.chat.completions.create(
            model=self.MODEL,
            max_tokens=1024,
            messages=self.messages,
        )

        # Process response and handle tool calls
        final_text = []
        content = response.choices[0].message.content
        if'<use_mcp_tool>'notin content:
            final_text.append(content)
        else:
            # 解析tool_string
            server_name, tool_name, tool_args = self.parse_tool_string(content)

            # 执行工具调用
            result = await self.sessions[server_name].call_tool(tool_name, tool_args)
            print(f"[Calling tool {tool_name} with args {tool_args}]")
            print("-"*40)
            print("Server:", server_name)
            print("Tool:", tool_name)
            print("Args:", tool_args)
            print("-"*40)
            print("Result:", result.content[0].text)
            print("-"*40)
            self.messages.append({
                "role": "assistant",
                "content": content
            })
            self.messages.append({
                "role": "user",
                "content": f"[Tool {tool_name} \n returned: {result}]"
            })

            response = self.client.chat.completions.create(
                model=self.MODEL,
                max_tokens=1024,
                messages=self.messages
            )
            final_text.append(response.choices[0].message.content)
        return"\n".join(final_text)

    def parse_tool_string(self, tool_string: str) -> tuple[str, str, dict]:
        tool_string = re.findall("(<use_mcp_tool>.*?</use_mcp_tool>)", tool_string, re.S)[0]
        root = etree.fromstring(tool_string)
        server_name = root.find('server_name').text
        tool_name = root.find('tool_name').text
        try:
            tool_args = json.loads(root.find('arguments').text)
        except json.JSONDecodeError:
            raise ValueError("Invalid tool arguments")
        return server_name, tool_name, tool_args

    async def chat_loop(self):
        """Run an interactive chat loop"""
        print("\nMCP Client Started!")
        print("Type your queries or 'quit' to exit.")
        self.messages = []
        whileTrue:
            try:
                query = input("\nQuery: ").strip()

                if query.lower() == 'quit':
                    break
                if query.strip() == '':
                    print("Please enter a query.")
                    continue
                response = await self.process_query(query)
                print(response)

            except Exception as e:
                print(f"\nError: {str(e)}")

    async def cleanup(self):
        """Clean up resources"""
        await self.exit_stack.aclose()

async def main():
    client = MCPClient()
    try:
        mcp_config_file = './mcp.json'
        await client.mcp_json_config(mcp_config_file)
        await client.chat_loop()
    finally:
        await client.cleanup()

if __name__ == "__main__":
    asyncio.run(main())
演示效果如下所示:
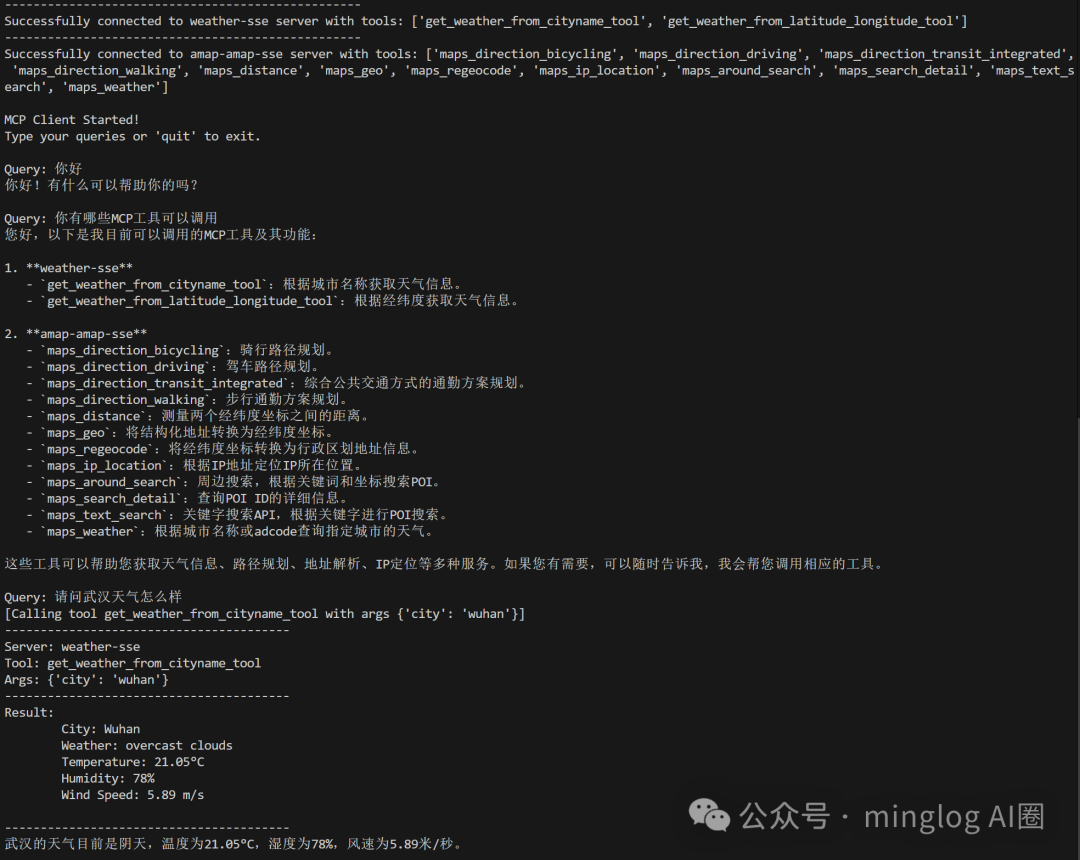
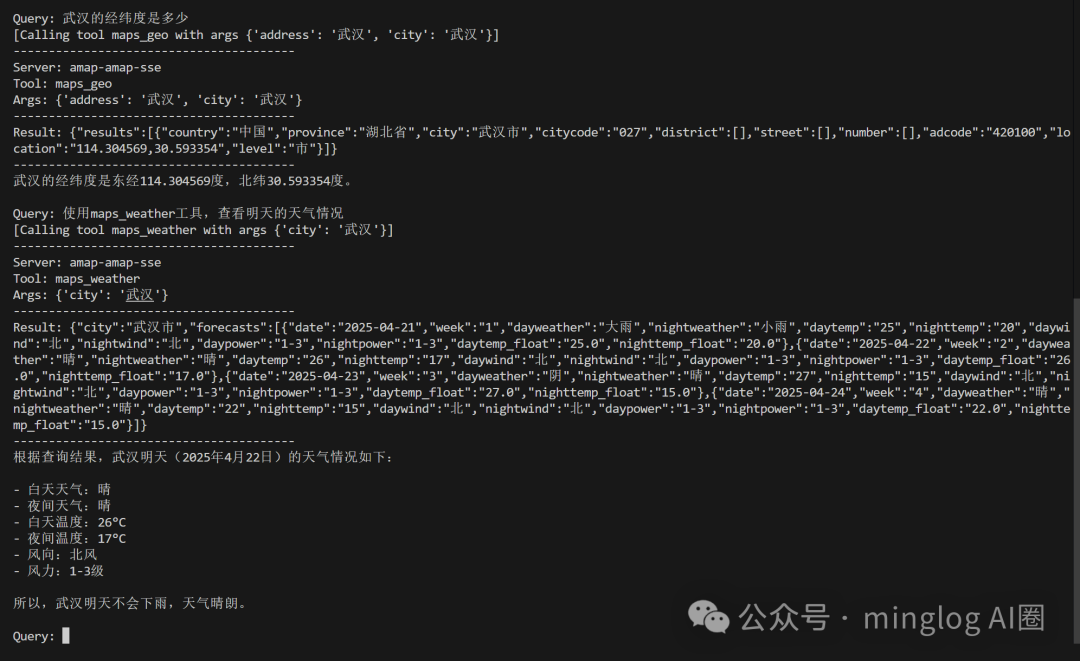
可以看到,两个工具都可以成功调用。
值得进一步优化的小建议
在本节中,我们已经实现了通过MCP配置文件,加载所有的MCP Server,并且经过验证所有的MCP Server工具都可以成功调用。
但是,现在的版本无法完成工具之前进行相互调用,无法通过用户的需求调用多个工具配置完成用户问题的解答,基于此大家可以自行修改现有代码,实现的方式不难,大家可以自己动手实操一下。
如何学习大模型 AI ?
由于新岗位的生产效率,要优于被取代岗位的生产效率,所以实际上整个社会的生产效率是提升的。
但是具体到个人,只能说是:
“最先掌握AI的人,将会比较晚掌握AI的人有竞争优势”。
这句话,放在计算机、互联网、移动互联网的开局时期,都是一样的道理。
我在一线互联网企业工作十余年里,指导过不少同行后辈。帮助很多人得到了学习和成长。
我意识到有很多经验和知识值得分享给大家,也可以通过我们的能力和经验解答大家在人工智能学习中的很多困惑,所以在工作繁忙的情况下还是坚持各种整理和分享。但苦于知识传播途径有限,很多互联网行业朋友无法获得正确的资料得到学习提升,故此将并将重要的AI大模型资料包括AI大模型入门学习思维导图、精品AI大模型学习书籍手册、视频教程、实战学习等录播视频免费分享出来。

第一阶段(10天):初阶应用
该阶段让大家对大模型 AI有一个最前沿的认识,对大模型 AI 的理解超过 95% 的人,可以在相关讨论时发表高级、不跟风、又接地气的见解,别人只会和 AI 聊天,而你能调教 AI,并能用代码将大模型和业务衔接。
- 大模型 AI 能干什么?
- 大模型是怎样获得「智能」的?
- 用好 AI 的核心心法
- 大模型应用业务架构
- 大模型应用技术架构
- 代码示例:向 GPT-3.5 灌入新知识
- 提示工程的意义和核心思想
- Prompt 典型构成
- 指令调优方法论
- 思维链和思维树
- Prompt 攻击和防范
- …
第二阶段(30天):高阶应用
该阶段我们正式进入大模型 AI 进阶实战学习,学会构造私有知识库,扩展 AI 的能力。快速开发一个完整的基于 agent 对话机器人。掌握功能最强的大模型开发框架,抓住最新的技术进展,适合 Python 和 JavaScript 程序员。
- 为什么要做 RAG
- 搭建一个简单的 ChatPDF
- 检索的基础概念
- 什么是向量表示(Embeddings)
- 向量数据库与向量检索
- 基于向量检索的 RAG
- 搭建 RAG 系统的扩展知识
- 混合检索与 RAG-Fusion 简介
- 向量模型本地部署
- …
第三阶段(30天):模型训练
恭喜你,如果学到这里,你基本可以找到一份大模型 AI相关的工作,自己也能训练 GPT 了!通过微调,训练自己的垂直大模型,能独立训练开源多模态大模型,掌握更多技术方案。
到此为止,大概2个月的时间。你已经成为了一名“AI小子”。那么你还想往下探索吗?
- 为什么要做 RAG
- 什么是模型
- 什么是模型训练
- 求解器 & 损失函数简介
- 小实验2:手写一个简单的神经网络并训练它
- 什么是训练/预训练/微调/轻量化微调
- Transformer结构简介
- 轻量化微调
- 实验数据集的构建
- …
第四阶段(20天):商业闭环
对全球大模型从性能、吞吐量、成本等方面有一定的认知,可以在云端和本地等多种环境下部署大模型,找到适合自己的项目/创业方向,做一名被 AI 武装的产品经理。
- 硬件选型
- 带你了解全球大模型
- 使用国产大模型服务
- 搭建 OpenAI 代理
- 热身:基于阿里云 PAI 部署 Stable Diffusion
- 在本地计算机运行大模型
- 大模型的私有化部署
- 基于 vLLM 部署大模型
- 案例:如何优雅地在阿里云私有部署开源大模型
- 部署一套开源 LLM 项目
- 内容安全
- 互联网信息服务算法备案
- …
学习是一个过程,只要学习就会有挑战。天道酬勤,你越努力,就会成为越优秀的自己。
如果你能在15天内完成所有的任务,那你堪称天才。然而,如果你能完成 60-70% 的内容,你就已经开始具备成为一名大模型 AI 的正确特征了。
这份完整版的大模型 AI 学习资料已经上传优快云,朋友们如果需要可以微信扫描下方优快云官方认证二维码免费领取【保证100%免费】

 2050


 扫一扫


 被折叠的 条评论
为什么被折叠?
 到【灌水乐园】发言


