A trip through the Graphics Pipeline 2011, part 3
At this point, we’ve sent draw calls down from our app all the way through various driver layers and the command processor; now, finally we’re actually going to do some graphics processing on it! In this part, I’ll look at the vertex pipeline. But before we start…
Have some Alphabet Soup!
We’re now in the 3D pipeline proper, which in turn consists of several stages, each of which does one particular job. I’m gonna give names to all the stages I’ll talk about – mostly sticking with the “official” D3D10/11 names for consistency – plus the corresponding acronyms. We’ll see all of these eventually on our grand tour, but it’ll take a while (and several more parts) until we see most of them – seriously, I made a small outline of the ground I want to cover, and this series will keep me busy for at least 2 weeks! Anyway, here goes, together with a one-sentence summary of what each stage does.
IA— Input Assembler. Reads index and vertex data.VS— Vertex shader. Gets input vertex data, writes out processed vertex data for the next stage.PA— Primitive Assembly. Reads the vertices that make up a primitive and passes them on.HS— Hull shader; accepts patch primitives, writes transformed (or not) patch control points, inputs for the domain shader, plus some extra data that drives tessellation.TS— Tessellator stage. Creates vertices and connectivity for tessellated lines or triangles.DS— Domain shader; takes shaded control points, extra data from HS and tessellated positions from TS and turns them into vertices again.GS— Geometry shader; inputs primitives, optionally with adjacency information, then outputs different primitives. Also the primary hub for…SO— Stream-out. Writes GS output (i.e. transformed primitives) to a buffer in memory.RS— Rasterizer. Rasterizes primitives.PS— Pixel shader. Gets interpolated vertex data, outputs pixel colors. Can also write to UAVs (unordered access views).OM— Output merger. Gets shaded pixels from PS, does alpha blending and writes them back to the backbuffer.CS— Compute shader. In its own pipeline all by itself. Only input is constant buffers+thread ID; can write to buffers and UAVs.
And now that that’s out of the way, here’s a list of the various data paths I’ll be talking about, in order: (I’ll leave out the IA, PA, RS and OM stages in here, since for our purposes they don’t actually do anything to the data, they just rearrange/reorder it – i.e. they’re essentially glue)
- VS→PS: Ye Olde Programmable Pipeline. In D3D9, this was all you got. Still the most important path for regular rendering by far. I’ll go through this from beginning to end then double back to the fancier paths once I’m done.
- VS→GS→PS: Geometry Shading (new with D3D10).
- VS→HS→TS→DS→PS, VS→HS→TS→DS→GS→PS: Tessellation (new in D3D11).
- VS→SO, VS→GS→SO, VS→HS→TS→DS→GS→SO: Stream-out (with and without tessellation).
- CS: Compute. New in D3D11.
And now that you know what’s coming up, let’s get started on vertex shaders!
Input Assembler stage
The very first thing that happens here is loading indices from the index buffer – if it’s an indexed batch. If not, just pretend it was an identity index buffer (0 1 2 3 4 …) and use that as index instead. If there is an index buffer, its contents are read from memory at this point – not directly though, the IA usually has a data cache to exploit locality of index/vertex buffer access. Also note that index buffer reads (in fact, all resource accesses in D3D10+) are bounds checked; if you reference elements outside the original index buffer (for example, issue a DrawIndexed with IndexCount == 6 from a 5-index buffer) all out-of-bounds reads return zero. Which (in this particular case) is completely useless, but well-defined. Similarly, you can issue a DrawIndexed with a NULL index buffer set – this behaves the same way as if you had an index buffer of size zero set, i.e. all reads are out-of-bounds and hence return zero. With D3D10+, you have to work some more to get into the realm of undefined behavior. :)
Once we have the index, we have all we need to read both per-vertex and per-instance data (the current instance ID is just another counter, fairly straightforward, at this stage anyway) from the input vertex streams. This is fairly straightforward – we have a declaration of the data layout; just read it from the cache/memory and unpack it into the float format that our shader cores want for input. However, this read isn’t done immediately; the hardware is running a cache of shaded vertices, so that if one vertex is referenced by multiple triangles (and in a fully regular closed triangle mesh, each vertex will be referenced by about 6 tris!) it doesn’t need to be shaded every time – we just reference the shaded data that’s already there!
Vertex Caching and Shading
Note: The contents of this section are, in part, guesswork. They’re based on public comments made by people “in the know” about current GPUs, but that only gives me the “what”, not the “why”, so there’s some extrapolation here. Also, I’m simply guessing some of the details here. That said, I’m not talking completely out of my ass here – I’m confident that what I’m describing here is both reasonable and works (in the general sense), I just can’t guarantee that it’s actually that way in real HW or that I didn’t miss any tricky details. :)
Anyway. For a long time (up to and including the shader model 3.0 generation of GPUs), vertex and pixel shaders were implemented with different units that had different performance trade-offs, and vertex caches were a fairly simple affair: usually just a FIFO for a small number (think one or two dozen) of vertices, with enough space for a worst-case number of output attributes, using the vertex index as a tag. As said, fairly straightforward stuff.
And then unified shaders happened. If you unify two types of shaders that used to be different, the design is necessarily going to be a compromise. So on the one hand, you have vertex shaders, which (at that time) touched maybe up to 1 million vertices a frame in normal use. On the other hand you had pixel shaders, which at 1920×1200 need to touch at least 2.3 million pixels a frame just to fill the whole screen once – and a lot more if you want to render anything interesting. So guess which of the two units ended up pulling the short straw?
Okay, so here’s the deal: instead of the vertex shader units of old that shaded more or less one vertex at a time, you now have a huge beast of a unified shader unit that’s designed for maximum throughput, not latency, and hence wants large batches of work (How large? Right now, the magic number seems to be between 16 and 64 vertices shaded in one batch).
So you need between 16-64 vertex cache misses until you can dispatch one vertex shading load, if you don’t want to shade inefficiently. But the whole FIFO thing doesn’t really play ball with this idea of batching up vertex cache misses and shading them in one go. The problem is this: if you shade a whole batch of vertices at once, that means you can only actually start assembling triangles once all those vertices have finished shading. At which point you’ve just added a whole batch (let’s just say 32 here and in the following) of vertices to the end of the FIFO, which means 32 old vertices now fell out – but each of these 32 vertices might’ve been a vertex cache hit for one of the triangles in the current batch we’re trying to assemble! Uh oh, that doesn’t work. Clearly, we can’t actually count the 32 oldest verts in the FIFO as vertex cache hits, because by the time we want to reference them they’ll be gone! Also, how big do we want to make this FIFO? If we’re shading 32 verts in a batch, it needs to be at least 32 entries large, but since we can’t use the 32 oldest entries (since we’ll be shifting them out), that means we’ll effectively start with an empty FIFO on every batch. So, make it bigger, say 64 entries? That’s pretty big. And note that every vertex cache lookup involves comparing the tag (vertex index) against all tags in the FIFO – this is fully parallel, but it also a power hog; we’re effectively implementing a fully associative cache here. Also, what do we do between dispatching a shading load of 32 vertices and receiving results – just wait? This shading will take a few hundred cycles, waiting seems like a stupid idea! Maybe have two shading loads in flight, in parallel? But now our FIFO needs to be at least 64 entries long, and we can’t count the last 64 entries as vertex cache hits, since they’ll be shifted out by the time we receive results. Also, one FIFO vs. lots of shader cores? Amdahl’s law still holds – putting one strictly serial component in a pipeline that’s otherwise completely parallel is a surefire way to make it the bottleneck.
This whole FIFO thing really doesn’t adapt well to this environment, so, well, just throw it out. Back to the drawing board. What do we actually want to do? Get a decently-sized batch of vertices to shade, and not shade vertices (much) more often than necessary.
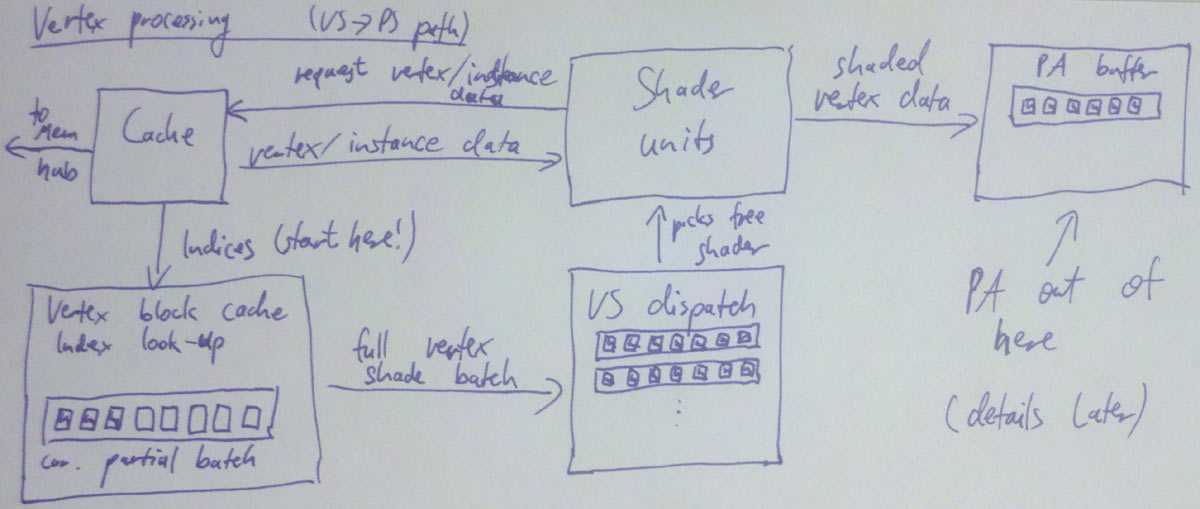
So, well, keep it simple: Reserve enough buffer space for 32 vertices (=1 batch), and similarly cache tag space for 32 entries. Start with an empty “cache”, i.e. all entries invalid. For every primitive in the index buffer, do a lookup on all the indices; if it’s a hit in the cache, fine. If it’s a miss, allocate a slot in the current batch and add the new index to the cache tag array. Once we don’t have enough space left to add a new primitive anymore, dispatch the whole batch for vertex shading, save the cache tag array (i.e. the 32 indices of the vertices we just shaded), and start setting up the next batch, again from an empty cache – ensuring that the batches are completely independent.
Each batch will keep a shader unit busy for some while (probably at least a few hundred cycles!). But that’s no problem, because we got plenty of them – just pick a different unit to execute each batch! Presto parallelism. We’ll eventually get the results back. At which point we can use the saved cache tags and the original index buffer data to assemble primitives to be sent down the pipeline (this is what “primitive assembly” does, which I’ll cover in the later part).
By the way, when I say “get the results back”, what does that mean? Where do they end up? There’s two major choices: 1. specialized buffers or 2. some general cache/scratchpad memory. It used to be 1), with a fixed organization designed around vertex data (with space for 16 float4 vectors of attributes per vertex and so on), but lately GPUs seem to be moving towards 2), i.e. “just memory”. It’s more flexible, and has the distinct advantage that you can use this memory for other shader stages, whereas things like specialized vertex caches are fairly useless for the pixel shading or compute pipeline, to give just one example.
Update: And here’s a picture of the vertex shading dataflow as described so far.
Shader Unit internals
Short versions: It’s pretty much what you’d expect from looking at disassembled HLSL compiler output (fxc /dumpbin is your friend!). Guess what, it’s just processors that are really good at running that kind of code, and the way that kind of thing is done in hardware is building something that eats something fairly close to shader bytecode, in spirit anyway. And unlike the stuff that I’ve been talking about so far, it’s fairly well documented too – if you’re interested, just check out conference presentations from AMD and NVidia or read the documentation for the CUDA/Stream SDKs.
Anyway, here’s the executive summary: fast ALU mostly built around a FMAC (Floating Multiply-ACcumulate) unit, some HW support for (at least) reciprocal, reciprocal square root, log2, exp2, sin, cos, optimized for high throughput and high density not low latency, running a high number of threads to cover said latency, fairly small number of registers per thread (since you’re running so many of them!), very good at executing straight-line code, bad at branches (especially if they’re not coherent).
All that is common to pretty much all implementations. There’s some differences, too; AMD hardware used to stick directly with the 4-wide SIMD implied by the HLSL/GLSL and shader bytecode (even though they seem to be moving away from that lately), while NVidia decided to rather turn the 4-way SIMD into scalar instructions a while back. Again though, all that’s on the Web already!
What’s interesting to note though is the differences between the various shader stages. The short version is that really are rather few of them; for example, all the arithmetic and logic instructions are exactly the same across all stages. Some constructs (like derivative instructions and interpolated attributes in pixel shaders) only exist in some stages; but mostly, the differences are just what kind (and format) of data are passed in and out.
There’s one special bit related to shaders though that’s a big enough subject to deserve a part on its own. That bit is texture sampling (and texture units). Which, it turns out, will be our topic next time! See you then.
Closing remarks
Again, I repeat my disclaimer from the “Vertex Caching and Shading” section: Part of that is conjecture on my part, so take it with a grain of salt. Or maybe a pound. I don’t know.
I’m also not going into any detail on how scratch/cache memory is managed; the buffer sizes depend (primarily) on the size of batches you process and the number of vertex output attributes you expect. Buffer sizing and management is really important for performance, but I can’t meaningfully explain it here, nor do I want to; while interesting, this stuff is very specific to whatever hardware you’re talking about, and not really very insightful.
 880


 扫一扫


 被折叠的 条评论
为什么被折叠?
 到【灌水乐园】发言