IJCV2021: Knowledge Distillation: A Survey

多目标追踪-2019综述《Deep Learning in Video Multi-Object Tracking: A Survey》 Deep Learning in Video Multi-Object Tracking: A Survey 近期开始研究多目标追踪,因此先找了一篇比较新的2019年综述性论文入门。 本论文将MOT通用算法归纳为4个步骤,并分别介绍了Deep Learning在各步骤中的应用,给出了典型论文以供读者进一步阅读学习。 文章目录1 Introduction2 MOT: algorithms, me... 阅读详情

Abstract:This paper provides a comprehensive survey of knowledge distillation from the perspectives of knowledge categories, training schemes, teacher–student architecture, distillation algorithms, performance comparison and applications. Furthermore, challenges in knowledge distillation are briefly reviewed and comments on future research are discussed and forwarded.

Section1:Introduction

模型轻量化的技术
1. 设计 efficient deep models
2. 剪枝:parameter pruning and sharing
3. 量化:Low-rank factorization
4. Transferred compact convolutional filters, 不太了解
5. 知识蒸馏
知识蒸馏的main idea:student model mimics the teacher model to obtain a competitive or even a superior performance
知识蒸馏的key problem:how to represent, and transfer knowledge from a large teacher model to a small student model.
知识蒸馏系统的三个组成部分:knowledge,distillation algorithm,teacher-student architecture

在这里插入图片描述

Section2:知识

知识蒸馏中的知识有多种类别,一种最基本的知识就是使用教师模型的预测logits;此外,教师模型中间层的特征,也可以视为表征知识来引导学生网络学习。教师网络中不同神经元,不同特征层富含的关系信息,以及教师模型的参数也包含的一定的知识。综述将知识分为三种类别:response-based knowledge,feature-based knowledge,relation-based knowledge

在这里插入图片描述

response-based knowledge:指的是教师模型的输出类别的logits

Response-based knowledge usually refers to the neural response of the last output layer of the teacher model. The main idea is to directly mimic the final prediction of the teacher model, which is simple yet effective. The idea of the response-based knowledge is straightforward and easy to understand, especially in the context of “dark knowledge”
在这里插入图片描述

最典型的response-based的方法为Hinton在2015年提出的结合Temperature的soft target方法
然而, the response-based knowledge usually relies on the output of the last layer, e.g., soft targets, and thus fails to address the intermediate-level supervision from the teacher model, which turns out to be very important for representation learning using very deep neural networks
feature-based knowledge

在这里插入图片描述

典型方法是FitNet的Hints方法:the output of a teacher’s hidden layer that supervises the student’s learning.,用教师模型的Feature map当做知识。
The main idea is to directly match the feature activations of the teacher and the student. Inspired by this, a variety of other methods have been proposed to match the features indirectly,indirect的方法有从特征图中产生attention map来表征知识,匹配特征空间的概率分布,use the activation boundary of the hidden neurons for knowledge transfer,cross-layer knowledge distillation, which adaptively assigns proper teacher layers for each student layer via attention allocation.
用于监督feature-based knowledge distillation的损失函数有:L1损失,L2损失,CE交叉熵损失,MMD损失(maximum mean discrepancy)
feature-based knowledge distillation的难点:Though feature-based knowledge transfer provides favorable information for the learning of the student model, how to effectively choose the hint layers from the teacher model and the guided layers from the student model remains to be further investigated (Romero et al. 2015). Due to the significant differences between sizes of hint and guided layers, how to properly match feature representations of teacher and student also needs to be explored.
Relation-based knowledge:further explores the relationships between different layers or data samples of teacher-student models
常见的方法有FSP矩阵(flow of solution process matrix)表示法,SVD singular value decomposition表示法,graph表示法,mutual information flow表示法,instance relationship graph表示法,
relation-based distillation loss based on relations of feature maps

在这里插入图片描述

relation-based distillation loss based on relations of instance

在这里插入图片描述
在这里插入图片描述

不同种类的relation-based knowledge

在这里插入图片描述

relations of feature maps 和 relations of instance的区别是什么????

Section 3:蒸馏的范式:offline distillation,online distillation,self-distillation

在这里插入图片描述

offline distillation:先训练好教师模型,然后冻结教师模型,再监督训练学生模型
online distillation:both the teacher model and the student model are updated simultaneously, and the whole knowledge distillation framework is end-to-end trainable
self-distillation:只有一个模型,knowledge from the deeper sections of the network is distilled into its shallow sections
Besides, offline, online and self distillation can also be intuitively understood from the perspective of human beings teacher–student learning. Offline distillation means the knowledgeable teacher teaches a student knowledge; online distillation means both teacher and student study together with each other; self-distillationmeans student learn knowledge by oneself. Moreover, just like the human beings learning, these three kinds of distillation can be combined to complement each other due to their own advantages.

Section 4:Teacher-Student Architecture

在这里插入图片描述

The complexity of deep neural networks mainly comes from two dimensions: depth and width. It is usually required to transfer knowledge from deeper and wider neural networks to shallower and thinner neural networks
The student network is usually chosen to be
1)a simplified version of a teacher network with fewer layers and fewer channels in each layer
2)a quantized version of a teacher network in which the structure of the network is preserved
3) a small network with efficient basic operations
4) a small network with optimized global network structure
5) the same network as teacher

Section 5: 蒸馏算法

1. Adversarial Distillation:Inspired by GAN, many adversarial knowledge distillation methods have been proposed to enable the teacher and student networks to have a better understanding of the true data distribution
如图所示,adversarial distillation方法可分为三种类型

在这里插入图片描述

不太懂adversarial distillation

2. Multi-Teacher Distillation:Different teacher architectures can provide their own useful knowledge for a student network
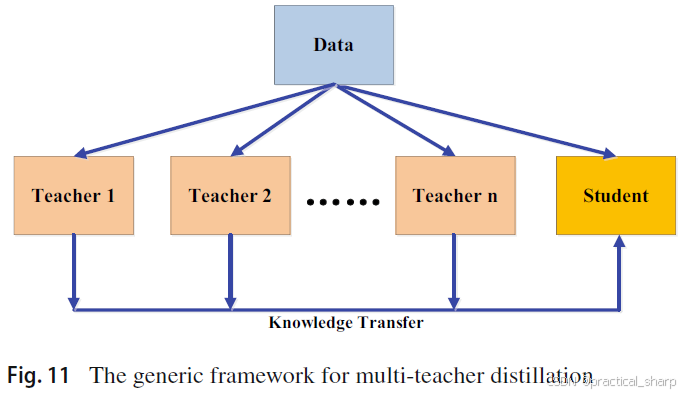
在这里插入图片描述

3. Cross-Modal Distillation

在这里插入图片描述

相关工作

[1] CVPR 2016: Cross modal distillation for supervision transfer.
[2] ECCV 2018: Modality distillation with multiple stream networks for action recognition
[3] CVPR 2018: Through-wall human pose estimation using radio signals.
[4] ICASSP 2018: Cross-modality distillation:A case for conditional generative adversarial networks
[5] CVPR 2020: Knowledge as Priors: Cross-Modal Knowledge Generalization for Datasets without Superior Knowledge
[6] ACM MM 2018: Emotion recognition in speech using cross-modal transfer in the wild
[7] ICIP 2019: Cross-modal knowledge distillation for action recognition
[8] ICLR 2020: Contrastive representation distillation
[9] ICCV 2019: Compact trilinear interaction for visual question answering
[10] ECCV 2018: Learning deep representations with probabilistic knowledge transfer.
[11] CVPR 2016: Learning with side information through modality hallucination
[12] CVPR 2019: Um-adapt: Unsupervised multi-task adaptation using adversarial cross-task distillation
[13] CVPR 2019: rdoco: Pixel-level domain transfer with cross-domain consistency
[14] BMVC 2017: Adaptingmodels to signal degradation using distillation
[15] ECCV 2018: Graph distillation for action detection with privileged modalities
[16] PR 2019: Spatiotemporal distilled denseconnectivity network for video action recognition
[17] ICASSP 2019: Multi-teacher knowledge distillation for compressed video action recognition on deep neural networks
[18] AAAI 2020: Knowledge integration networks for action recognition

在这里插入图片描述

4. Graph-based Distillation:explore the intra-data relationships using graphs. The main ideas of these graph-based distillation methods are 1) to use the graph as the carrier of teacher knowledge; or 2) to use the graph to control the message passing of the teacher knowledge. A generic framework for graph-based distillation is shown in Fig. 13在这里插入图片描述
5. Attention-based Distillation:The core of attention transfer is to define the attention maps for feature embedding in the layers of a neural network. That is to say, knowledge about feature embedding is transferred using attention map functions
6. Data-Free Distillation:no training data. Instead, the data is newly or synthetically generated.

在这里插入图片描述

7. Quantized Distillation:using the quantization process in the teacher–student framework:the full-precision teacher network is first quantized on the feature maps, and then the knowledge is transferred from the quantized teacher to a quantized student network


在这里插入图片描述

不太懂
8. Lifelong Distillation
lifelong learning, including continual learning, continuous learning and meta-learning
9. NAS-Based Distillation

Section 6: Performance Comparison

在CIFAR10和CIFAR100上提供了许多基于教师-学生模型的对比报道。具体见原文。

Section 7: Application

Section 8: Conclusion and Discussion

Challenges: 1) the quality of knowledge, 2) the types of distillation, 3) the design of the teacher-student architectures, 4) the theory behind knowledge distillation

Future Directions: 见原文

【持续学习系列(九)】《Continual Learning with Pre-Trained Models: A Survey》 这篇论文是关于预训练模型(PTM)在持续学习(CL)中的应用的全面调查。持续学习旨在使学习系统能够随着数据的演变吸收新知识,同时克服在学习新知识时对旧知识的灾难性遗忘。论文将现有的方法分为三类:基于提示的方法、基于表示的方法和基于模型混合的方法,并对它们进行了比较分析。 阅读详情

相关推荐

连续目标检测综述 Continual Object Detection: A review of definitions, strategies, and challenges

持续学习领域研究学习连续任务而不丧失先前学习的能力。其重点主要是增量分类任务。我们相信,由于连续目标检测在机器人和自动驾驶车辆中的广泛应用,其研究值得更多关注。由于出现了当时未知的类实例,但可以在后续任务中作为要学习的新类出现,导致注释缺失和与背景标签冲突,因此该场景比传统分类更复杂。在这篇综述中,我们分析了当前提出的解决类增量对象检测问题的策略。我们的主要贡献是:(1)对提出传统增量目标检测方案的方法进行了简短而系统的回顾;......

weixin_42155685的博客 2319

论文阅读《Deep Learning in Video Multi-Object Tracking: A Survey》

时间:2019年11月 作者机构:萨勒诺大学&格拉纳达大学等 链接:https://arxiv.org/abs/1907.12740 《DEEP LEARNING IN VIDEO MULTI -OBJECT TRACKING : A SURVEY》 1.Introduction mot的output 应用领域:video surveillance 、autonomou...

越努力,越幸运 3211

【知识蒸馏】知识蒸馏(Knowledge Distillation)技术详解

知识蒸馏综述

Roaddd的博客 4万+

Data-Free Network Quantization With Adversarial Knowledge Distillation

Data-Free Network Quantization With Adversarial Knowledge Distillation 1. Introduction 在本文中,我们提出了一个对抗性知识提炼框架,在无法获得原始训练数据的损失时,通过对抗性学习使最坏情况下的可能损失(最大损失)最小化。与[36]的关键区别在于,给定任何元数据,我们利用它们来约束对抗性学习框架中的发生器。为了避免额外的努力来制作新的元数据来分享,我们使用存储在批量规范化层中的统计数据来约束生成器,使其产生模仿原始训练数据的

weixin_37958272的博客 879

【论文笔记】CrossKD: Cross-Head Knowledge Distillation for Object Detection

爆裂吧,现实!粉碎吧,精神!Vanishment This World! ——《中二病也要谈恋爱!》小鸟游六花

xhyu61的博客 2187

Knowledge Distillation: A Survey

近年来,深度神经网络在工业界和学术界都取得了成功,尤其是在计算机视觉任务方面。深度学习的巨大成功主要归功于其对大规模数据进行编码和操纵数十亿模型参数的可扩展性。然而,在资源有限的设备(例如移动电话和嵌入式设备)上部署这些繁琐的深度模型是一个挑战,这不仅是因为计算复杂度高,而且还因为存储需求大。为此,已经开发了各种模型压缩和加速技术。知识蒸馏作为一种具有代表性的模型压缩和加速,可以有效地从大型教师模型中学习小型学生模型。它迅速受到社会越来越多的关注。

c_cpp_csharp的专栏 1256

Deep learning in video multi-object tracking A survey 论文笔记

qq_61363628的博客 215

【知识蒸馏+量化】(二)Data-Free Network Quantization with Adversarial Knowledge Distillation

这篇文章提出了无数据的对抗性知识蒸馏,它最小化了来自生成器的任何对抗性样本的教师和(量化)学生输出之间的最大距离;为了生成类似于原始数据的对抗性样本,作者还提出了生成的批归一化数据和教师原始数据的匹配统计数据

梁瑛平的博客 852

知识提炼:一项调查 Knowledge Distillation: A Survey

原文地址:https://link.springer.com/article/10.1007/s11263-021-01453-z?抽象近年来,深度神经网络在工业界和学术界都取得了成功,尤其是在计算机视觉任务方面。深度学习的巨大成功主要归功于其可扩展性,可以对大规模数据进行编码并操纵数十亿个模型参数。然而,在资源有限的设备(例如手机和嵌入式设备)上部署这些繁琐的深度模型是一项挑战,这不仅是因为计算复杂度高,而且存储需求很大。为此,已经开发了各种模型压缩和加速技术。

VS2021的专栏 740

Mit6.S081-实验1-Xv6 and Unix utilities

Mit6.S081-实验1-Xv6 and Unix utilities前言一、Boot xv61,实验目的2,操作流程1)切换到xv6-labs-2020代码库的lab1分支2)启动xv63)测试xv64)过程分析5)其他操作二、在xv6中添加一个自己编写的程序1,源码准备2,编译配置3,测试添加程序4,过程分析三、xv6中shell简析 前言 一、Boot xv6 1,实验目的 利用qemu启动xv6 2,操作流程 1)切换到xv6-labs-2020代码库的lab1分支 git checkout ut

code a better life~ 36万+

如何用Megatron-LM搭建多卡集群?手把手教你配置分布式训练环境

本文提供了一份详细的Megatron-LM多卡集群搭建实战指南。从硬件兼容性检查、软件栈版本对齐,到分布式并行策略(数据并行、张量并行、流水线并行)的配置与多节点启动脚本编写,手把手教你配置稳定高效的分布式训练环境,并分享了关键的排错与性能调优经验。

yellow的专栏 416

Knowledge Distillation A Survey - 知识蒸馏综述

2020IJCV - Knowledge Distillation A Survey -arXiv2006.05525 文章目录2020IJCV - Knowledge Distillation A Survey -arXiv2006.05525模型压缩常见方法知识蒸馏主要思想本文贡献知识 Knowledge蒸馏方案 Distillation Schemes师生架构 Teacher-Student Architecture蒸馏算法 Distillation Algorithms性能比较应用结论和讨论 @ar

qq_41982726的博客 1374

君正T31x metartc集成测试

metartc为国内杨大侠部分开源的一款用于嵌入式领域webrtc库,它与谷歌官方webrtc相比,编译到君正平台的可执行文件仅有5M即可实现webrtc的通信。1. 目前实现的是基于开源版v5.0-b0版本做的简单修改,官方的好几个版本都多少缺点东西,我这里给整理了一下。目前是局域网连接的webrtc,后续尝试走stun和turn试一下NAT穿越的效果。

fsmpeg的博客 3161

论文阅读 - FedACK: Federated Adversarial Contrastive Knowledge Distillation for Cross-Lingual

社交机器人检测对于在线社交平台的弹性和安全性至关重要。最先进的检测模型是孤立的,在很大程度上忽略了来自多个跨语言平台的各种数据特征。同时,数据分布和模型结构的异构性使得设计一个有效的跨平台和跨模型检测框架变得非常复杂。在本文中,我们提出了一个新的联邦对抗性对比知识提取框架 FedACK,用于社交机器人检测。我们设计了一种基于 GAN 的联邦知识蒸馏机制,用于在客户端之间有效地传输数据分布的知识。特别是,全局生成器用于提取全局数据分布的知识,并将其提炼到每个客户端的本地模型中。

qq_40671063的博客 807

Jmeter压测报告

账户分析压测报告 一、测试内容 本次测试是针对账户分析进行的压力测试,在账户分析查询接口中,只对用户资产查询接口进行压力测试,其中不包含用户签名校验功能。 二、测试方法 本次采用apache的开源测试工具jmeter,采用本地动态拼装请求数据并通过http协议GET方式发送每日盈亏查询请求。并采用1000个用户账号测试访问情况。...

qq_31108731的博客 6629

Lama:基于傅立叶卷积的分辨率鲁棒性大掩模修复

为了缓解修复网络和损失函数都缺乏有效的感受野这个问题,提出了大掩模修复(LaMa)。LaMa基于一种新的修复网络架构,该架构使用快速傅立叶卷积(FFC),具有图像范围的感受野;高感受野感知损失;大型训练掩码,释放前两个组件的潜力。

qq_44926214的博客 1420

Knowledge Distillation论文阅读之:综述文章:Knowledge Distillation: A Survey(未完待续····)

只挑重点的说,不是翻译论文 文章目录Abstract1. Introduction2. Background3. Knowledge3.1 Response-base Knowledge3.2 Feature-Based Knowledge3.3 Relation-Based Knowledge Abstract 本问提供了 KD 的复杂研究包括了下述方面: KD 的种类 训练方案 teacher-student 结构 蒸馏算法 表现对比和实际应用 在此基础上,简要回顾了知识蒸馏面临的挑战,并对未来的研

qq_42902997的博客 5446

Windows下快速搭建MSYS2开发环境(含GCC与MinGW配置)

本文详细介绍了在Windows系统下快速搭建MSYS2开发环境的完整流程。通过使用pacman包管理器,可以便捷地安装GCC编译器与MinGW-w64工具链,并配置系统环境变量。文章还涵盖了从基础安装、系统更新到编译开源项目的实战指南,帮助开发者高效构建原生Windows程序,显著提升C/C++开发效率。

weixin_29213827的博客 542

第05篇:对抗蒸馏(Adversarial Knowledge Distillation)——让学生“骗过”判别器的秘密

知识蒸馏(Knowledge Distillation, KD)中,学生模型模仿教师模型的输出,学习其“行为”或“特征”。传统 KD 偏重于逐点对齐,比如 Soft Target KD 通过 KL 散度对齐 soft logits,而 Feature-based KD 则是直接对齐中间特征。但这些方式对“整体分布”理解有限。如果把教师当作一个“真实样本的生成器”,那么我们能否训练一个“判别器”来判断学生输出是否“足够像老师”?这正是。

m0_45101613的博客 2235

数据科学中的异常检测:算法与应用场景

异常检测(Anomaly Detection)是数据科学中识别数据集中异常或罕见项目的技术,这些异常项目与大多数数据显著不同。系统介绍异常检测的核心概念和技术详细解析主流异常检测算法原理提供可操作的Python实现示例探讨实际应用场景和最佳实践分析未来发展趋势和挑战本文涵盖从基础统计方法到深度学习技术的完整异常检测技术栈,适用于结构化数据和非结构化数据的异常检测场景。背景介绍:定义异常检测及其重要性核心概念:异常检测的分类和技术路线算法原理:详细解析主流算法。

AI云原生与云计算技术学院 897

[VT虚拟化驱动]利用EPT实现无痕HOOK

本章利用讲EPT无痕HOOK

吾无法无天的博客 1万+

CrossKD 原理与代码解析

在预测模拟中,学生模型的预测需要同时模拟GT和教师模型的预测,但是教师模型的预测常常会和GT有很大的差异,学生模型在蒸馏过程中经历了一个矛盾的学习过程,作者认为这是阻碍预测模型获得更高性能的主要原因。 为了缓解学习目标冲突的问题,本文提出了一种新的蒸馏方法CrossKD,将学生检测头的中间特征送入教师的检测头,得到的预测结果与教师的原始预测结果进行蒸馏,这种方法有两个好处,首先KD损失不影响学生检测头的权重更新,避免了原始检测损失和KD损失的冲突。此外由于交叉头的预测和教师的预测共享了部分教师的检测头,两

00000cj的博客 1775

计算机控制技术及应用

《计算机控制技术及应用》通过总结作者的科研成果和吸收国内外的先进理论、方法和技术,以计算机控制系统的网络化、开放化、智能化和集成化发展趋势为主线索,主要介绍计算机控制系统的基本概念和计算机控制系统的典型形式,计算机控制系统的数学描述与基本分析方法,以及数字PID控制器、最少拍控制系统、达林算法、状态变量设计法等设计方法及其各种改进算法。重点突出计算机控制系统输入输出通道接口的设计方法和典型控制系统的设计案例与实现方法等。

知识蒸馏(Knowledge Distillation)

知识蒸馏(Knowledge Distillation) 从大型、深层的教师网络中提炼知识并转移到小型、简单的学生网络中 更深更广→更浅更薄 [外链图片转存失败,源站可能有防盗链机制,建议将图片保存下来直接上传(img-LtOe5CiH-1631343439036)(F:\Blog\image\知识蒸馏1.PNG)] 知识(Knowledge) [外链图片转存失败,源站可能有防盗链机制,建议将图片保存下来直接上传(img-mQBacMmn-1631343439039)(F:\Blog\image\知识蒸馏2

weixin_44125346的博客 3581

Devexpress16.2.6破解工具

Devexpress16.2.6破解工具Devexpress16.2.6破解工具Devexpress16.2.6破解工具Devexpress16.2.6破解工具

贝叶斯统计 [韦来生编]

贝叶斯(Bayes)统计是近几十年来迅速发展起来的数理统计的一个重要分支。贝叶斯方法与经典统计方法的主要不同之处是进行统计推断时除了利用样本信息外,还要利用参数的先验信息,因此可以提高统计推断或统计决策的效果。它在经济、金融、生物、医学、自然科学和社会科学等许多领域具有广泛的应用。贝叶斯方法的研究已渗透到了统计学的几乎所有领域。作者在给中国科学技术大学概率论与数理统计专业本科生开设的“数理统计”课程中有一章专门讲授“贝叶斯方法和统计决策理论”,近十年来也给中国科学技术大学概率统计专业研究生开设过几次“贝叶斯分析”课。本书是在对过去讲稿的内容作了适当的增减和调整的基础上完成的。  本书共分六章。第1章是绪论,介绍了贝叶斯统计的若干基本概念,同时对必要的数理统计的基础知识有重点地作了回顾。第二章介绍了确定先验分布的若干可供选择的方法。第三章介绍了几类常见统计模型参数的后验分布的主要结果和计算方法。第四章和第五章分别介绍了“贝叶斯统计推断”和“贝叶斯统计决策”的内容。第六章介绍了贝叶斯统计计算的若干方法,包括蒙特卡洛方法和马尔可夫链蒙特卡洛(MCMC)方法以及相关统计软件的简介。本书的每一章附右大量的例题和习题,书末附有常用的几个表格和部分习题解答供读者查用。  大约可在54学时内讲授本书的第1章至第六章的主要内容,教师可根据学时需要选讲本书第1章至第六章的部分内容。书中标“*”号的章节可略去不讲,留给读者作为阅读材料。第六章例题中的R代码和部分例题的数据文件等可从作者个人主页下载。  作者在编写本书的过程中参考了J.O.Berger教授的《统计决策论及贝叶斯分析》和茆诗松教授编写的《贝叶斯统计》等书中的一些内容,以及《贝叶斯分析》一书中由张伟平博士编写的有关贝叶斯统计计算的一些内容。在此表示衷心感谢。  本书编写准备过程中,中国科学技术大学统计与金融系的几个研究生帮助完成了本书部分中文的录入和排版,作者对他们的辛勤工作表示真诚的感谢。高等教育出版社为本书的出版给予了大力支持。在此一并致谢。

【论文笔记_知识蒸馏_2022】Compressing Deep Graph Neural Networks via Adversarial Knowledge Distillation

通过对立知识蒸馏压缩深度图神经网络 深度图神经网络(GNNs)已被证明对图结构数据的建模具有表达能力。然而,深度图模型的过度堆积的体系结构使得在移动或嵌入式系统上部署和快速测试变得困难。为了压缩过度堆积的广义神经网络,通过师生架构进行知识提炼是一种有效的技术,其中关键步骤是用预定义的距离函数来度量教师和学生网络之间的差异。然而,对各种结构的图使用相同的距离可能是不合适的,并且最佳距离公式很难确定。为了解决这些问题,我们提出了一个新的图模型的对抗性知识蒸馏框架GraphAKD,它对抗性地训练一个鉴别器和一个生

qq_45128278的博客 884

迈瑞BS系列全自动生化分析仪LIS协议接口手册(内含HL7和ASTM)

迈瑞BS系列全自动生化分析仪LIS协议接口手册,内含HL7和ASTM)

悉尼大学 & 伦敦大学联合出品:知识蒸馏最新综述

©作者 | 夏劲松学校 | 哈尔滨理工大学研究方向 | 知识蒸馏、图神经网络摘要深度学习通过参数量巨大的模型,近几年中在多个领域取得了较好的效果,但是往往因为模型体积过大(模型的体积指的就...

Paper weekly 1140

Compressing Deep Graph Neural Networks via Adversarial Knowledge Distillation

为了压缩过度堆叠的gnn,基于师生架构的知识蒸馏是一种有效的技术,其中关键步骤是通过预定义的距离函数来测量教师和学生网络之间的差异。为解决这些问题,本文提出一种新的图模型对抗知识蒸馏框架GraphAKD,对抗性地训练一个鉴别器和一个生成器,以自适应地检测和减少差异。充分捕获的节点间和类间相关性有利于深度gnn的成功,本文建议用可训练的判别器来批评节点级和类级视图的继承知识。鉴别器区分老师的知识和学生继承的知识,而学生GNN作为生成器,旨在欺骗鉴别器。

小蚂蚁与大象 429
上一篇: 基于Pytorch的MINIST数据集soft target的知识蒸馏代码实验
下一篇: 基于Pytorch的CIFAR100数据集上从ResNet50到VGG16的知识蒸馏实验记录
practical_sharp
博客等级 码龄8年 500粉丝 148原创
评论
成就一亿技术人!
拼手气红包6.0元
还能输入1000个字符
 
 条评论被折叠 查看
添加红包

请填写红包祝福语或标题

个

红包个数最小为10个

元

红包金额最低5元

当前余额3.43元 前往充值 >
需支付:10.00元
成就一亿技术人!
领取后你会自动成为博主和红包主的粉丝 规则
hope_wisdom
发出的红包
实付元
使用余额支付
点击重新获取
扫码支付
钱包余额 0

抵扣说明:

1.余额是钱包充值的虚拟货币,按照1:1的比例进行支付金额的抵扣。
2.余额无法直接购买下载,可以购买VIP、付费专栏及课程。

余额充值