codeforces807div2 D.Dynamic Problem Scoring[暴力][贪心]

COLMAP在Ubuntu下的编译陷阱与实战避坑指南——从环境配置到三维重建全流程 本文详细介绍了在Ubuntu系统下编译和配置COLMAP三维重建工具的全流程,包括环境准备、依赖库安装、CUDA加速配置以及常见编译问题的解决方案。通过实战案例演示了从图像特征提取到稠密重建的完整步骤,并提供了性能优化和问题排查的实用技巧,帮助用户高效完成三维重建任务。 阅读详情

D. Dynamic Problem Scoring
time limit per test
2 seconds
memory limit per test
256 megabytes
input
standard input
output
standard output

Vasya and Petya take part in a Codeforces round. The round lasts for two hours and contains five problems.

For this round the dynamic problem scoring is used. If you were lucky not to participate in any Codeforces round with dynamic problem scoring, here is what it means. The maximum point value of the problem depends on the ratio of the number of participants who solved the problem to the total number of round participants. Everyone who made at least one submission is considered to be participating in the round.
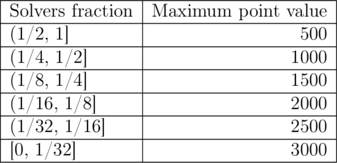
Pay attention to the range bounds. For example, if 40 people are taking part in the round, and 10 of them solve a particular problem, then the solvers fraction is equal to 1 / 4, and the problem's maximum point value is equal to 1500.

If the problem's maximum point value is equal to x, then for each whole minute passed from the beginning of the contest to the moment of the participant's correct submission, the participant loses x / 250 points. For example, if the problem's maximum point value is 2000, and the participant submits a correct solution to it 40 minutes into the round, this participant will be awarded with 2000·(1 - 40 / 250) = 1680points for this problem.

There are n participants in the round, including Vasya and Petya. For each participant and each problem, the number of minutes which passed between the beginning of the contest and the submission of this participant to this problem is known. It's also possible that this participant made no submissions to this problem.

With two seconds until the end of the round, all participants' submissions have passed pretests, and not a single hack attempt has been made. Vasya believes that no more submissions or hack attempts will be made in the remaining two seconds, and every submission will pass the system testing.

Unfortunately, Vasya is a cheater. He has registered 109 + 7 new accounts for the round. Now Vasya can submit any of his solutions from these new accounts in order to change the maximum point values of the problems. Vasya can also submit any wrong solutions to any problems. Note that Vasya can not submit correct solutions to the problems he hasn't solved.

Vasya seeks to score strictly more points than Petya in the current round. Vasya has already prepared the scripts which allow to obfuscate his solutions and submit them into the system from any of the new accounts in just fractions of seconds. However, Vasya doesn't want to make his cheating too obvious, so he wants to achieve his goal while making submissions from the smallest possible number of new accounts.

Find the smallest number of new accounts Vasya needs in order to beat Petya (provided that Vasya's assumptions are correct), or report that Vasya can't achieve his goal.

Input

The first line contains a single integer n (2 ≤ n ≤ 120) — the number of round participants, including Vasya and Petya.

Each of the next n lines contains five integers ai, 1, ai, 2..., ai, 5 ( - 1 ≤ ai, j ≤ 119) — the number of minutes passed between the beginning of the round and the submission of problem j by participant i, or -1 if participant i hasn't solved problem j.

It is guaranteed that each participant has made at least one successful submission.

Vasya is listed as participant number 1, Petya is listed as participant number 2, all the other participants are listed in no particular order.

Output

Output a single integer — the number of new accounts Vasya needs to beat Petya, or -1 if Vasya can't achieve his goal.

Examples
input
2
5 15 40 70 115
50 45 40 30 15
output
2
input
3
55 80 10 -1 -1
15 -1 79 60 -1
42 -1 13 -1 -1
output
3
input
5
119 119 119 119 119
0 0 0 0 -1
20 65 12 73 77
78 112 22 23 11
1 78 60 111 62
output
27
input
4
-1 20 40 77 119
30 10 73 50 107
21 29 -1 64 98
117 65 -1 -1 -1
output
-1
Note

In the first example, Vasya's optimal strategy is to submit the solutions to the last three problems from two new accounts. In this case the first two problems will have the maximum point value of 1000, while the last three problems will have the maximum point value of 500. Vasya's score will be equal to 980 + 940 + 420 + 360 + 270 = 2970 points, while Petya will score just 800 + 820 + 420 + 440 + 470 = 2950 points.

In the second example, Vasya has to make a single unsuccessful submission to any problem from two new accounts, and a single successful submission to the first problem from the third new account. In this case, the maximum point values of the problems will be equal to 500, 1500, 1000, 1500, 3000. Vasya will score 2370 points, while Petya will score just 2294 points.

In the third example, Vasya can achieve his goal by submitting the solutions to the first four problems from 27 new accounts. The maximum point values of the problems will be equal to 500, 500, 500, 500, 2000. Thanks to the high cost of the fifth problem, Vasya will manage to beat Petya who solved the first four problems very quickly, but couldn't solve the fifth one.


题意:两个好朋友参加一场动态计分的比赛,根据比赛要求,每个题的分数与题的正确比率有关,每个人的每个题得分与作出题的时间和题目分数有关。为了让A战胜B,A开了很多小号来提交正确或错误,问最少的提交次数能战胜B。

思路:

一共初始状态最多120人参赛,所以为了让一个题的分数限定在500分或者3000分, 只需要大约3000个小号,所以五个题最多需要上万个小号吧,再多了也没有什么作用,所以对使用小号的个数进行暴力即可,针对每个小号如何提交才能达到最优状态,采用贪心的方式:

如果A没有做出来这题,所有小号一定无法正确提交。

如果A做出来了这题,但是B没有做出来,为了使此题分数最大,A的小号都提交错误答案。

如果A做出来了这题,B也做出来了,但是A比B做的快,次情况同上。

如果A做出来了,但B做的比A快,为了使此题分数最小,A的小号都正确提交。

按照以上贪心方式提交,即可判断当前小号个数下五个题的分数谁高,是否满足条件。

(比较坑的一点代码中计算 *(1-x/250)这里精度出错了)

#include<bits/stdc++.h>
using namespace std;
int a[150][150];
int cnt[10];
int n;
int getscore(int id, bool flag, int s)
{
    if(a[flag][id]==-1) return 0;
    int sum;
    if(a[0][id] == -1 || a[1][id] == -1 || a[0][id]<a[1][id]) sum = cnt[id];
    else sum = cnt[id]+s;

    int score = 500;
    for(int i = 2; i <= 32; i*=2)
    {
        if(sum*i > n+s)
            break;
        else score += 500;
    }

    return score*(250.0 - a[flag][id])/250.0;
}


int main()
{
    ios::sync_with_stdio(false);
    cin >> n;
    for(int i = 0; i < n; ++i)
        for(int j = 0; j < 5; ++j)
    {
        cin >> a[i][j];
        if(a[i][j] != -1)
            cnt[j]++;
    }
    //cout << getscore(4, 0, 2);
    for(int i = 0; i < 50000; ++i)
    {
        int a1=0, a2=0;
        for(int j = 0; j < 5; ++j)
            a1 += getscore(j, 0, i);
        for(int j = 0; j < 5; ++j)
            a2 += getscore(j, 1, i);
        //cout << a1 <<" " <<  a2 << endl;
        if(a1 > a2)
        {
            cout << i << endl;
            return 0;
        }
    }
    cout << "-1" <<endl;
    return 0;
}



多模态大模型助力AI人工智能领域的智能决策 我们的目的是深入了解多模态大模型是怎样在AI人工智能领域帮助做出智能决策的。范围涵盖了多模态大模型的基本概念、工作原理、在不同场景下的应用,以及未来的发展方向等。接下来,我们会先介绍多模态大模型和智能决策的核心概念,再讲讲它们之间的关系。然后说说多模态大模型在智能决策中的算法原理和操作步骤,用数学公式来解释一下。接着通过一个项目实战案例让大家更直观地感受。之后看看多模态大模型在实际中的应用场景,推荐一些学习的工具和资源。最后探讨未来的发展趋势和挑战,进行总结并提出一些思考题。多模态大模型。 阅读详情

相关推荐

Ubuntu 20.04 上 Geant4 安装避坑全记录:从源码编译到 B1 示例跑通(含数据包加速下载)

本文详细记录了在Ubuntu 20.04系统上从源码编译安装Geant4的全过程,包括环境准备、依赖安装、CMake参数解析、多线程编译优化以及数据包加速下载等关键步骤。特别针对B1示例的测试与验证提供了完整流程,帮助科研人员和学生避开常见安装陷阱,提升粒子物理模拟效率。

weixin_31220401的博客 312

AC日记——Dynamic Problem Scoring codeforces 807d

Dynamic Problem Scoring 思路:   水题; 代码: #include <cstdio> #include <cstring> #include <iostream> #include <algorithm> using namespace std; #define maxn 130 ...

weixin_34220834的博客 133

【入门篇】第五章 第一次与 AI Agent 交互

本文介绍了OpenClaw中最基本的用户与AI Agent交互方式,剖析了Agent和Gateway两个核心组件的作用,通过简单示例展示了从用户请求到结果返回的完整执行流程,说明了最小交互过程对验证系统可用性的重要意义,为后续学习复杂任务执行机制奠定基础。

lanyv的博客 512

codeforces 412 D Dynamic Problem Scoring

题意:两个人比赛,得分规则如下:           每个题目的分值如下,                      其中的分数代表,解决这道题目的人数占总比赛人数的比例;           每个人可以得的分数如下: 题目分值*(1-此人解决这道题目所用时间/250); 在比赛的所有的人当中有两个人,其中一个人的编号为0,名字为Vasya,另一个编号为1 ,名字为Petya,现在

Ma_tx 339

SBM与超效率SBM模型实战:从原始面板数据到MATLAB高效实现

本文详细介绍了SBM模型与超效率SBM模型的核心原理,并提供了从原始面板数据预处理到MATLAB高效实现的完整实战指南。通过具体代码解析,帮助研究者掌握如何利用MATLAB进行数据标准化、模型构建、效率求解及结果可视化,从而精准评估决策单元的相对效率,尤其适用于在高效单元中进一步精细排名的场景。

weixin_29100399的博客 477

提示词注入攻击全面解析与防御策略

提示词注入(Prompt Injection)是指攻击者通过精心构造的输入内容,操纵或欺骗AI系统执行非预期行为的技术手段。这种攻击类似于传统的SQL注入或XSS攻击,但其目标是AI模型的提示词处理机制而非数据库或网页。提示词注入利用了大语言模型的一个基本特性:它们被设计为遵循指令。攻击者通过在用户输入中嵌入特定指令,试图覆盖或绕过系统原有的安全限制和行为规则,让模型执行本不应该执行的操作。深度防御:实施多层次防御策略,不依赖单一安全措施持续更新:随着攻击技术的发展不断更新防御措施安全设计优先。

免责声明:本资料部分整理自合法网络公开渠道,部分为个人学习积累成果,仅作学习参考、学术交流使用。所收费用仅为资料搜集整理的时间劳务酬劳。版权归原作者及出版方所有,本人不承担相关版权及内容法律责任,若有侵权请告知,即刻删除处理。 4206

codeforces807div2 C.Success Rate[二分][数学]

C. Success Rate time limit per test 2 seconds memory limit per test 256 megabytes input standard input output standard output You are an experienced Codeforces user. Tod

Qer的博客 590

PPT高清导出秘籍:如何轻松设置600dpi图片分辨率

本文详细解析了PPT导出图片模糊的根本原因,并提供了通过修改Windows注册表将导出分辨率从默认的96dpi提升至600dpi的完整教程。该方法能显著提升图片清晰度,满足学术出版与高质量印刷需求,文中还包含效果对比、进阶设置及常见问题解答。

a0b1c2d3的专栏 1312

codeforces D. Dynamic Problem Scoring

题意: 给出n个人5道题的codeforces提交时间,现在第一个人想要自己的成绩总和大于第二 个人,怎么强行提高自己成绩呢?他会开小号去提交某一些题目,而一道题的 Accepted之后的成绩是根据比例计算的,Accepted / 总提交。比例越小成绩越高 如题中的表。他可以在自己能力范围内控制题目的比例。求出,他需要多少个小号 去达到目的。 思路: 对于第一个人,如

Since_natural_ran 471

【ComfyUI专栏】ComfyUI 常用工作流下载与分享网址

首先我们来分享第一个网站,Openart 网站,这个网站同时也能提供比较多的其他类型。但是如果希望下载工作流,我们可以访问到如下的这个站点。作为ComfyUI的学习用户来说,我们通常需要借助他山之石来帮助我们快速成长,因此我们需要找到能够分享和下载的网址。,当前网站是综合性网站,在网站中可以下载各种不同的类型,其中工作流只是可以下载的非常小的部分。这个网站也可以浏览不同的工作流,这个工作流的地址和访问如下的站点。

技术与管理的平衡木- 7778

Apollo EM Planner中路径-速度解耦优化的数学建模与仿真分析

摘要 Apollo EM Planner采用路径-速度解耦优化策略解决自动驾驶运动规划问题。该算法将时空轨迹规划分解为路径规划和速度规划两个子问题:首先在静态环境下生成几何最优路径,再优化沿路径的速度曲线。通过五次多项式表示路径和速度,构建包含平滑性、安全性、舒适性的多目标优化函数,并引入弹性模型处理动态障碍物约束。算法具有解耦优化、弹性适应、实时求解等特点,适用于高速公路、城市交叉口等多种场景。数学建模包括路径几何优化、速度动态优化和弹性势能函数,最终生成满足车辆动力学和环境约束的安全轨迹。

走向CTO的路上... 932

codeforces 807 D. Dynamic Problem Scoring(贪心+思维)

题目链接:http://codeforces.com/contest/807/problem/D 题意:对于动态计分的 Codeforces Round ,已知每题的 score 是根据 Round 参加人数和该题过题人数计算,两者之比结合上图得出该题的分数。某人在该题的得分为score*(1−t/250)其中 t 表示通过该题的时间。 已知参加该场比赛的所有参加者的过题情况(包...

awow80285的博客 192

STM32F401RCT6最小系统原理图设计

STM32F401RCT6最小系统原理图设计一、主控芯片二、电源电路三、晶振电路三、下载电路四、完整电路图      本文章基于STM32F401RCT6进行最小系统原理图设计,包含主控芯片,电源,晶振电路,下载电路等几部分 一、主控芯片 主控芯片采用STM32F401RCT6,需注意: VBAT在不接电池的情况下需接3.3V,VDDAVREF+需接3.3V,否则会造成芯片供电不正常,无法启动和识别的情况 VDDAVREF+和VCAP1处电容需按照规格书

weixin_43278295的博客 2万+

Codeforces Round #412 (rated, Div. 2, base on VK Cup 2017 Round 3) D. Dynamic Problem Scoring 贪心

&#13; 链接:&#13; http://codeforces.com/contest/807/problem/D&#13; 题意:&#13; 一场比赛一共5道题,有n个参赛者,现在只关心前两个,要使第一个人最后得分比第二个人高&#13; 每道题的总分数和通过这道题的人数与总人数的比值有关,如下表&#13; &#13; 现在给出每个人的每道题的通过时间,如果没有通过,时间为...

花海 126

深度学习工具包 DeepLearningToolbox

深度学习工具包Deprecation notice.-----This toolbox is outdated and no longer maintained.There are much better tools available for deep learning than this toolbox, e.g. [Theano](http://deeplearning.net/software/theano/), [torch](http://torch.ch/) or [tensorflow](http://www.tensorflow.org/)I would suggest you use one of the tools mentioned above rather than use this toolbox.Best, Rasmus.DeepLearnToolbox================A Matlab toolbox for Deep Learning.Deep Learning is a new subfield of machine learning that focuses on learning deep hierarchical models of data.It is inspired by the human brain's apparent deep (layered, hierarchical) architecture.A good overview of the theory of Deep Learning theory is[Learning Deep Architectures for AI](http://www.iro.umontreal.ca/~bengioy/papers/ftml_book.pdf)For a more informal introduction, see the following videos by Geoffrey Hinton and Andrew Ng.* [The Next Generation of Neural Networks](http://www.youtube.com/watch?v=AyzOUbkUf3M) (Hinton, 2007)* [Recent Developments in Deep Learning](http://www.youtube.com/watch?v=VdIURAu1-aU) (Hinton, 2010)* [Unsupervised Feature Learning and Deep Learning](http://www.youtube.com/watch?v=ZmNOAtZIgIk) (Ng, 2011)If you use this toolbox in your research please cite [Prediction as a candidate for learning deep hierarchical models of data](http://www2.imm.dtu.dk/pubdb/views/publication_details.php?id=6284)```@MASTERSTHESIS\{IMM2012-06284, author = "R. B. Palm", title = "Prediction as a candidate for learning deep hierarchical models of data", year = "2012",}```Contact: rasmusbergpalm at gmail dot comDirectories included in the toolbox-----------------------------------`NN/` - A library for Feedforward Backpropagation Neural Networks`CNN/` - A library for Convolutional Neural Networks`DBN/` - A library for Deep Belief Networks`SAE/` - A library for Stacked Auto-Encoders`CAE/` - A library for Convolutional Auto-Encoders`util/` - Utility functions used by the libraries`data/` - Data used by the examples`tests/` - unit tests to verify toolbox is workingFor references on each library check REFS.mdSetup-----1. Download.2. addpath(genpath('DeepLearnToolbox'));Example: Deep Belief Network---------------------```matlabfunction test_example_DBNload mnist_uint8;train_x = double(train_x) / 255;test_x = double(test_x) / 255;train_y = double(train_y);test_y = double(test_y);%% ex1 train a 100 hidden unit RBM and visualize its weightsrand('state',0)dbn.sizes = [100];opts.numepochs = 1;opts.batchsize = 100;opts.momentum = 0;opts.alpha = 1;dbn = dbnsetup(dbn, train_x, opts);dbn = dbntrain(dbn, train_x, opts);figure; visualize(dbn.rbm{1}.W'); % Visualize the RBM weights%% ex2 train a 100-100 hidden unit DBN and use its weights to initialize a NNrand('state',0)%train dbndbn.sizes = [100 100];opts.numepochs = 1;opts.batchsize = 100;opts.momentum = 0;opts.alpha = 1;dbn = dbnsetup(dbn, train_x, opts);dbn = dbntrain(dbn, train_x, opts);%unfold dbn to nnnn = dbnunfoldtonn(dbn, 10);nn.activation_function = 'sigm';%train nnopts.numepochs = 1;opts.batchsize = 100;nn = nntrain(nn, train_x, train_y, opts);[er, bad] = nntest(nn, test_x, test_y);assert(er < 0.10, 'Too big error');```Example: Stacked Auto-Encoders---------------------```matlabfunction test_example_SAEload mnist_uint8;train_x = double(train_x)/255;test_x = double(test_x)/255;train_y = double(train_y);test_y = double(test_y);%% ex1 train a 100 hidden unit SDAE and use it to initialize a FFNN% Setup and train a stacked denoising autoencoder (SDAE)rand('state',0)sae = saesetup([784 100]);sae.ae{1}.activation_function = 'sigm';sae.ae{1}.learningRate = 1;sae.ae{1}.inputZeroMaskedFraction = 0.5;opts.numepochs = 1;opts.batchsize = 100;sae = saetrain(sae, train_x, opts);visualize(sae.ae{1}.W{1}(:,2:end)')% Use the SDAE to initialize a FFNNnn = nnsetup([784 100 10]);nn.activation_function = 'sigm';nn.learningRate = 1;nn.W{1} = sae.ae{1}.W{1};% Train the FFNNopts.numepochs = 1;opts.batchsize = 100;nn = nntrain(nn, train_x, train_y, opts);[er, bad] = nntest(nn, test_x, test_y);assert(er < 0.16, 'Too big error');```Example: Convolutional Neural Nets---------------------```matlabfunction test_example_CNNload mnist_uint8;train_x = double(reshape(train_x',28,28,60000))/255;test_x = double(reshape(test_x',28,28,10000))/255;train_y = double(train_y');test_y = double(test_y');%% ex1 Train a 6c-2s-12c-2s Convolutional neural network %will run 1 epoch in about 200 second and get around 11% error. %With 100 epochs you'll get around 1.2% errorrand('state',0)cnn.layers = { struct('type', 'i') %input layer struct('type', 'c', 'outputmaps', 6, 'kernelsize', 5) %convolution layer struct('type', 's', 'scale', 2) %sub sampling layer struct('type', 'c', 'outputmaps', 12, 'kernelsize', 5) %convolution layer struct('type', 's', 'scale', 2) %subsampling layer};cnn = cnnsetup(cnn, train_x, train_y);opts.alpha = 1;opts.batchsize = 50;opts.numepochs = 1;cnn = cnntrain(cnn, train_x, train_y, opts);[er, bad] = cnntest(cnn, test_x, test_y);%plot mean squared errorfigure; plot(cnn.rL);assert(er<0.12, 'Too big error');```Example: Neural Networks---------------------```matlabfunction test_example_NNload mnist_uint8;train_x = double(train_x) / 255;test_x = double(test_x) / 255;train_y = double(train_y);test_y = double(test_y);% normalize[train_x, mu, sigma] = zscore(train_x);test_x = normalize(test_x, mu, sigma);%% ex1 vanilla neural netrand('state',0)nn = nnsetup([784 100 10]);opts.numepochs = 1; % Number of full sweeps through dataopts.batchsize = 100; % Take a mean gradient step over this many samples[nn, L] = nntrain(nn, train_x, train_y, opts);[er, bad] = nntest(nn, test_x, test_y);assert(er < 0.08, 'Too big error');%% ex2 neural net with L2 weight decayrand('state',0)nn = nnsetup([784 100 10]);nn.weightPenaltyL2 = 1e-4; % L2 weight decayopts.numepochs = 1; % Number of full sweeps through dataopts.batchsize = 100; % Take a mean gradient step over this many samplesnn = nntrain(nn, train_x, train_y, opts);[er, bad] = nntest(nn, test_x, test_y);assert(er < 0.1, 'Too big error');%% ex3 neural net with dropoutrand('state',0)nn = nnsetup([784 100 10]);nn.dropoutFraction = 0.5; % Dropout fraction opts.numepochs = 1; % Number of full sweeps through dataopts.batchsize = 100; % Take a mean gradient step over this many samplesnn = nntrain(nn, train_x, train_y, opts);[er, bad] = nntest(nn, test_x, test_y);assert(er < 0.1, 'Too big error');%% ex4 neural net with sigmoid activation functionrand('state',0)nn = nnsetup([784 100 10]);nn.activation_function = 'sigm'; % Sigmoid activation functionnn.learningRate = 1; % Sigm require a lower learning rateopts.numepochs = 1; % Number of full sweeps through dataopts.batchsize = 100; % Take a mean gradient step over this many samplesnn = nntrain(nn, train_x, train_y, opts);[er, bad] = nntest(nn, test_x, test_y);assert(er < 0.1, 'Too big error');%% ex5 plotting functionalityrand('state',0)nn = nnsetup([784 20 10]);opts.numepochs = 5; % Number of full sweeps through datann.output = 'softmax'; % use softmax outputopts.batchsize = 1000; % Take a mean gradient step over this many samplesopts.plot = 1; % enable plottingnn = nntrain(nn, train_x, train_y, opts);[er, bad] = nntest(nn, test_x, test_y);assert(er < 0.1, 'Too big error');%% ex6 neural net with sigmoid activation and plotting of validation and training error% split training data into training and validation datavx = train_x(1:10000,:);tx = train_x(10001:end,:);vy = train_y(1:10000,:);ty = train_y(10001:end,:);rand('state',0)nn = nnsetup([784 20 10]); nn.output = 'softmax'; % use softmax outputopts.numepochs = 5; % Number of full sweeps through dataopts.batchsize = 1000; % Take a mean gradient step over this many samplesopts.plot = 1; % enable plottingnn = nntrain(nn, tx, ty, opts, vx, vy); % nntrain takes validation set as last two arguments (optionally)[er, bad] = nntest(nn, test_x, test_y);assert(er < 0.1, 'Too big error');```[![Bitdeli Badge](https://d2weczhvl823v0.cloudfront.net/rasmusbergpalm/deeplearntoolbox/trend.png)](https://bitdeli.com/free "Bitdeli Badge")

OV9734 DATASHEET,完整规格书

OV9734完整规格书,包括电气参数,尺寸规格,寄存器配置表等

Codeforces Round #412 (Div. 2)(Codeforces 807 ABCDE)

Codeforces Round #412 (Div. 2, base on VK Cup 2017 Round 3)比赛时过了3题,rating暴涨90+。。一定是上次只做出一题拉低了rating。。这场感觉AB都是题面杀。。然后比赛时看了DE感觉都可做,赛后补了一下。 官方题解依旧是高质量,耐心读,即使是会的题,也绝对收获不少。样例代码也很棒。 官方题解传送门:%touristCodefor

P.H.S 757

汉书HE8,好用的汇编代码编写工具

汉书HE8,好用的汇编代码编写工具早期编写汇编代码所用功能强大

Codeforces Round #807 (Div. 2) A-C题解

CF Round 807 Div2 题解 Codeforces Round #807 Div 2. Editorial

GoWilli的优快云 469

WINCC7.3破解文件

WINCC7.3硬件够破解文件,有需要的下载!WINCC7.3硬件够破解文件,有需要的下载!

Codeforces_807

A. 严格按照题目给的两个条件来。 #include<bits/stdc++.h> using namespace std; int n,a[1005],b[1005]; int main() { ios::sync_with_stdio(false); cin >> n; for(int i = 1;i &...

diaotan0836的博客 151

Codeforces Round #412 D. Dynamic Problem Scoring (枚举 + 贪心)

参考http://blog.csdn.net/dormousenone/article/details/71422868题意对于动态计分的 Codeforces Round ,已知每题的 score 是根据 Round 参加人数和该题过题人数计算,两者之比结合上图得出该题的分数。某人在该题的得分为 score×(1−t/250) 其中 t 表示通过该题的时间。已知参加该场比赛的所有参加者的过题情况(

now_ing的博客 338

# CF #807 Div.2(A - D)

​给定2n个数和k,请问是否存在n对(i,j)abs(ai-aj)>=k​先排序然后对1和n+1,2和n+2连续比对。​赛时拖了节奏因为看成了==k下次注意读题。

DM010maker的博客 395

codeforces807div2 E.Prairie Partition[二分]

E. Prairie Partition time limit per test 2 seconds memory limit per test 256 megabytes input standard input output standard output It can be shown that any positive inte

Qer的博客 794

764E Timofey and remoduling[数学]

E. Timofey and remoduling time limit per test 2 seconds memory limit per test 256 megabytes input standard input output standard output Little Timofey likes integers a l

Qer的博客 715

B. The Queue codeforces398div2

B. The Queue time limit per test 1 second memory limit per test 256 megabytes input standard input output standard output Finally! Vasya have come of age and that means

Qer的博客 660

761D Dasha and Very Difficult Problem[数学][思维]

D. Dasha and Very Difficult Problem time limit per test 2 seconds memory limit per test 256 megabytes input standard input output standard output Dasha logged into the s

Qer的博客 563

764D Timofey and rectangles[思维][染色]

D. Timofey and rectangles time limit per test 2 seconds memory limit per test 256 megabytes input standard input output standard output One of Timofey's birthday present

Qer的博客 534

HDU5972Regular Number [shiftand][字符串]

题意:给定n个集合,每个集合中有一些数字,问给出的一个长数字串中的所有匹配。 匹配:如果连续n个数字分别出现在1~n这些集合中,则是一个成功的匹配。 考虑每个数字出现的集合,用十个01二进制表示0~9这十个数字出现在那些集合中(预处理占位),然后通过左移操作和与运算验证是否匹配到n位。 使用bitset更方便操作。#include<bits/stdc++.h> using namespace s

Qer的博客 418
上一篇: codeforces807div2 C.Success Rate[二分][数学]
下一篇: codeforces807div2 E.Prairie Partition[二分]
Qer_
博客等级 码龄11年 34粉丝 69原创
评论
成就一亿技术人!
拼手气红包6.0元
还能输入1000个字符
 
 条评论被折叠 查看
添加红包

请填写红包祝福语或标题

个

红包个数最小为10个

元

红包金额最低5元

当前余额3.43元 前往充值 >
需支付:10.00元
成就一亿技术人!
领取后你会自动成为博主和红包主的粉丝 规则
hope_wisdom
发出的红包
实付元
使用余额支付
点击重新获取
扫码支付
钱包余额 0

抵扣说明:

1.余额是钱包充值的虚拟货币,按照1:1的比例进行支付金额的抵扣。
2.余额无法直接购买下载,可以购买VIP、付费专栏及课程。

余额充值