


出处:http://frodoking.github.io/2015/03/12/android-okhttp/
Android为我们提供了两种HTTP交互的方式:HttpURLConnection 和 Apache HTTP Client,虽然两者都支持HTTPS,流的上传和下载,配置超时,IPv6和连接池,已足够满足我们各种HTTP请求的需求。但更高效的使用HTTP可以让您的应用运行更快、更节省流量。而OkHttp库就是为此而生。
OkHttp是一个高效的HTTP库:
- 支持 SPDY ,共享同一个Socket来处理同一个服务器的所有请求
- 如果SPDY不可用,则通过连接池来减少请求延时
- 无缝的支持GZIP来减少数据流量
- 缓存响应数据来减少重复的网络请求
会从很多常用的连接问题中自动恢复。如果您的服务器配置了多个IP地址,当第一个IP连接失败的时候,OkHttp会自动尝试下一个IP。OkHttp还处理了代理服务器问题和SSL握手失败问题。
使用 OkHttp 无需重写您程序中的网络代码。OkHttp实现了几乎和java.net.HttpURLConnection一样的API。如果您用了 Apache HttpClient,则OkHttp也提供了一个对应的okhttp-apache 模块。
OKHttp源码位置https://github.com/square/okhttp
##使用
简单使用代码
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 | private final OkHttpClient client = new OkHttpClient(); public void run() throws Exception { Request request = new Request.Builder() .url("https://api.github.com/repos/square/okhttp/issues") .header("User-Agent", "OkHttp Headers.java") .addHeader("Accept", "application/json; q=0.5") .addHeader("Accept", "application/vnd.github.v3+json") .build(); Response response = client.newCall(request).execute(); if (!response.isSuccessful()) throw new IOException("Unexpected code " + response); System.out.println("Server: " + response.header("Server")); System.out.println("Date: " + response.header("Date")); System.out.println("Vary: " + response.headers("Vary")); } |
在这里使用不做详细介绍,推荐一篇关于OKHttp的详细使用教程,下面转入源码的分析。
##总体设计

上面是OKHttp总体设计图,主要是通过Diapatcher不断从RequestQueue中取出请求(Call),根据是否已缓存调用Cache或Network这两类数据获取接口之一,从内存缓存或是服务器取得请求的数据。该引擎有同步和异步请求,同步请求通过Call.execute()直接返回当前的Response,而异步请求会把当前的请求Call.enqueue添加(AsyncCall)到请求队列中,并通过回调(Callback)的方式来获取最后结果。
接下来会介绍一些比较重要的类,另外一些基础IO方面的内容主要来之iohttp这个包。这些类的解释大部分来至文档介绍本身,所以在此不会翻译成中文,本人觉得英语原文更能准确表达它自身的作用。
##OKHttp中重要的类
1.Route.java
The concrete route used by a connection to reach an abstract origin server.
When creating a connection the client has many options:
- HTTP proxy: a proxy server may be explicitly configured for the client. Otherwise the {@linkplain java.net.ProxySelector proxy selector} is used. It may return multiple proxies to attempt.
- IP address: whether connecting directly to an origin server or a proxy, opening a socket requires an IP address. The DNS server may return multiple IP addresses to attempt.
- TLS configuration: which cipher suites and TLS versions to attempt with the HTTPS connection.
Each route is a specific selection of these options.
其实就是对地址的一个封装类,但是很重要。
2.Platform.java
Access to platform-specific features.
- Server name indication (SNI): Supported on Android 2.3+.
- Session Tickets: Supported on Android 2.3+.
- Android Traffic Stats (Socket Tagging): Supported on Android 4.0+.
- ALPN (Application Layer Protocol Negotiation): Supported on Android 5.0+. The APIs were present in Android 4.4, but that implementation was unstable.
Supported on OpenJDK 7 and 8 (via the JettyALPN-boot library).
这个类主要是做平台适应性,针对Android2.3到5.0后的网络请求的适配支持。同时,在这个类中能看到针对不同平台,通过java反射不同的class是不一样的。
3.Connnection.java
The sockets and streams of an HTTP, HTTPS, or HTTPS+SPDY connection. May be used for multiple HTTP request/response exchanges. Connections may be direct to the origin server or via a proxy.
Typically instances of this class are created, connected and exercised automatically by the HTTP client. Applications may use this class to monitor HTTP connections as members of a ConnectionPool.
Do not confuse this class with the misnamed HttpURLConnection, which isn’t so much a connection as a single request/response exchange.
Modern TLS
There are tradeoffs when selecting which options to include when negotiating a secure connection to a remote host. Newer TLS options are quite useful:
- Server Name Indication (SNI) enables one IP address to negotiate secure connections for multiple domain names.
- Application Layer Protocol Negotiation (ALPN) enables the HTTPS port (443) to be used for different HTTP and SPDY protocols.
Unfortunately, older HTTPS servers refuse to connect when such options are presented. Rather than avoiding these options entirely, this class allows a connection to be attempted with modern options and then retried without them should the attempt fail.
4.ConnnectionPool.java
Manages reuse of HTTP and SPDY connections for reduced network latency. HTTP requests that share the same Address may share a Connection. This class implements the policy of which connections to keep open for future use.
The system-wide default uses system properties for tuning parameters:
- http.keepAlive true if HTTP and SPDY connections should be pooled at all. Default is true.
- http.maxConnections maximum number of idle connections to each to keep in the pool. Default is 5.
- http.keepAliveDuration Time in milliseconds to keep the connection alive in the pool before closing it. Default is 5 minutes. This property isn’t used by HttpURLConnection.
The default instance doesn’t adjust its configuration as system properties are changed. This assumes that the applications that set these parameters do so before making HTTP connections, and that this class is initialized lazily.
5.Request.java
An HTTP request. Instances of this class are immutable if their body is null or itself immutable.(Builder模式)
6.Response.java
An HTTP response. Instances of this class are not immutable: the response body is a one-shot value that may be consumed only once. All other properties are immutable.
7.Call.java
A call is a request that has been prepared for execution. A call can be canceled. As this object represents a single request/response pair (stream), it cannot be executed twice.
8.Dispatcher.java
Policy on when async requests are executed.
Each dispatcher uses an ExecutorService to run calls internally. If you supply your own executor, it should be able to run configured maximum number of calls concurrently.
9.HttpEngine.java
Handles a single HTTP request/response pair. Each HTTP engine follows this
lifecycle:
- It is created.
- The HTTP request message is sent with sendRequest(). Once the request is sent it is an error to modify the request headers. After sendRequest() has been called the request body can be written to if it exists.
- The HTTP response message is read with readResponse(). After the response has been read the response headers and body can be read. All responses have a response body input stream, though in some instances this stream is empty.
The request and response may be served by the HTTP response cache, by the network, or by both in the event of a conditional GET.
10.Internal.java
Escalate internal APIs in {@code com.squareup.okhttp} so they can be used from OkHttp’s implementation packages. The only implementation of this interface is in {@link com.squareup.okhttp.OkHttpClient}.
11.Cache.java
Caches HTTP and HTTPS responses to the filesystem so they may be reused, saving time and bandwidth.
Cache Optimization
To measure cache effectiveness, this class tracks three statistics:
- Request Count: the number of HTTP requests issued since this cache was created.
- Network Count: the number of those requests that required network use.
- Hit Count: the number of those requests whose responses were served by the cache.
Sometimes a request will result in a conditional cache hit. If the cache contains a stale copy of the response, the client will issue a conditional GET. The server will then send either the updated response if it has changed, or a short ‘not modified’ response if the client’s copy is still valid. Such responses increment both the network count and hit count.
The best way to improve the cache hit rate is by configuring the web server to return cacheable responses. Although this client honors all HTTP/1.1 (RFC 2068) cache headers, it doesn’t cache partial responses.
Force a Network Response
In some situations, such as after a user clicks a ‘refresh’ button, it may be necessary to skip the cache, and fetch data directly from the server. To force a full refresh, add the {@code no-cache} directive:
1
| connection.addRequestProperty("Cache-Control", "no-cache")
|
If it is only necessary to force a cached response to be validated by the server, use the more efficient {@code max-age=0} instead:
1
| connection.addRequestProperty("Cache-Control", "max-age=0");
|
Force a Cache Response
Sometimes you’ll want to show resources if they are available immediately, but not otherwise. This can be used so your application can show something while waiting for the latest data to be downloaded. To restrict a request to locally-cached resources, add the {@code only-if-cached} directive:
1 2 3 4 5 6 7 | try { connection.addRequestProperty("Cache-Control", "only-if-cached"); InputStream cached = connection.getInputStream(); // the resource was cached! show it } catch (FileNotFoundException e) { // the resource was not cached } |
This technique works even better in situations where a stale response is better than no response. To permit stale cached responses, use the {@code max-stale} directive with the maximum staleness in seconds:
1 2 | int maxStale = 60 * 60 * 24 * 28; // tolerate 4-weeks stale connection.addRequestProperty("Cache-Control", "max-stale=" + maxStale); |
12.OkHttpClient.java
Configures and creates HTTP connections. Most applications can use a single OkHttpClient for all of their HTTP requests - benefiting from a shared response cache, thread pool, connection re-use, etc.
Instances of OkHttpClient are intended to be fully configured before they’re shared - once shared they should be treated as immutable and can safely be used to concurrently open new connections. If required, threads can call clone to make a shallow copy of the OkHttpClient that can be safely modified with further configuration changes.
##请求流程图
下面是关于OKHttp的请求流程图

##详细类关系图
由于整个设计类图比较大,所以本人将从核心入口client、cache、interceptor、网络配置、连接池、平台适配性…这些方面来逐一进行分析源代码的设计。
下面是核心入口OkHttpClient的类设计图

从OkHttpClient类的整体设计来看,它采用门面模式来。client知晓子模块的所有配置以及提供需要的参数。client会将所有从客户端发来的请求委派到相应的子系统去。
在该系统中,有多个子系统、类或者类的集合。例如上面的cache、连接以及连接池相关类的集合、网络配置相关类集合等等。每个子系统都可以被客户端直接调用,或者被门面角色调用。子系统并不知道门面的存在,对于子系统而言,门面仅仅是另外一个客户端而已。同时,OkHttpClient可以看作是整个框架的上下文。
通过类图,其实很明显反应了该框架的几大核心子系统;路由、连接协议、拦截器、代理、安全性认证、连接池以及网络适配。从client大大降低了开发者使用难度。同时非常明了的展示了该框架在所有需要的配置以及获取结果的方式。
在接下来的几个Section中将会结合子模块核心类的设计,从该框架的整体特性上来分析这些模块是如何实现各自功能。以及各个模块之间是如何相互配合来完成客户端各种复杂请求。
##同步与异步的实现
在发起请求时,整个框架主要通过Call来封装每一次的请求。同时Call持有OkHttpClient和一份HttpEngine。而每一次的同步或者异步请求都会有Dispatcher的参与,不同的是:
- 同步
Dispatcher会在同步执行任务队列中记录当前被执行过得任务Call,同时在当前线程中去执行Call的getResponseWithInterceptorChain()方法,直接获取当前的返回数据Response;- 异步
首先来说一下Dispatcher,Dispatcher内部实现了懒加载无边界限制的线程池方式,同时该线程池采用了SynchronousQueue这种阻塞队列。SynchronousQueue每个插入操作必须等待另一个线程的移除操作,同样任何一个移除操作都等待另一个线程的插入操作。因此此队列内部其 实没有任何一个元素,或者说容量是0,严格说并不是一种容器。由于队列没有容量,因此不能调用peek操作,因为只有移除元素时才有元素。显然这是一种快速传递元素的方式,也就是说在这种情况下元素总是以最快的方式从插入者(生产者)传递给移除者(消费者),这在多任务队列中是最快处理任务的方式。对于高频繁请求的场景,无疑是最适合的。
异步执行是通过Call.enqueue(Callback responseCallback)来执行,在Dispatcher中添加一个封装了Callback的Call的匿名内部类Runnable来执行当前的Call。这里一定要注意的地方这个AsyncCall是Call的匿名内部类。AsyncCall的execute方法仍然会回调到Call的getResponseWithInterceptorChain方法来完成请求,同时将返回数据或者状态通过Callback来完成。
接下来继续讲讲Call的getResponseWithInterceptorChain()方法,这里边重点说一下拦截器链条的实现以及作用。
##拦截器有什么作用
先来看看Interceptor本身的文档解释:观察,修改以及可能短路的请求输出和响应请求的回来。通常情况下拦截器用来添加,移除或者转换请求或者回应的头部信息。
拦截器接口中有intercept(Chain chain)方法,同时返回Response。所谓拦截器更像是AOP设计的一种实现。下面来看一个okhttp源码中的一个引导例子来说明拦截器的作用。
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 | public final class LoggingInterceptors { private static final Logger logger = Logger.getLogger(LoggingInterceptors.class.getName()); private final OkHttpClient client = new OkHttpClient(); public LoggingInterceptors() { client.networkInterceptors().add(new Interceptor() { @Override public Response intercept(Chain chain) throws IOException { long t1 = System.nanoTime(); Request request = chain.request(); logger.info(String.format("Sending request %s on %s%n%s", request.url(), chain.connection(), request.headers())); Response response = chain.proceed(request); long t2 = System.nanoTime(); logger.info(String.format("Received response for %s in %.1fms%n%s", request.url(), (t2 - t1) / 1e6d, response.headers())); return response; } }); } public void run() throws Exception { Request request = new Request.Builder() .url("https://publicobject.com/helloworld.txt") .build(); Response response = client.newCall(request).execute(); response.body().close(); } public static void main(String... args) throws Exception { new LoggingInterceptors().run(); } } |
返回信息
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 | 三月 19, 2015 2:11:29 下午 com.squareup.okhttp.recipes.LoggingInterceptors$1 intercept 信息: Sending request https://publicobject.com/helloworld.txt on Connection{publicobject.com:443, proxy=DIRECT hostAddress=54.187.32.157 cipherSuite=TLS_ECDHE_RSA_WITH_AES_128_CBC_SHA protocol=http/1.1} Host: publicobject.com Connection: Keep-Alive Accept-Encoding: gzip User-Agent: 三月 19, 2015 2:11:30 下午 com.squareup.okhttp.recipes.LoggingInterceptors$1 intercept 信息: Received response for https://publicobject.com/helloworld.txt in 275.9ms Server: nginx/1.4.6 (Ubuntu) Date: Thu, 19 Mar 2015 06:08:50 GMT Content-Type: text/plain Content-Length: 1759 Last-Modified: Tue, 27 May 2014 02:35:47 GMT Connection: keep-alive ETag: "5383fa03-6df" Accept-Ranges: bytes OkHttp-Selected-Protocol: http/1.1 OkHttp-Sent-Millis: 1426745489953 OkHttp-Received-Millis: 1426745490198 |
从这里的执行来看,拦截器主要是针对Request和Response的切面处理。
那再来看看源码到底在什么位置做的这个处理呢?为了更加直观的反应执行流程,本人截图了一下执行堆栈
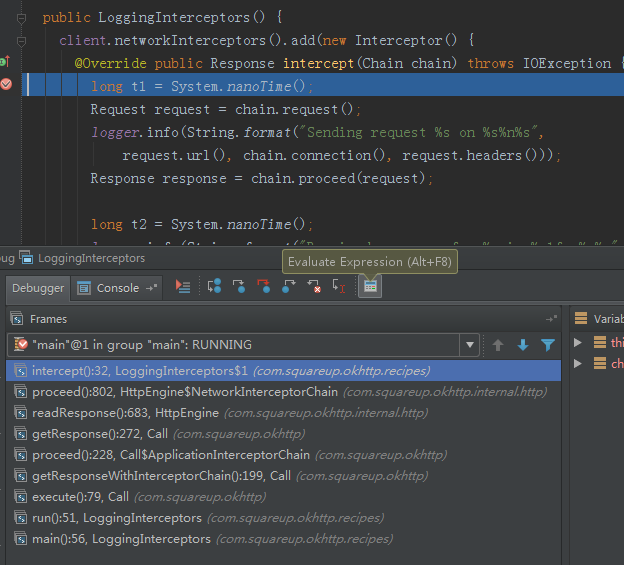
另外如果还有同学对Interceptor比较敢兴趣的可以去源码的simples模块看看GzipRequestInterceptor.java针对HTTP request body的一个zip压缩。
在这里再多说一下关于Call这个类的作用,在Call中持有一个HttpEngine。每一个不同的Call都有自己独立的HttpEngine。在HttpEngine中主要是各种链路和地址的选择,还有一个Transport比较重要
##缓存策略
在OkHttpClient内部暴露了有Cache和InternalCache。而InternalCache不应该手动去创建,所以作为开发使用者来说,一般用法如下:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 | public final class CacheResponse { private static final Logger logger = Logger.getLogger(LoggingInterceptors.class.getName()); private final OkHttpClient client; public CacheResponse(File cacheDirectory) throws Exception { logger.info(String.format("Cache file path %s",cacheDirectory.getAbsoluteFile())); int cacheSize = 10 * 1024 * 1024; // 10 MiB Cache cache = new Cache(cacheDirectory, cacheSize); client = new OkHttpClient(); client.setCache(cache); } public void run() throws Exception { Request request = new Request.Builder() .url("http://publicobject.com/helloworld.txt") .build(); Response response1 = client.newCall(request).execute(); if (!response1.isSuccessful()) throw new IOException("Unexpected code " + response1); String response1Body = response1.body().string(); System.out.println("Response 1 response: " + response1); System.out.println("Response 1 cache response: " + response1.cacheResponse()); System.out.println("Response 1 network response: " + response1.networkResponse()); Response response2 = client.newCall(request).execute(); if (!response2.isSuccessful()) throw new IOException("Unexpected code " + response2); String response2Body = response2.body().string(); System.out.println("Response 2 response: " + response2); System.out.println("Response 2 cache response: " + response2.cacheResponse()); System.out.println("Response 2 network response: " + response2.networkResponse()); System.out.println("Response 2 equals Response 1? " + response1Body.equals(response2Body)); } public static void main(String... args) throws Exception { new CacheResponse(new File("CacheResponse.tmp")).run(); } } |
返回信息
1 2 3 4 5 6 7 8 9 10 | 信息: Cache file path D:\work\workspaces\workspaces_intellij\workspace_opensource\okhttp\CacheResponse.tmp Response 1 response: Response{protocol=http/1.1, code=200, message=OK, url=https://publicobject.com/helloworld.txt} Response 1 cache response: null Response 1 network response: Response{protocol=http/1.1, code=200, message=OK, url=https://publicobject.com/helloworld.txt} Response 2 response: Response{protocol=http/1.1, code=200, message=OK, url=https://publicobject.com/helloworld.txt} Response 2 cache response: Response{protocol=http/1.1, code=200, message=OK, url=https://publicobject.com/helloworld.txt} Response 2 network response: null Response 2 equals Response 1? true Process finished with exit code 0 |
上边这一段代码同样来之于simple代码CacheResponse.java,反馈回来的数据重点看一下缓存日志。第一次是来至网络数据,第二次来至缓存。
那在这一节重点说一下整个框架的缓存策略如何实现的。
在这里继续使用上一节中讲到的运行堆栈图。从Call.getResponse(Request request, boolean forWebSocket)执行Engine.sendRequest()和Engine.readResponse()来详细说明一下。
sendRequest()
此方法是对可能的Response资源进行一个预判,如果需要就会开启一个socket来获取资源。如果请求存在那么就会为当前request添加请求头部并且准备开始写入request body。
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 | public void sendRequest() throws IOException { if (cacheStrategy != null) { return; // Already sent. } if (transport != null) { throw new IllegalStateException(); } //填充默认的请求头部和事务。 Request request = networkRequest(userRequest); //下面一行很重要,这个方法会去获取client中的Cache。同时Cache在初始化的时候会去读取缓存目录中关于曾经请求过的所有信息。 InternalCache responseCache = Internal.instance.internalCache(client); Response cacheCandidate = responseCache != null? responseCache.get(request): null; long now = System.currentTimeMillis(); //缓存策略中的各种配置的封装 cacheStrategy = new CacheStrategy.Factory(now, request, cacheCandidate).get(); networkRequest = cacheStrategy.networkRequest; cacheResponse = cacheStrategy.cacheResponse; if (responseCache != null) { //记录当前请求是来至网络还是命中了缓存 responseCache.trackResponse(cacheStrategy); } if (cacheCandidate != null && cacheResponse == null) { closeQuietly(cacheCandidate.body()); // The cache candidate wasn't applicable. Close it. } if (networkRequest != null) { // Open a connection unless we inherited one from a redirect. if (connection == null) { //连接到服务器、重定向服务器或者通过一个代理Connect to the origin server either directly or via a proxy. connect(); } //通过Connection创建一个SpdyTransport或者HttpTransport transport = Internal.instance.newTransport(connection, this); ... } else { ... } } |
readResponse()
此方法发起刷新请求头部和请求体,解析HTTP回应头部,并且如果HTTP回应体存在的话就开始读取当前回应头。在这里有发起返回存入缓存系统,也有返回和缓存系统进行一个对比的过程。
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 | public void readResponse() throws IOException { ... Response networkResponse; if (forWebSocket) { ... } else if (!callerWritesRequestBody) { // 这里主要是看当前的请求body,其实真正请求是在这里发生的。 // 在readNetworkResponse()方法中执行transport.finishRequest() // 这里可以看一下该方法内部会调用到HttpConnection.flush()方法 networkResponse = new NetworkInterceptorChain(0, networkRequest).proceed(networkRequest); } else { ... } //对Response头部事务存入事务管理中 receiveHeaders(networkResponse.headers()); // If we have a cache response too, then we're doing a conditional get. if (cacheResponse != null) { //检查缓存是否可用,如果可用。那么就用当前缓存的Response,关闭网络连接,释放连接。 if (validate(cacheResponse, networkResponse)) { userResponse = cacheResponse.newBuilder() .request(userRequest) .priorResponse(stripBody(priorResponse)) .headers(combine(cacheResponse.headers(), networkResponse.headers())) .cacheResponse(stripBody(cacheResponse)) .networkResponse(stripBody(networkResponse)) .build(); networkResponse.body().close(); releaseConnection(); // Update the cache after combining headers but before stripping the // Content-Encoding header (as performed by initContentStream()). // 更新缓存以及缓存命中情况 InternalCache responseCache = Internal.instance.internalCache(client); responseCache.trackConditionalCacheHit(); responseCache.update(cacheResponse, stripBody(userResponse)); // unzip解压缩response userResponse = unzip(userResponse); return; } else { closeQuietly(cacheResponse.body()); } } userResponse = networkResponse.newBuilder() .request(userRequest) .priorResponse(stripBody(priorResponse)) .cacheResponse(stripBody(cacheResponse)) .networkResponse(stripBody(networkResponse)) .build(); //发起缓存的地方 if (hasBody(userResponse)) { maybeCache(); userResponse = unzip(cacheWritingResponse(storeRequest, userResponse)); } } |
##HTTP连接的实现方式(说说连接池)
外部网络请求的入口都是通过Transport接口来完成。该类采用了桥接模式将HttpEngine和HttpConnection来连接起来。因为HttpEngine只是一个逻辑处理器,同时它也充当了请求配置的提供引擎,而HttpConnection是对底层处理Connection的封装。
OK现在重点转移到HttpConnection(一个用于发送HTTP/1.1信息的socket连接)这里。主要有如下的生命周期:
1、发送请求头;
2、打开一个sink(io中有固定长度的或者块结构chunked方式的)去写入请求body;
3、写入并且关闭sink;
4、读取Response头部;
5、打开一个source(对应到第2步的sink方式)去读取Response的body;
6、读取并关闭source;
下边看一张关于连接执行的时序图:

这张图画得比较简单,详细的过程以及连接池的使用下面大致说明一下:
1、连接池是暴露在client下的,它贯穿了Transport、HttpEngine、Connection、HttpConnection和SpdyConnection;在这里目前默认讨论HttpConnection;
2、ConnectionPool有两个构建参数是maxIdleConnections(最大空闲连接数)和keepAliveDurationNs(存活时间),另外连接池默认的线程池采用了Single的模式(源码解释是:一个用于清理过期的多个连接的后台线程,最多一个单线程去运行每一个连接池);
3、发起请求是在Connection.connect()这里,实际执行是在HttpConnection.flush()这里进行一个刷入。这里重点应该关注一下sink和source,他们创建的默认方式都是依托于同一个socket:
this.source = Okio.buffer(Okio.source(socket));
this.sink = Okio.buffer(Okio.sink(socket));
如果再进一步看一下io的源码就能看到:
Source source = source((InputStream)socket.getInputStream(), (Timeout)timeout);
Sink sink = sink((OutputStream)socket.getOutputStream(), (Timeout)timeout);
这下我想大家都应该明白这里到底是真么回事儿了吧?
相关的sink和source还有相应的细分,如果有兴趣的朋友可以继续深入看一下,这里就不再深入了。不然真的说不完了。。。
其实连接池这里还是有很多值得细看的地方,由于时间有限,到这里已经花了很多时间搞这事儿了。。。
##重连机制
这里重点说说连接链路的相关事情。说说自动重连到底是如何实现的。
照样先来看看下面的这个自动重连机制的实现方式时序图

同时回到Call.getResponse()方法说起
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 | Response getResponse(Request request, boolean forWebSocket) throws IOException { ... while (true) { // 自动重连机制的循环处理 if (canceled) { engine.releaseConnection(); return null; } try { engine.sendRequest(); engine.readResponse(); } catch (IOException e) { //如果上一次连接异常,那么当前连接进行一个恢复。 HttpEngine retryEngine = engine.recover(e, null); if (retryEngine != null) { engine = retryEngine; continue;//如果恢复成功,那么继续重新请求 } // Give up; recovery is not possible.如果不行,那么就中断了 throw e; } Response response = engine.getResponse(); Request followUp = engine.followUpRequest(); ... } } |
相信这一段代码能让同学们清晰的看到自动重连机制的实现方式,那么我们来看看详细的步骤:
1、HttpEngine.recover()的实现方式是通过检测RouteSelector是否还有更多的routes可以尝试连接,同时会去检查是否可以恢复等等的一系列判断。如果可以会为重新连接重新创建一份新的HttpEngine,同时把相应的链路信息传递过去;
2、当恢复后的HttpEngine不为空,那么替换当前Call中的当前HttpEngine,执行while的continue,发起下一次的请求;
3、再重点强调一点HttpEngine.sendRequest()。这里之前分析过会触发connect()方法,在该方法中会通过RouteSelector.next()再去找当前适合的Route。多说一点,next()方法会传递到nextInetSocketAddress()方法,而此处一段重要的执行代码就是network.resolveInetAddresses(socketHost)。这个地方最重要的是在Network这个接口中有一个对该接口的DEFAULT的实现域,而该方法通过工具类InetAddress.getAllByName(host)来完成对数组类的地址解析。
所以,多地址可以采用[“http://aaaaa","https://bbbbbb"]的方式来配置。
##Gzip的使用方式
在源码引导RequestBodyCompression.java中我们可以看到gzip的使用身影。通过拦截器对Request 的body进行gzip的压缩,来减少流量的传输。
Gzip实现的方式主要是通过GzipSink对普通sink的封装压缩。在这个地方就不再贴相关代码的实现。有兴趣同学对照源码看一下就ok。
强大的Interceptor设计应该也算是这个框架的一个亮点。
##安全性
连接安全性主要是在HttpEngine.connect()方法。上一节油讲到地址相关的选择,在HttpEngine中有一个静态方法createAddress(client, networkRequest),在这里通过获取到OkHttpClient中关于SSLSocketFactory、HostnameVerifier和CertificatePinner的配置信息。而这些信息大部分采用默认情况。这些信息都会在后面的重连中作为对比参考项。
同时在Connection.upgradeToTls()方法中,有对SSLSocket、SSLSocketFactory的创建活动。这些创建都会被记录到ConnectionSpec中,当发起ConnectionSpec.apply()会发起一些列的配置以及验证。
建议有兴趣的同学先了解java的SSLSocket相关的开发再来了解本框架中的安全性,会更能理解一些。
##平台适应性
讲了很多,终于来到了平台适应性了。Platform是整个平台适应的核心类。同时它封装了针对不同平台的三个平台类Android和JdkWithJettyBootPlatform。
代码实现在Platform.findPlatform中
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 | private static Platform findPlatform() { // Attempt to find Android 2.3+ APIs. try { try { Class.forName("com.android.org.conscrypt.OpenSSLSocketImpl"); } catch (ClassNotFoundException e) { // Older platform before being unbundled. Class.forName("org.apache.harmony.xnet.provider.jsse.OpenSSLSocketImpl"); } OptionalMethod<Socket> setUseSessionTickets = new OptionalMethod<>(null, "setUseSessionTickets", boolean.class); OptionalMethod<Socket> setHostname = new OptionalMethod<>(null, "setHostname", String.class); Method trafficStatsTagSocket = null; Method trafficStatsUntagSocket = null; OptionalMethod<Socket> getAlpnSelectedProtocol = null; OptionalMethod<Socket> setAlpnProtocols = null; // Attempt to find Android 4.0+ APIs. try { //流浪统计类 Class<?> trafficStats = Class.forName("android.net.TrafficStats"); trafficStatsTagSocket = trafficStats.getMethod("tagSocket", Socket.class); trafficStatsUntagSocket = trafficStats.getMethod("untagSocket", Socket.class); // Attempt to find Android 5.0+ APIs. try { Class.forName("android.net.Network"); // Arbitrary class added in Android 5.0. getAlpnSelectedProtocol = new OptionalMethod<>(byte[].class, "getAlpnSelectedProtocol"); setAlpnProtocols = new OptionalMethod<>(null, "setAlpnProtocols", byte[].class); } catch (ClassNotFoundException ignored) { } } catch (ClassNotFoundException | NoSuchMethodException ignored) { } return new Android(setUseSessionTickets, setHostname, trafficStatsTagSocket, trafficStatsUntagSocket, getAlpnSelectedProtocol, setAlpnProtocols); } catch (ClassNotFoundException ignored) { // This isn't an Android runtime. } // Find Jetty's ALPN extension for OpenJDK. try { String negoClassName = "org.eclipse.jetty.alpn.ALPN"; Class<?> negoClass = Class.forName(negoClassName); Class<?> providerClass = Class.forName(negoClassName + "$Provider"); Class<?> clientProviderClass = Class.forName(negoClassName + "$ClientProvider"); Class<?> serverProviderClass = Class.forName(negoClassName + "$ServerProvider"); Method putMethod = negoClass.getMethod("put", SSLSocket.class, providerClass); Method getMethod = negoClass.getMethod("get", SSLSocket.class); Method removeMethod = negoClass.getMethod("remove", SSLSocket.class); return new JdkWithJettyBootPlatform( putMethod, getMethod, removeMethod, clientProviderClass, serverProviderClass); } catch (ClassNotFoundException | NoSuchMethodException ignored) { } return new Platform(); } |
这里采用了JAVA的反射原理调用到class的method。最后在各自的平台调用下发起invoke来执行相应方法。详情请参看继承了Platform的Android类。
当然要做这两种的平台适应,必须要知道当前平台在内存中相关的class地址以及相关方法。
##总结
1、从整体结构和类内部域中都可以看到OkHttpClient,有点类似与安卓的ApplicationContext。看起来更像一个单例的类,这样使用好处是统一。但是如果你不是高手,建议别这么用,原因很简单:逻辑牵连太深,如果出现问题要去追踪你会有深深地罪恶感的;
2、框架中的一些动态方法、静态方法、匿名内部类以及Internal的这些代码相当规整,每个不同类的不同功能能划分在不同的地方。很值得开发者学习的地方;
3、从平台的兼容性来讲,也是很不错的典范(如果你以后要从事API相关编码,那更得好好注意对兼容性的处理);
4、由于时间不是很富裕,所以本人对细节的把握还是不够,这方面还得多多努力;
5、对于初学网络编程的同学来说,可能一开始学习都是从简单的socket的发起然后获取响应开始的。因为没有很好的场景能让自己知道网络编程到底有多么的重要,当然估计也没感受到网络编程有多么的难受。我想这是很多刚入行的同学们的一种内心痛苦之处;
6、不足的地方是没有对SPDY的方式最详细跟进剖析(手头还有工作的事情,后面如果有时间再补起来吧)。
##结束语
很早前都打算花点时间好好来看一个值得学习的框架,今天终于算是弄得差不多了。我相信从框架的前期使用、到代码的介入、再到源码分模块的剖析、最后到整理成文章。我想这都是一个很好的学习和成长的过程。
希望看到这篇文章的同学能做出评价,并且给出一些好的剖析点。
我也是一个普普通通的编码人,只是内心多了一点点不“安分” ^.^。
##后续
最近看到一些网友建议把okhttp的连接池对Connection的重用维护机制以及HTTP和SPDY协议如何得到区分这两部分内容做深入的分析
有需要的同学请移步:OKHttp源码解析-ConnectionPool对Connection重用机制&Http/Https/SPDY协议选择

 479


 扫一扫


 被折叠的 条评论
为什么被折叠?
 到【灌水乐园】发言


