Assembly line / Pipeline

Azure DevOps四段式CI/CD实战:构建、测试、制品、部署全链路避坑指南 CI/CD是现代软件交付的核心实践,其本质是通过自动化流水线实现代码到生产环境的可靠、可重复、可审计转化。其底层原理依赖于构建(Build)、测试(Test)、制品(Package)、部署(Deploy)四个关键阶段的解耦协同与契约化交接。技术价值在于显著降低人工干预风险、加速反馈闭环、强化质量门禁并满足合规审计要求。典型应用场景包括金融级SaaS持续交付、医疗系统灰度发布、多团队并行微服务治理等。本文聚焦Azure DevOps平台,深入解析分层Pipeline设计、YAML字段血泪配置、NuGet制品可 阅读详情

Problem Definition

Cache Data Refresh


  • We have 576 cache files, each file (in fact, a file pair, one is an index file, the other is data file) contains point to address mapping: (latitude, longitude) -> Address, i.e., the result of reverse geocoding.
  • some data (addresses) may be out of date, now we need get updated address of those points.

Requirement

  1. There is no date info for each cache entry [point, address], so we refresh all points in cache file,  that is, regenerate the cache file in whole.
  2. The refresh can be interrupted and continue from the breakpoint - we do not want start from beginning. 
  3. Total points number is about 80M, we need finish it in given time, or the refresh duration time can be controlled.
  4. The refresh is done on-line. After refresh finished, the server switch to new cache file and back up old cache file.
  5. There are several peer server, each server has same data (576 cache files), we want all of the server get updated addresses in the same time.

Solution1

  1. For each cache file
    • For each point in the cache file
      • read point from cache file - R
      • get updated address - G
      • write new address into new cache file - W

Limits:

  • If the refresh is interrupted, one cache file need restart at right beginning. Suppose a cache file contains 5m points, the server crash when the refresh coming to the last point of 5m points. Then all the 4.99m effort is lost.
  • The whole process is in single thread, its rate is limits by the bottleneck process: get updated address.

Solution2

Instead of 'R-G-W' one point by one point. We first snap all the points in the cache file intensively, and put all the point in 4096 point files. So each point file contains a certain number of points.  Then use several threads to repeat 'R-G' process using point files, and one threads to repeat 'W' process. Once a point file is finished, delete it and process next file.

  1. For each cache file
    • For each point in the cache file
      • read point from cache file
      • write point into point file, create a new file every 80m/4096 points
  2. For each point file
    • For each point in the point file - multiply threads, each threads handle one file
      • read point from point file
      • get updated address
      • add new address into write thread queue
    • Delete the point file once it finish all the points
  3. For each point in the write queue
    • Write new address into new cache file

Benefit:

  • If the refresh is interrupted, at most one point file work is lost. 
  • Use multiply threads in bottleneck function('G'), so we speed up the whole refresh. The refresh rate is controlled by thread number

Postmortem


1. How to handle batch process


1) break down (Split) and reassemble to get pipelining

http://en.wikipedia.org/wiki/Assembly_line

Consider the assembly of a car: assume that certain steps in the assembly line are to install the engine, install the hood, and install the wheels (in that order, with arbitrary interstitial steps); only one of these steps can be done at a time. In traditional production, only one car would be assembled at a time. If engine installation takes 20 minutes, hood installation takes 5 minutes, and wheel installation takes 10 minutes, then a car can be produced every 35 minutes.
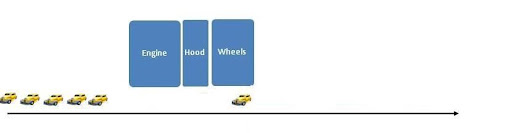

In an assembly line, car assembly is split between several stations, all working simultaneously. When one station is finished with a car, it passes it on to the next. By having three stations, a total of three different cars can be operated on at the same time, each one at a different stage of its assembly.
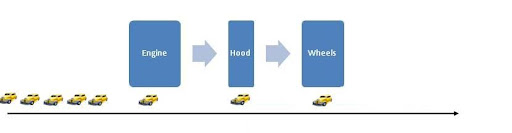


After finishing its work on the first car, the engine installation crew can begin working on the second car. While the engine installation crew works on the second car, the first car can be moved to the hood station and fitted with a hood, then to the wheels station and be fitted with wheels. After the engine has been installed on the second car, the second car moves to the hood assembly. At the same time, the third car moves to the engine assembly. When the third car’s engine has been mounted, it then can be moved to the hood station; meanwhile, subsequent cars (if any) can be moved to the engine installation station.


Assuming no loss of time when moving a car from one station to another, the longest stage on the assembly line determines the throughput (20 minutes for the engine installation) so a car can be produced every 20 minutes, once the first car taking 35 minutes has been produced.


http://en.wikipedia.org/wiki/Pipeline_(computing)

http://en.wikipedia.org/wiki/Instruction_pipeline


2) find the bottleneck in a proper granularity


3) intermediate result/state may be helpful. In above case, point file. 


2. Cache Design

Considering about cache expire. Generally Date info or life time is created together with cache entry.


3. Quadtrees

Why not database to store the entry ?


please see Quadtrees

1) C++ Implementation 

2) Use Case

C/C++底层原理深度解析:从源码到硬件,掌握系统级编程核心 理解计算机程序的底层运行机制是每个开发者进阶的必经之路。从高级语言到机器指令的转换,涉及编译、链接等核心过程,这些原理决定了程序的执行效率与稳定性。在系统级编程中,内存管理、CPU缓存优化和并发控制等技术价值尤为突出,直接影响着操作系统、数据库和高性能中间件等关键应用的性能表现。通过剖析C语言内存管理、hashmap底层实现原理等热词背后的技术细节,开发者能够穿透抽象层,掌握程序从源码到硬件执行的完整链路,从而编写出更高效、可控的系统软件。 阅读详情

相关推荐

de-novo-transcriptome-assembly-pipeline:从头组合转录组组装-多个汇编程序-多个参数

从头转录组装配流程 该流水线使用组合的从头转录组组装流水线将多个汇编器和多个参数组合在一起。 有关更多信息,请转到 如有其他疑问,请联系NCGAS团队( ) 该管道当前仅设置了TORQUE作业处理程序(SLURM正在进行中,将很快更新),当前设置是针对IU Carbonate Cluster。 如果您想在自己的硬件上运行它,我们可以帮助您将脚本转换为在您的计算机上运行。 阅读自述文件。 每个文件夹中都有自述文件。 步骤0: 您将需要运行启动脚本来设置您的电子邮件,项目位置,并指定您是使用单链还是双链。 可以使用以下命令完成此操作: Setup.ba -e -s -r -i @@ -29,21 +29,21 @@您可以使用以下方法获得所有软件的引用:注:您可以多次更改电子邮件和链设置,但当前可以使用目录将仅在第一次运行。 只要您不移动目录,就不会造成任何问题。 另外,此步骤可能需要

Genomes correction and assembling - Present methods and tools

Genomes correction and assembling - Present methods and tools 基因组校正和组装-现有的方法和工具 摘要 新一代测序(NGS)技术的迅速发展对基因组学研究领域产生了重大影响,使许多以前受技术成本限制的新物种测序项目得以实施。随着NGS的发展,需要对装配程序进行调整。新算法必须在合理的时间限制内处理大量的数据计算,处理能力和硬件也是一...

wangprince2017 687

别再死磕NFP了!用Python+遗传算法搞定异形件自动排版(附完整代码)

本文介绍了如何利用Python和遗传算法实现异形件智能排版,解决传统NFP方法计算复杂的问题。通过Shapely库处理几何运算和DEAP库搭建遗传算法框架,结合模拟退火策略避免局部最优,显著提升材料利用率。附完整代码和优化技巧,适用于服装裁剪、金属加工等行业。

weixin_26965807的博客 236

Assemblyline 开源项目安装与使用指南

Assemblyline 开源项目安装与使用指南 1. 项目目录结构及介绍 Assemblyline 是一个由加拿大网络安全中心开发的可扩展文件分类和恶意软件分析系统,它整合了安全社区的最佳工具。以下是其主要的目录结构和关键组件简介: 主要目录结构: assemblyline-base: 包含基础框架和通用功能。 assemblyline-core: 核心服务的实现,负责系统的业务逻辑处理。 ...

gitblog_00118的博客 1304

ETL第八章无人售货机零售项目实践

ETL实战项目——无人售货机

m0_52058217的博客 4420

华为 MetaERP 总账模块依托 “交易即核算” 的事件驱动架构,与 Oracle EBS 相比,更强调业务事件自动触发财务动作、实时数据同步和智能规则引擎,实现业务与财务的深度融合

华为MetaERP总账模块采用"交易即核算"架构,相比Oracle EBS实现了三大突破:1)业务事件自动触发财务动作,如采购收货自动生成暂估凭证;2)业务财务数据实时同步,支持即时分析;3)内置智能规则引擎,实现自动匹配、核销和结转。该模块覆盖采购、销售、资产、薪酬等全业务场景,支持多维核算和关联交易自动抵消,显著提升核算效率与准确性。其中采购暂估、销售结转等场景实现全自动化处理,较EBS减少80%手工操作。

金牌架构师 227

Assembly-Line scheduling------code in c++

#include #include #include using namespace std; int num_of_st; void getdata(vector & v, int n) { if (!v.empty()) throw runtime_error("v empty"); int t; for (int i = 0; i < n; ++i) { cin >> t

chriselp 1132

【即插即用模块】Transformer篇 | ICCV 2025 | MALA :注意力分布神似Softmax,告别线性注意力性能短板!

MALA(Magnitude-Aware Linear Attention)是一种改进的线性注意力机制,通过引入缩放因子和偏移项,解决了传统线性注意力忽视查询幅度的问题,使其分布更接近Softmax Attention。该模块具有线性复杂度(O(n)),结合RoPE和LEPE编码实现全局-局部位置信息混合,通过z值调制平衡信息权重。实验表明MALA在轻量级视觉任务中能有效平衡效率与精度,注意力可视化显示其分布与Softmax Attention高度相似。代码提供完整的RoPE位置编码和线性注意力

主要更新底层视觉(去噪、超分等)相关的科研内容,形式为【论文精读】+【论文复现】 1109

Jenkins集成fireline插件

1、Jenkins中选择“Manage Jenkins”——“Manage Plugins" 2、搜索”360 FireLine Plugin“并安装。 3、Jenkins新建简单工程。 4、配置工程。 源码管理中输入代码地址。 增加构建步骤”execute fireline“。 结果报告路径:生成报告位置 结果报告文件名:生成报告文件名 规则配置信息:扫描规则,重要。 5、构建。 ...

yyjbluesword的专栏 670

注意力机制篇 | YOLOv8改进之在C2f模块添加EMA注意力机制(附2种改进方法)

EMA(Exponential Moving Average)注意力机制是一种用于增强模型性能的注意力机制,它通过对模型的特征图进行加权平均来提取更有用的特征信息。具体来说,EMA注意力机制通过引入一个权重因子来调整特征图中每个位置的重要性,从而使模型能够更好地关注重要的特征。🌈

小哥谈 4181

TripoSR: Fast 3D Object Reconstruction from a Single Image 论文阅读

模型的主要参数,如变换器的层数、三平面的维度、NeRF模型的具体细节和主要训练配置,在表1中详细说明。TripoSR的算法流程结合了先进的数据处理、模型设计和训练技术,使其能够在不到0.5秒的时间内从单张图像中快速生成详细的3D网格。总体而言,TripoSR是一个强大的3D重建工具,它在速度和质量上都表现出色,但也需要考虑到其对计算资源的需求和在处理极端复杂场景时可能遇到的挑战。:通过精心策划的训练数据集和多样化的数据渲染技术,TripoSR提高了模型的泛化能力和对真实世界图像的适应性。

Christo的博客 1949

Vulkan 示例解析:pipelines.cpp 如何在一个 Render Pass 中切换多条 Graphics Pipeline

在 Vulkan 中,如果两个物体使用了不同的 shader,通常意味着它们需要不同的 graphics pipeline。如果两个物体使用了不同的 polygon mode,例如一个填充绘制、一个线框绘制,也通常意味着它们需要不同的 graphics pipeline。

wang的博客 470

沁恒CH32V208GBU6读写芯片内部FLASH:代码空间;使用OTA时候的代码空间;保存结构体到FLASH

沁恒CH32V208GBU6读写芯片内部FLASH:代码空间;使用OTA时候的代码空间;保存结构体到FLASH

cheng___yi的博客 556

【Pthreads】Pipeline Model(Assembly Line)示例

前言 Pthreads 有几种工作模型,例如 Boss/Workder Model、Pileline Model(Assembly Line)、Background Task Model、Interface/Implementation Model,详细介绍可以参考 pthread Tutorial,这里给出一个流水线模型(Pipeline Model)的简单示例。在该示例中,主线程开启...

weixin_30305735的博客 196

RK3588 部署 YOLOv5s 实战:多线程加速从 16FPS 飙升到 120FPS(含性能优化)

因为RK3588包含了3个NPU核心,支持3个核心同时工作、双核合作、以及单核工作。我们可以使用线程池来加速。线程池是一种长街的并发编程模型,它用于管理和复用线程,以提高多线程程序的性能和效率。线程池通常包含以下主要组件:1、任务队列:任务队列用于存储待执行的任务。这些任务可以是函数、方法或其他需要多线程环境中执行的操作。2、线程池管理:线程池管理器负责创建、销毁和管理线程。它会监视任务队列中的任务,根据需要创建线程,执行任务,并在任务完成后将线程放回池中以供重用。

FJN110的博客 100

汉书HE8,好用的汇编代码编写工具

汉书HE8,好用的汇编代码编写工具早期编写汇编代码所用功能强大

Drawing a triangle/Graphics pipeline basics/Fixed functions

Vulkan Tutorial 阅读记录(机翻)

J__yaoyao 的博客 470

贝叶斯统计 [韦来生编]

贝叶斯(Bayes)统计是近几十年来迅速发展起来的数理统计的一个重要分支。贝叶斯方法与经典统计方法的主要不同之处是进行统计推断时除了利用样本信息外,还要利用参数的先验信息,因此可以提高统计推断或统计决策的效果。它在经济、金融、生物、医学、自然科学和社会科学等许多领域具有广泛的应用。贝叶斯方法的研究已渗透到了统计学的几乎所有领域。作者在给中国科学技术大学概率论与数理统计专业本科生开设的“数理统计”课程中有一章专门讲授“贝叶斯方法和统计决策理论”,近十年来也给中国科学技术大学概率统计专业研究生开设过几次“贝叶斯分析”课。本书是在对过去讲稿的内容作了适当的增减和调整的基础上完成的。  本书共分六章。第1章是绪论,介绍了贝叶斯统计的若干基本概念,同时对必要的数理统计的基础知识有重点地作了回顾。第二章介绍了确定先验分布的若干可供选择的方法。第三章介绍了几类常见统计模型参数的后验分布的主要结果和计算方法。第四章和第五章分别介绍了“贝叶斯统计推断”和“贝叶斯统计决策”的内容。第六章介绍了贝叶斯统计计算的若干方法,包括蒙特卡洛方法和马尔可夫链蒙特卡洛(MCMC)方法以及相关统计软件的简介。本书的每一章附右大量的例题和习题,书末附有常用的几个表格和部分习题解答供读者查用。  大约可在54学时内讲授本书的第1章至第六章的主要内容,教师可根据学时需要选讲本书第1章至第六章的部分内容。书中标“*”号的章节可略去不讲,留给读者作为阅读材料。第六章例题中的R代码和部分例题的数据文件等可从作者个人主页下载。  作者在编写本书的过程中参考了J.O.Berger教授的《统计决策论及贝叶斯分析》和茆诗松教授编写的《贝叶斯统计》等书中的一些内容,以及《贝叶斯分析》一书中由张伟平博士编写的有关贝叶斯统计计算的一些内容。在此表示衷心感谢。  本书编写准备过程中,中国科学技术大学统计与金融系的几个研究生帮助完成了本书部分中文的录入和排版,作者对他们的辛勤工作表示真诚的感谢。高等教育出版社为本书的出版给予了大力支持。在此一并致谢。

vulakn教程--Drawing a Triangle--Pipeline--Fixed function

原文地址 : vulkan-tutorial Fixed functions 这一章节的内容大部分设计Pipeline中不可编程部分的配置。 Vertex input VkPipelineVertexInputStateCreateInfo 代表我们传递给Vertex Shader 顶点数据的格式,它涉及以下两个方面: 顶点数据的描述(Bindings) :数据间的间

lbknxy的专栏 1805

华为的C语言编程规范.pdf

华为技术有限公司内部技术规范。本规范制定了编写C语言程序的基本原则、规则和建议。从代码的清晰、简洁、可测试、安全、程序效率、可移植各个方面对C语言编程作出了具体指导。

ET2012新版免狗免安装绿色软件

ET2012新版免狗免安祖昂绿色软件。,新界面,新视觉,

Vulkan Samples 阅读 -- Performance(二): Occlusion Queries & Pipeline Statistics

目录Occlusion Queriespreparerendershader小结 Occlusion Queries prepare loadAssets: 加载模型(茶壶, 遮挡平面, 球) setupQueryPool vkCreateQueryPool: 创建一个查询池 prepareUniformBuffers createBuffer: Vertex shader, Teapot, Sphere updateUniformBuffers uboVS.visible = (passedS

jiamada的博客 549

Primitive Assembly, Clipping, and Rasterization

周一到周五,每天一篇,北京时间早上7点准时更新~,中英文对照,一边学编程一边弹吉他,做一个奇葩码农! After the front end of the pipeline has run (which includes vertex shading, tessellation, and geometry shading)(当前面提到的那些渲染管线阶段执行完毕后), a fixed-functi...

zgzammshi的专栏 536

[Vulkan教程]绘制一个三角形/图形管线基础/固定功能(Fixed functions)

固定功能

楚栋浩的博客 737

CANN/catlass单核Split-K矩阵乘法

The CATLASS [34_single_core_splitk_matmul sample](https://link.gitcode.com/i/9318bd2d5b4310a1522b1ec05e0df20a) is an Ascend-native Matmul operator implemented using the CATLASS Gemm API. It is optimiz

gitblog_00586的博客 929

cann/catlass昇腾算子模板库

--- ## ⚠ Important Changes At the first community meeting in March 2026, we officially confirmed that the CATLASS community mainline will add support for the next-generation Ascend hardware Ascend 9

gitblog_00678的博客 856

Vulkan入门(6)-创建管道的几个固定操作.md

文章目录参考资料简述一. Vertex input二. Input assembly三. Viewports and scissors3.1 Viewports3.2 Scissors3.3 使用方式四. Rasterizer (光栅化)五. Multisampling 多重采样六. Color blending 颜色混合6.1 VkPipelineColorBlendAttachmentState 结构6.2 VkPipelineColorBlendStateCreateInfo 全局颜色混合设置七. D

SwallowJoe的博客 1375

Vulkan教程 - 09 固定管线

固定管线 老式图形API为多数图形管线提供了默认状态。而在Vulkan中你必须明确所有的东西,从视口大小到混合函数。本章我们会填充所有的结构体来配置这些固定管线操作。 VkPipelineVertexInputStateCreateInfo结构体描述了将要传给顶点着色器的顶点数据的格式,它主要通过以下两种方式描述: 绑定:数据间的距离以及数据是否是逐顶点或者逐实例的; 属性描述:传给顶点着...

捉不住的鼬鼠的足迹 1940

Vulkan填坑学习Day11—固有功能

Vulkan 固有功能 Vulkan 固有功能,早期的图形API在图形渲染管线的许多阶段提供了默认的状态。在Vulkan中,从viewport的大小到混色函数,需要凡事做到亲历亲为。在本章节中我们会填充有关固有功能操作的所有结构体。 一、顶点输入 VkPipelineVertexInputStateCreateInfo结构体描述了顶点数据的格式,该结构体数据传递到vertex shader中。它以...

qq_35312463的博客 2139

在线GLB/GLTF编辑器核心技术解析:多选、反选与单物体导出实现

GLB和GLTF作为Web3D主流交付格式,其轻量级在线编辑能力长期缺失。理解GLTF文件结构是实现精准编辑的前提——它基于JSON描述场景树(nodes)、网格(meshes)、材质与二进制数据(buffers)的严格映射关系。真正可用的编辑器需突破浏览器限制,在保持PBR材质完整性与动画兼容性的前提下,支持Node粒度的可见性控制、材质实时调整及子集导出。技术价值在于将传统建模流程压缩为‘选中-修改-导出’三步,显著提升电商3D内容迭代、AR运营与前端协作效率。本文聚焦Three.js深度定制、GLTF

weixin_34014555的博客 500
上一篇: http://www.artima.com/wbc/interprogP.html
下一篇: Missed Signals : state-dependent in concurrent
FireCoder
博客等级 码龄17年 65粉丝 100原创
评论
成就一亿技术人!
拼手气红包6.0元
还能输入1000个字符
 
 条评论被折叠 查看
添加红包

请填写红包祝福语或标题

个

红包个数最小为10个

元

红包金额最低5元

当前余额3.43元 前往充值 >
需支付:10.00元
成就一亿技术人!
领取后你会自动成为博主和红包主的粉丝 规则
hope_wisdom
发出的红包

打赏作者

FireCoder

你的鼓励将是我创作的最大动力

¥1 ¥2 ¥4 ¥6 ¥10 ¥20
扫码支付:¥1
获取中
扫码支付

您的余额不足,请更换扫码支付或充值

打赏作者

实付元
使用余额支付
点击重新获取
扫码支付
钱包余额 0

抵扣说明:

1.余额是钱包充值的虚拟货币,按照1:1的比例进行支付金额的抵扣。
2.余额无法直接购买下载,可以购买VIP、付费专栏及课程。

余额充值