


第 37章 正则表达式(Regular Expressions)
目录
37.1 正则表达式(规范表达式)(Regular Expressions)
37.1.1 正则表达式相关符号(Regular Express Notation)
37.1 正则表达式(规范表达式)(Regular Expressions)
在 <regex> 中,标准库提供了正则表达式:
• regex_match():将正则表达式与已知长度的字符串进行匹配。
• regex_search():在任意长度的数据流中搜索与正则表达式匹配的字符串。
• regex_replace():在任意长度的数据流中搜索与正则表达式匹配的字符串并进行替换。
• regex_iterator:迭代匹配项和子匹配项。
• regex_token_iterator:迭代不匹配项。
regex_search() 的结果是匹配的集合,通常表示为 smatch:
void use()
{
ifstream in("file.txt"); // input file
if (!in) cerr << "no file\n";
regex pat {R"(\w{2}\s∗\d{5}(−\d{4})?)"}; // U.S. postal code pattern
int lineno = 0;
for (string line; getline(in,line);) {
++lineno;
smatch matches; // matched strings go here
if (regex_search(line , matches, pat)) {
cout << lineno << ": " << matches[0] << '\n'; // the complete match
if (1<matches.siz e() && matches[1].matched)
cout << "\t: " << matches[1] << '\n';// submatch
}
}
}
此函数读取一个文件,查找美国邮政编码,例如 TX77845 和 DC 20500-0001。smatch 类型是正则表达式结果的容器。其中,matches[0] 表示整个模式,matches[1] 表示可选的四位子模式。我使用了原始字符串(§7.3.2.1),它特别适合正则表达式,因为正则表达式通常包含大量反斜杠。如果我使用传统的字符串,则模式定义如下:
regex pat {"\\w{2}\\s∗\\d{5}(−\\d{4})?"}; // U.S. postal code pattern
正则表达式的语法和语义经过精心设计,以便能够将其编译成状态机,从而高效执行 [Cox,2007]。regex 类型在运行时执行此编译。
37.1.1 正则表达式相关符号(Regular Express Notation)
regex 库可以识别正则表达式的多种表示法变体(见第 37.2 节)。这里,我首先介绍默认使用的表示法,它是 ECMAScript(通常称为 JavaScript)中使用的 ECMA 标准的一种变体。
正则表达式的语法基于具有特殊意义的字符:
| 正则表达式特殊字符 | |
| . | 任意单字符(通配符(wildcard)) |
| [ | 字符类开始 |
| ] | 字符类结束 |
| { | 开始计数 |
| } | 结束计数 |
| ( | 分组开始 |
| ) | 分组结束 |
| \ | 下一个字符具有特别的意义(转义字符) |
| * | 0个或以上 |
| + | 1个或以上 |
| ? | 可选(0个或1个) |
| | | 替代对象(或运算) |
| ˆ | 匹配行之开始;取反操作 |
| $ | 匹配行之结束 |
例如,我们可以指定一行,以零个或多个 A 开头,后跟一个或多个 B,然后是一个可选的 C,如下所示:
ˆA∗B+C?$
匹配的例子:
AAAAAAAAAAAABBBBBBBBBC
BC
B
不匹配的例子:
AAAAA //无 B
AAAABC //开头出现空白
AABBCC //太多C
如果模式的一部分被括在括号中,则该部分被视为子模式(可以从 smatch 中单独提取)。
通过添加后缀,模式可以是可选的,也可以是重复的(默认是1次):
| 重复 | |
| { n } | 恰好 n 次 |
| { n, } | n或以上次数 |
| {n,m} | 至少n次且至多m次 |
| ∗ | 0或以上次数,即 { 0, } |
| + | 1或以上次数,即 { 1, } |
| ? | 可选(0次或1次),即 (0,1) |
例如:
A{3}B{2,4}C∗
匹配的例子:
AAABBC
AAABBB
不匹配的例子:
AABBC //太少A
AAABC //太少B
AAABBBBBCCC // 太多B
在任何重复符号后添加后缀 ? 会使模式匹配器变成“惰性(lazy)”或“非贪婪(non-greedy)”。也就是说,在查找模式时,它会查找最短匹配,而不是最长匹配。在默认情况下,模式匹配器始终查找最长匹配(类似于 C++ 的 Max Munch 规则;§10.3)。考虑:
ababab
模式 (ab)∗ 匹配所有 ababab。然而,(ab)∗? 只匹配第一个 ab。
最常见的字符分类有名称:
| 字符分类 | |
| alnum | 任意字母数字字符 |
| alpha | 任意字母字符 |
| blank | 任意非行分隔符的空白字符 |
| cntrl | 任意控制字符 |
| d | 任意十进制数 |
| digit | 任意十进制数 |
| graph | 任意图形字符 |
| lower | 任意小写字符 |
| | 任意可打印字符 |
| punct | 任何标点符号字符 |
| s | 任意空白字符 |
| space | 任意空白字符 |
| upper | 任意大写字符 |
| w | 任意词字符(字母数字字符加下划线) |
| xdigit | 何意16进制数字符 |
支持几种字条类缩写:
| 缩写的字符类 | ||
| \d | 一个十进制数 | [[:digit:]] |
| \s | 一个空白(空白,跳格,等等) | [[:space:]] |
| \w | 一个字母(a-z)或数字(0-9)或下划线(_) | [_[:alnum:]] |
| \D | 非 \d | [ˆ[:digit:]] |
| \S | 非 \s | [ˆ[:space:]] |
| \W | 非 \w | [ˆ_[:alnum:]] |
此外,支持正则表达式的语言通常提供:
| 非标准但(常用的)缩写字符类 | ||
| \l | 一个小写字符 | [[:lower:]] |
| \u | 一个大写字符 | [[:upper:]] |
| \L | 非 \l | [ˆ[:lower:]] |
| \U | 非 \u | [ˆ[:upper:]] |
为了实现完全可移植性,请使用字符类名称而不是这些缩写。
例如,考虑编写一个描述 C++ 标识符的模式:一个下划线或字母,后跟一个可能为空的字母、数字或下划线序列。为了说明其中的微妙之处,我列举了一些错误的尝试:
[:alpha:][:alnum:]∗ // 错: 来自集合“:alph”的字符,后跟...
[[:alpha:]][[:alnum:]]∗ // 错: 不接受下划线('_' 不是字母)
([[:alpha:]]|_)[[:alnum:]]∗ // 错: 下划线也不是 alnum 的一部分
([[:alpha:]]|_)([[:alnum:]]|_)∗ // 可, 但笨拙
[[:alpha:]_][[:alnum:]_]∗ // 可: 在字符类中包含下划线
[_[:alpha:]][_[:alnum:]]∗ // 也可
[_[:alpha:]]\w∗ // \w 等价于 [_[:alnum:]]
最后,这里有一个函数,它使用 regex_match() 的最简单版本(§37.3.1)来测试一个字符串是否是一个标识符:
bool is_identifier(const string& s)
{
regex pat {"[_[:alpha:]]\\w∗"};
return regex_match(s,pat);
}
注意,为了在普通字符串字面量(literal)中包含反斜杠,需要使用两个反斜杠。通常,反斜杠也可以表示特殊字符:
| 特殊字符(§iso.2.14.3, §6.2.3.2) | |
| \n | 换行 |
| \t | 跳格(制表符) |
| \\ | 一个反斜杠 |
| \xhh | 使用两个十六进制数字表示的 Unicode 字符 |
| \uhhhh | 使用四个十六进制数字表示的 Unicode 字符 |
为了增加混淆的机会,提供了反斜杠的另外两种逻辑上不同的用法:
| 特殊字符(§iso.28.5.2, §37.2.2) | |
| \b | 一个词的第一个或最后一个字符 |
| \B | 非 \b |
| \i | 按这种模式第 i 个sub_match |
使用原始字符串字面量(raw string literals)可以缓解许多特殊字符的问题。例如:
bool is_identifier(const string& s)
{
regex pat {R"([_[:alpha:]]\w∗)"};
return regex_match(s,pat);
}
以下是一些模式示例:
Ax∗ // A, Ax, Axxxx
Ax+ //Ax, Axxx Not A
\d−?\d //1-2, 12 Not 1--2
\w{2}−\d{4,5} // Ab-1234, XX-54321, 22-5432 Digits are in \w
(\d∗:)?(\d+) // 12:3, 1:23, 123, :123 Not 123:
(bs|BS) // bs, BS Not bS
[aeiouy] // a, o, u An English vowel, not x
[ˆaeiouy] // x, k Not an English vowel, not e
[aˆeiouy] // a, ˆ, o, u An English vowel or ˆ
一个可能由 sub_match 表示的group(一种子模式)由括号分隔。如果需要括号,但又不用于定义子模式,请使用 (? 而不是普通的 ( 。例如:
(\s|:|,)∗(\d∗) //后接一个数的空白, 冒号, 和/或 逗号
假设我们对数前的字符(可能是分隔符)不感兴趣,我们可以写为:
(?\s|:|,)∗(\d∗) //后接一个数的空白, 冒号, 和/或 逗号
这将使正则表达式引擎不必存储第一个字符:(? 变体只有一个子模式。
| 正则表达式分组示例 | |
| \d∗\s\w+ | 无分组(子模式) |
| (\d∗)\s(\w+) | 两个分组 |
| (\d∗)(\s(\w+))+ | 两个分组(分组不嵌套) |
| (\s∗\w∗)+ | 一个组,但包含一个或多个子模式; 只有最后一个子模式会保存为 sub_match |
| <(.∗?)>(.∗?)</\1> | 三个分组;\1 表示“与第 1 组相同” |
最后一个模式对于解析 XML 非常有用。它可以查找标签/标签结束标记。请注意,我使用了非贪婪匹配(惰性匹配),.∗? 作为标签和结束标签之间的子模式。如果我使用普通的 .∗,则此输入会导致问题:
Always look for the <b>bright</b> side of <b>life</b>.
对第一个子模式进行贪婪匹配会将第一个 < 与最后一个 > 匹配。对第二个子模式进行贪婪匹配会将第一个 <b> 与最后一个 </b> 匹配。这两种行为都是正确的,但不太可能是程序员想要的。
可以使用选项(§37.2)改变正则表达式符号的细节。例如,如果使用 regex_constants::grep,则 a?x:y 是一个由五个普通字符组成的序列,因为 ? 在 grep 中不表示“可选”。
有关正则表达式的更详尽介绍,请参阅 [Friedl,1997]。
37.2 regex
正则表达式是由字符序列(例如string)构成的匹配引擎(通常是状态机):
template<class C, class traits = regex_traits<C>>
class basic_regex {
public:
using value_type = C;
using traits_type = traits;
using string_type = typename traits::string_type;
using flag_type = regex_constants::syntax_option_type;
using locale_type = typename traits::locale_type;
˜basic_regex(); // not virtual; basic_regex is not meant to be used as a base class
// ...
};
regex_traits 见 §37.5 。
与string一样,regex是使用char版本的别名:
using regex = basic_regex<char>;
正则表达式模式的含义由 regex_constants 和 regex 中定义相同的 syntax_option_type 常量控制:
| basic_regex<C,Tr> 成员(syntax_option_type, §iso.28.5.1) | |
| icase | 匹配时不区分大小写 |
| nosubs | 匹配结果中不存储任何子表达式匹配 |
| optimize | 优先考虑快速匹配而不是快速正则表达式对象构造 |
| collate | 形式为 [a−b] 的字符范围是局部敏感的 |
| ECMAScript | 正则表达式语法是 ECMAScript 在 ECMA-262 中使用的语法(略有修改;§iso.28.13) |
| basic | 正则表达式语法是 POSIX 中基本正则表达式所使用的语法 |
| extended | 正则表达式语法是 POSIX 中的扩展正则表达式所使用的语法 |
| awk | 正则表达式语法是 POSIX awk 使用的语法 |
| grep | 正则表达式语法是 POSIX grep 使用的语法 |
| egrep | 正则表达式语法是 POSIX egrep 使用的语法 |
除非有充分的理由,否则请使用默认值。充分的理由包括大量现有的正则表达式都采用了非默认的表示法。
regex对象可以由string或类似的字符序列构造:
| basic_regex<C,Tr> 构造函数(§iso.28.8.2) | |
| basic_regex r {}; | 默认构造函数:一个空模式; 标志设置为 regex_constants::ECMAScript |
| basic_regex r {x,flags}; | x 可以是 basic_regex、string、C 风格字符串或一个带有 flags 定义的符号的 initializer_list<value_type>;explicit |
| basic_regex r {x}; | basic_regex{x,reg ex_constants::ECMAScript}; explicit |
| basic_regex r {p,n,flags}; | 使用 flags 定义的符号,从 [p:p+n) 中的字符构造 r |
| basic_regex r {p,n}; | basic_regex{p,n,reg ex_constants::ECMAScript} |
| basic_regex r {b,e ,flags} | 使用 flags 定义的符号,根据 [b:e) 中的字符构造 r |
| basic_regex r {b,e}; | basic_regex{b,e ,regex_constants::ECMAScript} |
regex的主要用途贯穿搜索、匹配和替换功能(§37.3),但正则表达式本身也有一些操作:
| basic_regex<C,Tr> 操作(§iso.28.8) | |
| r=x | 复制赋值:x 可以是 basic_regex,C风格字符串,basic_string ,或者initializer_list<value_type> |
| r=move(r2) | 移动赋值 |
| r=r.assign(r2) | 复制或移动 |
| r=r.assign(x,flags) | 复制或移动;将 r 的标志设置为标志 x 可以是 basic_string、C 样式字符串或 initializer_list<value_type> |
| r=r.assign(x) | r=r.assign(x,reg ex_constants::ECMAScript) |
| r=r.assign(p,n,flags) | 将 r 的模式设置为 [p:p+n),并将 r 的标志设置为 flags |
| r=r.assign(b,e ,flags) | 将r 的模式设置为 [b:e),将 r 的标志设置为 flags |
| r=r.assign(b,e) | r=r.assign(b,e ,regex_constants::ECMAScript) |
| n=r.mark_count() | n 是 r 中标记子表达式的数量 |
| x=r.flags() | x 是 r 的标志 |
| loc2=r.imbue(loc) | r 获取语言环境 loc;loc2 是 r 之前的语言环境 |
| loc=r.g etloc() | loc 是 r 的语言环境 |
| r.swap(r2) | 交换 r 和 r2 的值 |
你可以通过调用 getloc() 来确定locale或regex,并通过 flags() 了解所使用的标志,但遗憾的是,没有(标准)方法来读取其模式。如果您需要输出模式,请保留用于初始化的字符串的副本。例如:
regex pat1 {R"(\w+\d∗)"}; // 无法输出 pat1 中的模式
string s {R"(\w+\d∗)"};
regex pat2 {s};
cout << s << '\n'; // pat2 中的模式
37.2.1 匹配结果(Match Results)
正则表达式匹配的结果收集于 match_results 对象中,该对象包含一个或多个 sub_match 对象:
template<class Bi>
class sub_match : public pair<Bi,Bi> {
public:
using value_type = typename iterator_traits<Bi>::value_type;
using difference_type = typename iterator_traits<Bi>::difference_type;
using iterator = Bi;
using string_type = basic_string<value_type>;
bool matched; // true if *this contains a match
// ...
};
Bi 必须是双向迭代器 (§33.1.2)。sub_match 可以看作是一对迭代器,指向被匹配的字符串。
| sub_match<Bi> 操作 | |
| sub_match sm {}; | 默认构造函数:一个空序列;constexpr |
| n=sm.length() | n 是匹配的字符数 |
| s=sm | 将 sub_match 隐式转换为 basic_string;s 是包含匹配字符的 basic_string |
| s=sm.str() | s 是包含匹配字符的 basic_string |
| x=sm.compare(x) | 字典顺序比较:sm.str().compare(x); x 可以是 sub_match、basic_string 或 C 风格字符串 |
| x==y | x 等于 y 吗?x 和 y 可以是 sub_match 或 basic_string |
| x!=y | !(x==y) |
| x<y | x 按字典顺序位于y 之前 |
| x>y | y<x |
| x<=y | !(x>y) |
| x>=y | !(x<y) |
| sm.matched | 如果 sm 包含匹配项,则为 true;否则为 false |
例如:
regex pat ("<(.∗?)>(.∗?)</(.∗?)>");
string s = "Always look for the <b> bright </b> side of <b> death </b>";
if (regex_search(s1,m,p2))
if (m[1]==m[3]) cout << "match\n";
输出是 match 。
一个 match_results 是一个 sub_match 的容器:
template<class Bi, class A = allocator<sub_match<Bi>>
class match_results {
public:
using value_type = sub_match<Bi>;
using const_reference = const value_type&;
using reference = const_reference;
using const_iterator = /* implementation-defined */;
using iterator = const_iterator;
using difference_type = typename iterator_traits<Bi>::difference_type;
using size_type = typename allocator_traits<A>::size_type;
using allocator_type = A;
using char_type = typename iterator_traits<Bi>::value_type;
using string_type = basic_string<char_type>;
˜match_results(); // not virtual
// ...
};
Bi 必须是双向迭代器(§33.1.2)。
与 basic_string 和 basic_ostream 一样,为最常见的 match_results 提供了一些标准别名:
using cmatch = match_results<const char∗>; //C-style string
using wcmatch = match_results<const wchar_t∗>; //wide C-style string
using smatch = match_results<string::const_iterator>; // string
using wsmatch = match_results<wstring::const_iterator>; // wstring
match_results 提供对其匹配字符串、其 sub_matches 以及匹配前后的字符的访问:
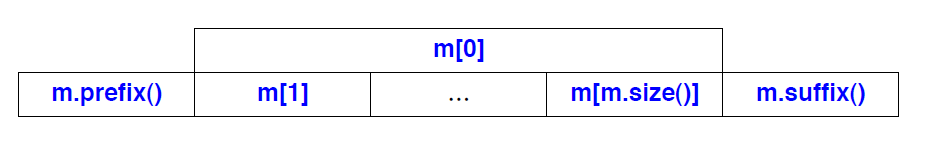
match_results 提供了一组常规操作:
| regex<C,Tr> 匹配和子匹配(§iso.28.9, §iso.28.10) | |
| match_results m {}; | 默认构造函数:使用 allocator_type{} |
| match_results m {a}; | 使用分配器a;explicit |
| match_results m {m2}; | 复制和移动构造函数 |
| m2=m | 复制赋值 |
| m2=move(m) | 移动赋值 |
| m.˜match_results() | 析构函数:释放所有资源 |
| m.ready() | m 是否完全匹配? |
| n=m.size() | n−1 是 m 中子表达式的数量;如果没有匹配,则 n==0 |
| n=m.max_size() | n 是 m 的最大可能的 sub_matches 数量 |
| m.empty() | m.size()==0? |
| r=m[i] | r 是 m 中第 i 个 sub_match 的常量引用; m[0] 表示完全匹配; 如果 i>= size(),则 m[i] 指向表示未匹配子表达式的 sub_match。 |
| n=m.length(i) | n=m[i].length();m[i]的字符个数 |
| n=m.length() | n=m.length(0) |
| pos=m.position(i) | pos=m[i].first;m[i]的第一个字符 |
| pos=m.position() | pos=position(0) |
| s=m.str(i) | s=m[i].str();m[i]的字符串表示 |
| s=m.str() | s=m.str(0) |
| sm=m.prefix() | sms 是一个 sub_match,表示输入字符串中匹配项之前未与 m 匹配的字符 |
| sm=m.suffix() | sms 一个 sub_match,表示输入字符串中匹配结果之后未与 m 匹配的字符 |
| p=m.begin() | p 指向 m 的第一个 sub_match |
| p=m.end() | p 指向 m 的最后一个子匹配项 |
| p=m.cbegin() | p 指向 m 的第一个 sub_match(const 迭代器) |
| p=m.cend() | p 指向 m 的最后一个子匹配项之后的子匹配项(const 迭代器) |
| a=m.get_allocator() | a 是 m 的分配器 |
| m.swap(m2) | 交换 m 和 m2 的状态 |
| m==m2 | m 和 m2 的 sub_matches 值是否相等? |
| m!=m2 | !(m==m2) |
我们可以通过对 regex_match 添加下标来访问sub_match,例如 m[i]。如果下标 i 指向一个不存在的sub_match,则 m[i] 的结果表示该sub_match不匹配。例如:
void test()
{
regex pat ("(AAAA)(BBB)?");
string s = "AAAA";
smatch m;
regex_search(s,m,pat);
cout << boolalpha;
cout << m[0].matched << '\n'; // true: we found a match
cout << m[1].matched << '\n'; // true: there was a first sub_match
cout << m[2].matched << '\n'; // false: no second sub_match
cout << m[3].matched << '\n'; // false: there couldn’t be a third sub_match for pat
}
37.2.2 格式化(Formatting)
在 regex_replace() 中,格式化是使用 format() 函数完成的:
| regex<C,Tr> 格式化(§iso.28.10.5) 格式由 match_flag_type 选项控制 | |
| out=m.format(out,b,e ,flags) | 将 [b:e) 复制到 out; 用 m 中的子匹配替换格式字符 |
| out=m.format(out,b,e) | out=m.format(out,b,e ,regex_constants::format_default) |
| out=m.format(out,fmt,flags) | out=m.format(out,begin(fmt),end(fmt),flags); fmt 可以是 basic_string 或 C 风格字符串 |
| out=m.format(out,fmt) | out=m.format(out,fmt,regex_constants::format_default) |
| s=m.format(fmt,flags) | 将 s 构造为 fmt 的副本; 用 m 中的子匹配替换格式字符; fmt 可以是 basic_string 或 C 风格字符串 |
| s=m.format(fmt) | s=m.format(fmt,reg ex_constants::format_default) |
格式可以包含格式字符:
| 格式替换符号 | |
| $& | 匹配 |
| $‘ | 前缀 |
| $’ | 后缀 |
| $i | 第i个子匹配,例如$1 |
| $ii | 第ii个子匹配,例如$12 |
| $$ | 不匹配,$字符 |
有关示例,请参阅§37.3.3。
format() 完成的格式化细节由一组选项(标志)控制:
| regex<C,Tr> 格式化操作(regex_constants::match_flag_type; §iso.28.5.2) | |
| format_default | 使用 ECMAScript(ECMA-262)规则(§iso.28.13) |
| format_sed | 使用 POSIX sed 符号 |
| format_no_copy | 仅复制匹配项 |
| format_first_only | 仅替换正则表达式的第一次出现 |
37.3 正则表达式函数
将正则表达式模式应用于数据的函数包括:regex_search()(用于在字符序列中搜索)、regex_match()(用于匹配固定长度的字符序列)以及regex_replace()(用于执行模式替换)。
匹配的细节由一组选项(标志)控制:
| regex<C,Tr> 匹配选项(regex_constants::match_flag_type; §iso.28.5.2) | |
| match_not_bol | 字符 ˆ 不被视为表示“行首” |
| match_not_eol | 字符 $ 不被视为表示“行尾” |
| match_not_bow | \b 与子序列 [first,first) 不匹配 |
| match_not_eow | \b 与子序列 [last,last) 不匹配 |
| match_any | 如果有多个匹配可能,则任何匹配都是可以接受的 |
| match_not_null | 不匹配空序列 |
| match_continuous | 仅匹配从first开始的子序列 |
| match_prev_avail | −−first 是有效的迭代器位置 |
37.3.1 regex_match()
要求得与已知长度的整个序列(例如一行文本)匹配的模式,请使用 regex_match():
| 正则表达式匹配(§iso.28.11.2) 匹配由match_flag_type 选项控制(§37.3) | |
| regex_match(b,e ,m,pat,flags) | 输入 [b:e) 是否与正则表达式模式 pat 匹配? 将结果放入 match_results m;使用选项标志 |
| regex_match(b,e ,m,pat) | regex_match(b,e ,m,pat,regex_constants::match_default) |
| regex_match(b,e ,pat,flags) | 输入 [b:e) 是否与正则表达式模式 pat 匹配?使用选项标志 |
| regex_match(b,e ,pat) | regex_match(b,e ,pat,regex_constants::match_default) |
| regex_match(x,m,pat,flags) | 输入 x 是否与正则表达式模式 pat 匹配? x 可以是 basic_string 或 C 语言风格的字符串; 将结果放入 match_results m 中;使用选项标志 |
| regex_match(x,m,pat) | regex_match(x,m,pat,regex_constants::match_default) |
| regex_match(x,pat,flags) | 输入 x 是否与正则表达式模式 pat 匹配? x 可以是 basic_string 或 C 语言风格的字符串;请使用选项标志 |
| regex_match(x,pat) | regex_match(x,pat,regex_constants::match_default) |
举个例子,考虑一个用于验证表格格式的简单程序。如果表格格式符合预期,程序会向 cout 写入“一切正常”;如果不符合预期,程序会向 cerr 写入错误消息。表格由一系列行组成,每行包含四个以制表符分隔的字段,但第一行(标题行)可能只有三个字段。例如:
Class-----------Boys---------------Girls----------------Total
1a----------------12------------------- 15 -------------------27
1b ---------------16 -------------------14 -------------------30
Total ------------28 -------------------29 -------------------57
这些数字应该在水平和垂直方向上相加。
程序读取标题行,然后对每一行进行求和,直到最后一行标记为“总计”:
int main()
{
ifstream in("table .txt"); // input file
if (!in) cerr << "no file\n";
string line; // input buffer
int lineno = 0;
regex header {R"(ˆ[\w ]+(\t[\w ]+)∗$)"}; //tab-separated words
regex row {R"(ˆ([\w ]+)(\t\d+)(\t\d+)(\t\d+)$)"}; // label followed by three tab-separated numbers
if (getline(in,line)) { // check and discard the header line
smatch matches;
if (!regex_match(line ,matches,header))
cerr << "no header\n";
}
int boys = 0; // running totals
int girls = 0;
while (getline(in,line)) {
++lineno;
smatch matches; //submatches go here
if (!regex_match(line ,matches,row))
cerr << "bad line: " << lineno << '\n';
int curr_boy = stoi(matches[2]); // for stoi() see §36.3.5
int curr_girl = stoi(matches[3]);
int curr_total = stoi(matches[4]);
if (curr_boy+curr_girl != curr_total) cerr << "bad row sum \n";
if (matches[1]=="Total") { // last line
if (curr_boy != boys) cerr << "boys do not add up\n";
if (curr_girl != girls) cerr << "girls do not add up\n";
cout << "all is well\n";
return 0;
}
boys += curr_boy;
girls += curr_girl;
}
cerr << "didn't find total line\n")
return 1;
}
37.3.2 regex_search()
要在序列的一部分(例如文件)中查找模式,请使用 regex_search():
| 正则表达式搜索(§iso.28.11.3) 匹配由match_flag_type 选项控制(§37.3) | |
| regex_search(b,e ,m,pat,flags) | 输入 [b:e) 是否包含正则表达式模式 pat 的匹配项?将结果放入 match_results m;使用选项标志 |
| regex_search (b,e ,m,pat) | regex_search(b,e ,m,regex_constants::match_default) |
| regex_search (b,e ,pat,flags) | 输入 [b:e) 是否包含正则表达式模式 pat 的匹配项?请使用选项标志 |
| regex_search (b,e ,pat) | regex_search(b,e ,pat,regex_constants::match_default) |
| regex_search (x,m,pat,flags) | 输入 x 是否包含正则表达式模式 pat 的匹配项? x 可以是 basic_string 或 C 语言风格的字符串; 将结果放入 match_results m 中;使用选项标志 |
| regex_search (x,m,pat) | regex_search(x,m,pat,regex_constants::match_default) |
| regex_search (x,pat,flags) | 输入 x 是否包含正则表达式模式 pat 的匹配项? x 可以是 basic_string 或 C 语言风格的字符串;请使用选项标志 |
| regex_search (x,pat) | regex_search(x,pat,regex_constants::match_default) |
例如,我可以像这样查找我的名字的一些更常见的拼写错误:
regex pat {"[Ss]tro?u?v?p?stra?o?u?p?b?"};
smatch m;
for (string s; cin>>s; )
if (regex_search(s,m,pat))
if (m[0]!="stroustrup" && m[0]!="Stroustrup" )
cout << "Found: " << m[0] << '\n';
给定合适的输入,这将输出 Stroustrup 的拼写错误,例如:
Found: strupstrup
Found: Strovstrup
Found: stroustrub
Found: Stroustrop
请注意,即使模式“隐藏”在其他字符中,regex_search() 也能找到它。例如,它会在 abstrustrubal 中找到 strustrub。如果你想将模式与输入字符串中的每一个字符匹配,请使用 regex_match (§37.3.1)。
37.3.3 regex_replace()
要对序列的一部分(例如文件)中的模式进行简单替换,请使用 regex_replace():
| 正则表达式替换(§iso.28.11.4) 匹配由match_flag_type 选项控制(§37.3) | |
| out=regex_replace(out,b,e ,pat,fmt,flags) | 将 [b:e) 复制到 out, 搜索正则表达式模式 pat; 当找到 pat 的匹配项时, 使用 fmt 格式将其复制到 out, 由 flags 控制; fmt 可以是 basic_string 或 C 风格字符串 |
| out=regex_replace(out,b,e ,pat,fmt) | out=reg ex_replace(out,b,e ,pat,fmt, regex_constants::match_defaults) |
| s=regex_replace(x,pat,fmt,flags) | 将 x 复制到 s,搜索正则表达式模式 pat; 当找到 pat 的匹配项时,使用 fmt 格式将其复制到 s,由标志控制; x 可以是 basic_string 或 C 风格的字符串; fmt 可以是 basic_string 或 C 风格的字符串 |
| s=regex_replace(x,pat,fmt) | s=regex_replace(x,pat,fmt, regex_constants::match_defaults) |
复制格式是使用regex的 format() (§37.2.2) 和 $ 前缀符号来完成的,例如,$& 表示匹配,$2 表示第二个子匹配。这里有一个小测试程序,它接受一个包含单词和数字对的字符串,并将它们输出为 {word,number},每行一个:
void test1()
{
string input {"x 1 y2 22 zaq 34567"};
regex pat {"(\w+)\s(\d+)"}; // word space number
string format {"{$1,$2}\n"};
cout << regex_replace(input,pat,format);
}
输出结果是:
{x,1}
{y2,22}
{zaq,34567}
请注意行首那些恼人的“虚假”空格。默认情况下,regex_match() 会将未匹配的字符复制到其输出中,因此 pat 未匹配的两个空格会被打印出来。
为了消除这些空格,我们可以使用 format_no_copy 选项(§37.2.2):
cout << regex_replace(input,pat,format,reg ex_constants::format_no_copy);
现在,我们得到:
{x,1}
{y2,22}
{zaq,34567}
子匹配不必按顺序输出:
void test2()
{
string input {"x 1 y 2 z 3"};
regex pat {"(\w)\s(\d+)"}; // word space number
string format {"$2: $1\n"};
cout << regex_replace(input,pat,format,reg ex_constants::format_no_copy);
}
我们得到:
1: x
22: y2
34567: zeq
37.4 正则表达式迭代器
regex_search() 函数允许我们在数据流中查找某个模式的单个匹配项。如果我们想查找并处理所有此类匹配项,该怎么办?如果数据被组织成易于识别的行或记录序列,我们可以迭代这些行或记录,并对每个行或记录使用 regex_match()。如果我们想对每个模式的匹配项执行简单的替换,可以使用 regex_replace()。如果我们想迭代字符序列,并对每个模式的匹配项执行操作,可以使用 regex_iterator。
37.4.1 regex_iterator
regex_iterator 是一个双向迭代器,当迭代的时候,它在序列中搜索下一个模式匹配项:
template<class Bi,
class C = typename iterator_traits<Bi>::value_type ,
class Tr = typename regex_traits<C>::type>
class regex_iterator {
public:
using regex_type = basic_regex<C,Tr>;
using value_type = match_results<Bi>;
using difference_type = ptrdiff_t;
using pointer = const value_type∗;
using reference = const value_type&;
using iterator_category = forward_iterator_tag;
// ...
}
regex_traits 在§37.5 中有描述。
提供了常用的别名集:
using cregex_iterator = regex_iterator<const char∗>;
using wcregex_iterator = regex_iterator<const wchar_t∗>;
using sregex_iterator = regex_iterator<string::const_iterator>;
using wsregex_iterator = regex_iterator<wstring::const_iterator>;
regex_iterator 提供了一组最小的迭代器操作:
| regex_iterator<Bi,C,Tr> (§iso.28.12.1) | |
| regex_iterator p {}; | p 是序列尾 |
| regex_iterator p {b,e,pat,flags); | 遍历 [b:e),使用选项标志寻找 pat 的匹配项 |
| regex_iterator p {b,e,pat); | p用{b,e,pat,regex_constants::match_default} 初始化 |
| regex_iterator p {q}; | 复制构造函数(无移动构造函数) |
| p=q | 赋值构造函数(无移动赋值函数) |
| p==q | p 是否指向与 q 相同的 sub_match? |
| p!=q | !(p==q) |
| c=∗p | c 是当前的 sub_match |
| x=p−>m | x=(∗p).m |
| ++p | 使p 指向p 模式的下一个出现位置 |
| q=p++ | q=p, 然后 ++p |
regex_iterator 是双向迭代器,因此我们不能直接在 istream 上进行迭代。
例如,我们可以输出string中所有以空格分隔的单词:
void test()
{
string input = "aa as; asd ++eˆasdf asdfg";
regex pat {R"(\s+(\w+))"};
for (sreg ex_iterator p(input.begin(),input.end(),pat); p!=sregex_iterator{}; ++p)
cout << (∗p)[1] << '\n';
}
输出:
as
asd
asdfg
注意,我们遗漏了第一个单词 aa,因为它前面没有空格。如果我们将模式简化为 R"((\ew+))",我们得到
aa
as
asd
e
asdf
asdfg
你不能通过 regex_iterator 进行写入,并且 regex_iterator{} 是唯一可能的序列尾。
37.4.2 regex_token_iterator
regex_token_iterator 是 regex_iterator 的适配器,它对找到的 match_results 的 sub_matches 进行迭代:
template<class Bi,
class C = typename iterator_traits<Bi>::value_type ,
class Tr = typename regex_traits<C>::type>
class regex_token_iterator {
public:
using regex_type = basic_regex<C,Tr>;
using value_type = sub_match<Bi>;
using difference_type = ptrdiff_t;
using pointer = const value_type∗;
using reference = const value_type&;
using iterator_category = forward_iterator_tag;
// ...
regex_traits 在§37.5 中有描述。
常用的别名集如下:
using cregex_token_iterator = regex_token_iterator<const char∗>;
using wcregex_token_iterator = regex_token_iterator<const wchar_t∗>;
using sregex_token_iterator = regex_token_iterator<string::const_iterator>;
using wsregex_token_iterator = regex_token_iterator<wstring::const_iterator>;
regex_token_iterator 提供了一组最小的迭代器操作:
| regex_token_iterator (§iso.28.12.2) | |
| regex_token_iterator p {}; | p是序列尾 |
| regex_token_iterator p {b,e,pat,x,flags}; | x 列出要包含在迭代中的 sub_matche 的索引,或者 0,表示“整个匹配”,或者 -1,表示“将每个未匹配的字符序列表示为 sub_match”; x 可以是 int、initializer_list<int>、constvector<int>& 或 const int (&sub_match)[N] |
| regex_token_iterator p {b,e,pat,x}; | p 初始化为 {b,e,pat,x,regex_constants::match_default} |
| regex_token_iterator p {b,e,pat}; | p 初始化为 {b,e,pat,0,regex_constants::match_default} |
| regex_token_iterator p {q}; | 复制构造函数(无移动构造函数) |
| p.˜regex_token_iterator() | 析构函数:释放所有资源 |
| p=q | 复制赋值(无移动赋值) |
| p==q | p 是否指向与 q 相同的 sub_match? |
| p!=q | !(p==q) |
| c=∗p | c 是当前的 sub_match |
| x=p−>m | x=(∗p).m |
| ++p | 让 p 指向 p 模式的下一个出现位置 |
| q=p++ | q=p,则 ++p |
x 参数列出了要包含在迭代中的sub_match。例如(迭代匹配项 1 和 3):
void test1()
{
string input {"aa::bb cc::dd ee::ff"};
regex pat {R"((\w+)([[:punct:]]+)(\w+)\s∗)"};
sregex_token_iterator end {};
for (sreg ex_token_iterator p{input.begin(),input.end(),pat,{1,3}}; p!=end; ++p)
cout << ∗p << '\n';
}
输出结果:
aa
bb
cc
dd
ee
ff
-1 选项基本上颠倒了报告匹配的策略,将每个不匹配的字符序列表示为一个 sub_match。这通常被称为 token 拆分(即将字符流拆分成 token),因为当你的模式匹配 token 分隔符时,选项 -1 会保留 token。例如:
void test2()
{
string s {"1,2 , 3 ,4,5, 6 7"}; // input
regex pat {R"(\s∗,\s∗)"}; //用逗号作分隔符
copy(sreg ex_token_iterator{s.begin(),s.end(),pat,−1)},
sregex_token_iterator{},
ostream_iterator<string>{cout,"\n"});
}
输出:
1
2
3
4
5
6 7
这可以使用显式循环等效地编写:
void test3()
{
sregex_token_iterator end{};
for (sreg ex_token_iterator p {s.begin(),s.end(),pat,−1}; p!=end; ++p)
cout << ∗p << '\n';
}
37.5 regex_traits
regex_traits<T> 表示regex实现者所需的字符类型、字符串类型和语言环境之间的对应关系:
template<class C>
struct regex_traits {
public:
using char_type = C;
using string_type = basic_string<char_type>;
using locale_type = locale;
using char_class_type = /* implementation-defined bitmask type */;
// ...
};
标准库提供了特化的 regex_traits<char> 和 regex_traits<wchar_t>。
| regex_traits<C>操作(§iso.28.7) | |
| regex_traits tr {}; | 创建默认的 regex_trait<C> |
| n=length(p) | n 是 C 风格字符串 p 中的字符数; n=char_traits<C>::length(); static |
| c2=tr.translate(c) | c2=c,即无操作 |
| c2=tr.translate_nocase(c) | use_facet<ctype<C>>(getloc()).tolower(c); §39.4.5 |
| s=tr.transform(b,e) | sis 是一个可用于与其他字符串进行比较的字符串[b:e);§39.4.1 |
| s=tr.transform_primary(b,e) | s 是一个字符串,可用于将 [b:e) 与其他字符串进行比较;忽略大小写;§39.4.1 |
| s=tr.lookup_collatename(b,e) | s 是排序元素的string名称(名为 [b:e)]或空字符串 |
| m=tr.lookup_classname(b,e ,ign) | m 是字符分类 [b:e) 的分类掩码的字符串名称; 如果 ign==true,则忽略大小写 |
| m=tr.lookup_classname(b,e) | m=tr.lookup_classname(b,e ,false) |
| tr.isctype(c,m) | c 是否被归类为 m ?m 是 class_type |
| i=tr.value(c,b) | iis 是 c 以 b 为底数表示的整数值; b 必须是 8、10 或 16 |
| loc2=tr.imbue(loc) | 将 tr 的本地化设置为 loc;loc2 是 tr 之前的本地化 |
| loc=tr.g etloc() | loc 是 tr 的本地化 |
转换用于生成字符串,以便在模式匹配实现中进行快速比较。
分类名称是 §37.1.1 中列出的字符分类之一,例如 alpha、s 和 xdigit。
37.6 建议
[1] 大多数常规正则表达式用法都使用 regex;§37.1。
[2] 正则表达式的表示法可以调整以符合各种标准;§37.1.1,§37.2。
[3] 默认的正则表达式表示法是 ECMAScript 的表示法;§37.1.1。
[4] 为了便于移植,请使用字符类表示法以避免使用非标准缩写;§37.1.1。
[5] 保持克制;正则表达式很容易变成只写语言;§37.1.1。
[6] 除了最简单的模式外,最好使用原始字符串字面量来表达所有模式;§37.1.1。
[7] 请注意, \i 允许你根据前一个子模式来表达子模式;§37.1.1。
[8] 使用 ? 使模式变得“惰性”; §37.1.1,§37.2.1。
[9] regex可以使用 ECMAScript、POSIX、awk、grep 和 egrep 表示法;§37.2。
[10] 保留模式字符串的副本,以备需要输出;§37.2。
[11] 使用 regex_search() 查找字符流,使用 regex_match() 查找固定布局;§37.3.2,§37.3.1。
内容来源:
<<The C++ Programming Language >> 第4版,作者 Bjarne Stroustrup


 469


 扫一扫


 被折叠的 条评论
为什么被折叠?
 到【灌水乐园】发言


