


(一)排序算法的稳定性及其汇总
1.稳定性
同样值的个体之间,如果不因为排序而改变相对次序,就是这个排序是有稳定性的;否则就没有。例如:
原数组[2,1,2,1,3,2,3,2],排完序后变成新数组[1,1,2,2,2,2,3,3],要保持稳定性,是指原数组中的第一个“1”和第二个“1”在排完序后是否能够对应新数组中的第一个“1”和第二个“1”,同样的,2和3以此类推。
对于基础数据类型来说,稳定性没有用处。但对于非基础数据类型来说,稳定性有作用。
例如:一些班级里有一批学生,每个学生有class和age属性,第一次排序的时候,按照age从小到大排序;第二次排序的时候,按照class排序。如果两轮排序之后,同一个班级内部的学生是按照age从小到大排序的,那么这个排序称为“稳定的排序”。
2.不具备稳定性的排序
选择排序、快速排序、堆排序
(1)选择排序
举例:[3,3,3,3,3,1,3,3,3,3,3],对应序列编号{a1,a2,a3,a3,a4,a5,a6,a7,a8,a9,a10,a11},在选择排序后,变成[1,3,3,3,3,3,3,3,3,3,3],对应序列编号{a6,a2,a3,a3,a4,a5,a1,a7,a8,a9,a10,a11},原来的序列被打断,没有做到有序,故不稳定。
(2)快速排序
举例:[6{a},7,6{b},6{c},3,5],以5为划分值。
划分过程中,6{a}>5,会和后面的3发生远距离交换,
数组变为[3,7,6{b},6{c},6{a},5]。
原来三个6的顺序为:
6{a}→6{b}→6{c}
交换后变为:
6{b}→6{c}→6{a}
相同元素的相对顺序被破坏,故快速排序不稳定。
(3)堆排序
举例:[5,4{a},4{b},6]。
建立大根堆时,当6插入到4{a}下面:
5
/ \
4{a} 4{b}
/
6
因为6>4{a},交换:
5
/ \
6 4{b}
/
4{a}
继续6>5,再交换:
6
/ \
5 4{b}
/
4{a}
原来的4顺序为:
4{a} → 4{b}
堆调整过程中变为:
4{b} → 4{a}
继续完成堆排序后可得到:
[4{b},4{a},5,6]
相同的4相对次序发生改变,故堆排序不稳定。
3.具备稳定性的排序
冒泡排序、插入排序、归并排序、一切桶排序思想下的排序
(1)冒泡排序
举例:[6,5,4,5,3,4,6],对应序列{0,1,2,3,4,5,6},一轮排序后变成[5,4,5,3,4,6,6],原序列的6{0}和6{6}的序列不变。
(2)插入排序
举例:[3,2,2]对应{0,1,2},一轮排序后变成[2,2,3],对应序列{1,2,0},2的序列不变。
(3)归并排序
举例:[3,2,4,2],对应序列{0,1,2,3}。
拆分并分别排序后得到:
[2{1},3] 和 [2{3},4]。
merge时,两个2相等,因为相等时优先拷贝左侧元素,
所以最终得到:
[2{1},2{3},3,4],
对应序列{1,3,0,2}。
两个2原来的相对次序没有改变,故归并排序稳定。
4.排序的时空复杂度和稳定性总结
| 时间复杂度 | 空间复杂度 | 稳定性 | |
| 选择 | O(N^2) | O(1) | × |
| 冒泡 | O(N^2) | O(1) | √ |
| 插入 | O(N^2) | O(1) | √ |
| 归并 | O(N*logN) | O(N) | √ |
| 快排(随机) | O(N*logN) | O(logN) | × |
| 堆 | O(N*logN) | O(1) | × |
目前没有找到时间复杂度O(N*logN),额外空间复杂度O(1),又稳定的排序。
常见的坑
(1),归并排序的额外空间复杂度可以变成O(1),但是非常难且变完之后不再稳定,不需要掌握,有兴趣可以搜“归并排序 内部缓存法”
(2),“原地归并排序”的帖子都是垃圾,会让归并排序的时间复杂度变成O(N^2)
(3),快速排序可以做到稳定性问题,但是非常难但是空间复杂度会变成O(N),不需要掌握,可以搜“01 stable sort”
(4),所有的改进都不重要,因为目前没有找到时间复杂度O(N*logN),额外空间复杂度O(1),又稳定的排序。
(5),有一道题目,是否奇数放在数组左边,偶数放在数组右边,还要求原始的相对次序不变,碰到这个问题,可以怼面试官。这道题本质上是“01 stable sort”问题: 奇数映射成0,偶数映射成1,对0和1做稳定排序。 若允许O(N)额外空间,可以O(N)时间轻松实现; 若进一步要求O(1)额外空间并保持稳定,则实现非常困难, 属于01 stable sort / stable partition问题。
工程上对排序的改进
(1)充分利用O(N*logN)和O(^2)排序各自的优势(综合排序)
| 样本量 | 调度 | 复杂度 |
| 大样本 | 快排 | O(N*logN) |
| 小样本 | 插入 | O(N^2) |
示例代码
package class004;

import java.util.Arrays;

public class Test {

    // 对整个数组排序
    public static void quickSort(int[] arr) {
        if (arr == null || arr.length < 2) {
            return;
        }
        quickSort(arr, 0, arr.length - 1);
    }

    public static void quickSort(int[] arr, int l, int r) {
        // 空区间或只有一个数
        if (l >= r) {
            return;
        }

        // 小样本使用插入排序
        // O(N^2)虽然复杂度高,但N很小时常数项小,实际跑得快
        if (r - l + 1 <= 60) {
            insertionSort(arr, l, r);
            return;
        }

        // 随机选择一个数,与最后位置交换
        swap(arr,
                l + (int) (Math.random() * (r - l + 1)),
                r);

        // 荷兰国旗划分
        int[] p = partition(arr, l, r);

        // <区继续排序
        quickSort(arr, l, p[0] - 1);

        // >区继续排序
        quickSort(arr, p[1] + 1, r);
    }

    // 对arr[L...R]进行插入排序
    public static void insertionSort(int[] arr, int L, int R) {
        for (int i = L + 1; i <= R; i++) {
            for (int j = i - 1;
                 j >= L && arr[j] > arr[j + 1];
                 j--) {
                swap(arr, j, j + 1);
            }
        }
    }

    /*
     * 处理arr[L...R]
     * 默认以arr[R]作为划分值p
     *
     * 最终:
     *
     * < p | == p | > p
     *
     * 返回等于区域:
     * [左边界, 右边界]
     */
    public static int[] partition(int[] arr, int L, int R) {

        int less = L - 1; // <区右边界
        int more = R;     // >区左边界

        // L同时作为当前遍历位置
        while (L < more) {

            // 当前数 < 划分值
            if (arr[L] < arr[R]) {
                swap(arr, ++less, L++);

                // 当前数 > 划分值
            } else if (arr[L] > arr[R]) {
                swap(arr, --more, L);

                // 当前数 == 划分值
            } else {
                L++;
            }
        }

        // 把最后位置的划分值放入等于区
        swap(arr, more, R);

        // 等于区:[less+1, more]
        return new int[]{less + 1, more};
    }

    public static void swap(int[] arr, int i, int j) {
        int tmp = arr[i];
        arr[i] = arr[j];
        arr[j] = tmp;
    }

    public static void main(String[] args) {

        // 测试1:普通数组
        int[] arr1 = {
                11, 43, 32, 12, 24,
                6, 3, 8, 1, 7
        };

        System.out.println("排序前:" + Arrays.toString(arr1));
        quickSort(arr1);
        System.out.println("排序后:" + Arrays.toString(arr1));

        System.out.println("--------------------");

        // 测试2:有重复值
        int[] arr2 = {
                5, 3, 7, 3, 9, 5, 2, 5, 1, 3
        };

        System.out.println("排序前:" + Arrays.toString(arr2));
        quickSort(arr2);
        System.out.println("排序后:" + Arrays.toString(arr2));

        System.out.println("--------------------");

        // 测试3:倒序数组
        int[] arr3 = {
                10, 9, 8, 7, 6, 5, 4, 3, 2, 1
        };

        System.out.println("排序前:" + Arrays.toString(arr3));
        quickSort(arr3);
        System.out.println("排序后:" + Arrays.toString(arr3));

        System.out.println("--------------------");

        // 测试4:超过60个元素,真正测试“快排+插入排序”
        int[] arr4 = new int[100];

        for (int i = 0; i < arr4.length; i++) {
            arr4[i] = (int) (Math.random() * 100);
        }

        System.out.println("排序前:" + Arrays.toString(arr4));
        quickSort(arr4);
        System.out.println("排序后:" + Arrays.toString(arr4));
    }
}
运行结果:
排序前:[11, 43, 32, 12, 24, 6, 3, 8, 1, 7]
排序后:[1, 3, 6, 7, 8, 11, 12, 24, 32, 43]
--------------------
排序前:[5, 3, 7, 3, 9, 5, 2, 5, 1, 3]
排序后:[1, 2, 3, 3, 3, 5, 5, 5, 7, 9]
--------------------
排序前:[10, 9, 8, 7, 6, 5, 4, 3, 2, 1]
排序后:[1, 2, 3, 4, 5, 6, 7, 8, 9, 10]
--------------------
排序前:[61, 43, 77, 33, 60, 67, 77, 48, 99, 50, 8, 18, 6, 95, 86, 3, 77, 61, 17, 98, 87, 71, 78, 0, 16, 66, 53, 48, 32, 47, 57, 83, 87, 35, 89, 27, 58, 66, 33, 42, 18, 37, 91, 7, 84, 17, 77, 58, 77, 25, 93, 74, 27, 15, 51, 99, 57, 63, 16, 96, 86, 17, 60, 84, 47, 38, 0, 9, 34, 11, 14, 48, 27, 0, 42, 65, 69, 55, 89, 91, 59, 11, 50, 23, 79, 32, 39, 94, 44, 94, 59, 98, 52, 49, 81, 28, 70, 13, 74, 93]
排序后:[0, 0, 0, 3, 6, 7, 8, 9, 11, 11, 13, 14, 15, 16, 16, 17, 17, 17, 18, 18, 23, 25, 27, 27, 27, 28, 32, 32, 33, 33, 34, 35, 37, 38, 39, 42, 42, 43, 44, 47, 47, 48, 48, 48, 49, 50, 50, 51, 52, 53, 55, 57, 57, 58, 58, 59, 59, 60, 60, 61, 61, 63, 65, 66, 66, 67, 69, 70, 71, 74, 74, 77, 77, 77, 77, 77, 78, 79, 81, 83, 84, 84, 86, 86, 87, 87, 89, 89, 91, 91, 93, 93, 94, 94, 95, 96, 98, 98, 99, 99]
实测时间消耗(以60为划分):
package class004;

import java.util.Arrays;

public class Test01 {

    // =========================
    // 调整前:纯快速排序
    // =========================
    public static void quickSortBefore(int[] arr) {
        if (arr == null || arr.length < 2) {
            return;
        }
        quickSortBefore(arr, 0, arr.length - 1);
    }

    public static void quickSortBefore(int[] arr, int l, int r) {
        if (l >= r) {
            return;
        }

        // 不做小样本优化
        // 所有区间一直使用快速排序
        swap(arr,
                l + (int) (Math.random() * (r - l + 1)),
                r);

        int[] p = partition(arr, l, r);

        quickSortBefore(arr, l, p[0] - 1);
        quickSortBefore(arr, p[1] + 1, r);
    }


    // =========================
    // 调整后:快排 + 插入排序
    // =========================
    public static void quickSortAfter(int[] arr) {
        if (arr == null || arr.length < 2) {
            return;
        }
        quickSortAfter(arr, 0, arr.length - 1);
    }

    public static void quickSortAfter(int[] arr, int l, int r) {
        if (l >= r) {
            return;
        }

        // 小样本直接使用插入排序
        if (r - l + 1 <= 60) {
            insertionSort(arr, l, r);
            return;
        }

        swap(arr,
                l + (int) (Math.random() * (r - l + 1)),
                r);

        int[] p = partition(arr, l, r);

        quickSortAfter(arr, l, p[0] - 1);
        quickSortAfter(arr, p[1] + 1, r);
    }


    // 对arr[L...R]进行插入排序
    public static void insertionSort(int[] arr, int L, int R) {
        for (int i = L + 1; i <= R; i++) {
            for (int j = i - 1;
                 j >= L && arr[j] > arr[j + 1];
                 j--) {
                swap(arr, j, j + 1);
            }
        }
    }


    // 荷兰国旗划分
    public static int[] partition(int[] arr, int L, int R) {
        int less = L - 1;
        int more = R;

        while (L < more) {
            if (arr[L] < arr[R]) {
                swap(arr, ++less, L++);
            } else if (arr[L] > arr[R]) {
                swap(arr, --more, L);
            } else {
                L++;
            }
        }

        swap(arr, more, R);

        return new int[]{less + 1, more};
    }


    public static void swap(int[] arr, int i, int j) {
        int tmp = arr[i];
        arr[i] = arr[j];
        arr[j] = tmp;
    }


    public static void main(String[] args) {
        // =========================
        // 测试4:调整前 VS 调整后
        // =========================

        int size = 100000;

        // 生成原始随机数组
        int[] arr4 = new int[size];

        for (int i = 0; i < arr4.length; i++) {
            arr4[i] = (int) (Math.random() * 100000);
        }

        // 必须复制两份完全相同的数据
        // 保证两种算法处理的是同一个数组
        int[] arr4Before = Arrays.copyOf(arr4, arr4.length);
        int[] arr4After = Arrays.copyOf(arr4, arr4.length);


        // =========================
        // 调整前:纯快速排序
        // =========================

        long start1 = System.nanoTime();

        quickSortBefore(arr4Before);

        long end1 = System.nanoTime();

        long timeBefore = end1 - start1;


        // =========================
        // 调整后:快排 + 插入排序
        // =========================

        long start2 = System.nanoTime();

        quickSortAfter(arr4After);

        long end2 = System.nanoTime();

        long timeAfter = end2 - start2;


        // =========================
        // 打印结果
        // =========================

        System.out.println("测试数据量:" + size);

        System.out.println(
                "调整前(纯快速排序)耗时:" +
                        timeBefore / 1_000_000.0 +
                        " ms"
        );

        System.out.println(
                "调整后(快排+插入排序)耗时:" +
                        timeAfter / 1_000_000.0 +
                        " ms"
        );

        System.out.println(
                "两种排序结果是否一致:" +
                        Arrays.equals(arr4Before, arr4After)
        );
    }
}
时间消耗(以60为划分,测试数据量达到100000):
第一次:

测试数据量:100000
调整前(纯快速排序)耗时:9.4522 ms
调整后(快排+插入排序)耗时:7.222 ms
两种排序结果是否一致:true

第二次:
测试数据量:100000
调整前(纯快速排序)耗时:8.8005 ms
调整后(快排+插入排序)耗时:6.7178 ms
两种排序结果是否一致:true
时间消耗(以20为划分,测试数据量达到1000000):
第一次:

测试数据量:1000000
调整前(纯快速排序)耗时:66.0448 ms
调整后(快排+插入排序)耗时:63.305 ms
两种排序结果是否一致:true

第二次:

测试数据量:1000000
调整前(纯快速排序)耗时:60.3482 ms
调整后(快排+插入排序)耗时:57.6581 ms
两种排序结果是否一致:true
时间消耗(以60为划分,测试数据量达到10000000):
第一次

测试数据量:10000000
调整前(纯快速排序)耗时:553.9916 ms
调整后(快排+插入排序)耗时:539.2518 ms
两种排序结果是否一致:true

第二次

测试数据量:10000000
调整前(纯快速排序)耗时:626.0049 ms
调整后(快排+插入排序)耗时:548.3475 ms
两种排序结果是否一致:true
时间消耗(以20为划分):
通过以上测试我们知道,以60为划分,在测试数据量达到100000时,调整后平均能够节约2ms;以20为划分,在测试数据量达到1000000时,调整后平均能够节约3ms;以30为划分,在测试数据量达到10000000时,调整后平均能够节约10ms以上。
(2)稳定性的考虑
面试问题:为什么在对基础类型进行排序时,采用快速排序;在面对非基础类型的数据时,采用归并排序?原因:稳定性的需要。
Java 底层排序同样采用综合排序思想。以 Arrays.sort(int[]) 为例,主要采用 Dual-Pivot Quicksort,但小规模区间会切换到插入排序等方法;当快速排序出现恶化风险时还可以使用堆排序兜底。因此工程中的排序通常不是单一算法,而是根据样本规模和数据特征动态选择算法。
(二)链表
1.哈希表的简单介绍
1)哈希表在使用层面上可以理解为一种集合结构
2)如果只有key,没有伴随数据value,可以使用HashSet结构(C++中叫UnOrderedSet)
3)如果既有key,又有伴随数据value,可以使用HashMap结构(C++中叫UnOrderedMap)
4)有无伴随数据,是HashMap和HashSet唯一的区别,底层的实际结构是一回事
5)使用哈希表增(put)、删(remove)、改(put)和查(get)的操作,可以认为时间复杂度为O(1),但是常数时间比较大
6)放入哈希表的东西,如果是基础类型,内部按值传递,内存占用就是这个东西的大小
7)放入哈希表的东西,如果不是基础类型,内部按引用传递,内存占用是这个东西内存地址的大小(一律只占八字节,和内存占用大小没有关系)
有关哈希表的原理,将在提升班“与哈希函数有关的数据结构”一章中讲叙原理。
2.有序表的简单介绍
1)有序表在使用层面上可以理解为一种集合结构
2)如果只有key,没有伴随数据value,可以使用TreeSet结构(C++中叫OrderedSet)
3)如果既有key,又有伴随数据value,可以使用TreeMap结构(C++中叫OrderedMap)
4)有无伴随数据,是TreeSet和TreeMap唯一的区别,底层的实际结构是一回事
5)有序表和哈希表的区别是,有序表把key按照顺序组织起来,而哈希表完全不组织
6)红黑树、AVL树、size-balance-tree和跳表等都属于有序表结构,只是底层具体实现不同
7)放入哈希表的东西,如果是基础类型,内部按值传递,内存占用就是这个东西的大小
8)放入哈希表的东西,如果不是基础类型,必须提供比较器,内部按引用传递,内存占用是这个东西内存地址的大小
9)不管是什么底层具体实现,只要是有序表,都有以下固定的基本功能和固定的时间复杂度
3.有序表的固定操作
1)void put(K key, V value):将一个(key,value)记录加入到表中,或者将key的记录更新成value。
2)V get(K key):根据给定的key,查询value并返回。
3)void remove(K key):移除key的记录。
4)boolean containsKey(K key):询问是否有关于key的记录。
5)K firstKey():返回所有键值的排序结果中,最左(最小)的那个。
6)K lastKey():返回所有键值的排序结果中,最右(最大)的那个。
7)K floorKey(K key):如果表中存入过key,返回key;否则返回所有键值的排序结果中,key的前一个。
8)K ceilingKey(K key):如果表中存入过key,返回key;否则返回所有键值的排序结果中,key的后一个。
以上所有操作时间复杂度都是O(logN),N为有序表含有的记录数
有关有序表的原理,将在提升班“有序表详解”一章中讲叙原理。
哈希表,有序表相关代码:
package class004;

import java.awt.*;
import java.util.*;

public class Code_HashAndTree {

    public static class Node{
        public int value;
        public Node next;

        public Node(int val){
            value=val;
        }
    }
    public static class NodeComparator implements Comparator<Node>{
        @Override
        public int compare(Node o1,Node o2){
            return o1.value-o2.value;
        }
    }
    public static void main(String[] args){
        Node nodeA=null;
        Node nodeB=null;
        Node nodeC=null;

        //UnOrderedMap,UnSortedMap,UnOrderedSet,UnSortedSet ->C++
        //hashSet1的key是基础类型-》int类型
        HashSet<Integer>hashSet1=new HashSet<>();
        hashSet1.add(3);
        System.out.println(hashSet1.contains(3));
        hashSet1.remove(3);
        System.out.println(hashSet1.contains(3));

        HashMap<Integer,String>mapTest=new HashMap<>();

        mapTest.put(1,"zuo");
        mapTest.put(1,"cheng");
        mapTest.put(2,"2");

        System.out.println(mapTest.containsKey(1));
        System.out.println(mapTest.get(1));
        System.out.println(mapTest.get(4));

        mapTest.remove(2);
        System.out.println(mapTest.get(2));

        System.out.println("===========1==========");

        //hashSet2的key是非基础类型->Node类型
        nodeA=new Node(1);
        nodeB=new Node(1);
        HashSet<Node>hashSet2=new HashSet<>();
        hashSet2.add(nodeA);
        System.out.println(hashSet2.contains(nodeA));
        System.out.println(hashSet2.contains(nodeB));
        hashSet2.remove(nodeA);
        System.out.println(hashSet2.contains(nodeA));
        System.out.println("===========2==========");

        //hashMap1的key是基础类型-》String类型
        HashMap<String,Integer>hashMap1=new HashMap<>();
        String str1="key";
        String str2="key";
        hashMap1.put(str1,1);
        System.out.println(hashMap1.containsKey(str1));
        System.out.println(hashMap1.containsKey(str2));
        System.out.println(hashMap1.get(str1));
        System.out.println(hashMap1.get(str2));

        hashMap1.put(str2,2);
        System.out.println(hashMap1.containsKey(str1));
        System.out.println(hashMap1.containsKey(str2));
        System.out.println(hashMap1.get(str1));
        System.out.println(hashMap1.get(str2));

        hashMap1.remove(str1);
        System.out.println(hashMap1.containsKey(str1));
        System.out.println(hashMap1.containsKey(str2));
        System.out.println("===========3==========");

        //hashMap2的key是非基础类型-》Node类型
        nodeA=new Node(1);
        nodeB=new Node(1);
        HashMap<Node,String>hashMap2=new HashMap<>();
        hashMap2.put(nodeA,"A节点");
        System.out.println(hashMap2.containsKey(nodeA));
        System.out.println(hashMap2.containsKey(nodeB));
        System.out.println(hashMap2.get(nodeA));
        System.out.println(hashMap2.get(nodeB));
        hashMap2.put(nodeB,"B节点");
        System.out.println(hashMap2.containsKey(nodeA));
        System.out.println(hashMap2.containsKey(nodeB));
        System.out.println(hashMap2.get(nodeA));
        System.out.println(hashMap2.get(nodeB));
        System.out.println("===========4==========");

        //treeSet的key是非基础类型-》Node类型
        nodeA=new Node(5);
        nodeB=new Node(3);
        nodeC=new Node(7);

        TreeSet<Node>treeSet=new TreeSet<>();//红黑树
        //以下代码会报错,因为没有提供Node类型的比较器
        try{
            treeSet.add(nodeA);
            treeSet.add(nodeB);
            treeSet.add(nodeC);
        }catch (Exception e){
            System.out.println("错误信息:"+e.getMessage());
        }
        treeSet=new TreeSet<>(new NodeComparator());
        //以下代码没问题,因为提供了Node类型的比较器
        try{
            treeSet.add(nodeA);
            treeSet.add(nodeB);
            treeSet.add(nodeC);
            System.out.println("这次节点都加入了");
        }catch (Exception e){
            System.out.println("错误信息:"+e.getMessage());
        }
        System.out.println("===========5==========");

        //展示有序表常用操作,性能O(logN)级别
        TreeMap<Integer,String>treeMap1=new TreeMap<>();
        treeMap1.put(7,"我是7");
        treeMap1.put(5,"我是5");
        treeMap1.put(4,"我是4");
        treeMap1.put(3,"我是3");
        treeMap1.put(9,"我是9");
        treeMap1.put(2,"我是2");
        System.out.println(treeMap1.containsKey(5));
        System.out.println(treeMap1.get(5));
        System.out.println(treeMap1.firstKey()+",我最小");
        System.out.println(treeMap1.lastKey()+",我最大");
        System.out.println(treeMap1.floorKey(8)+",在表中所有<=8的数中,我离8最近");
        System.out.println(treeMap1.ceilingKey(8)+",在表中所有>=8的数中,我离8最近");
        System.out.println(treeMap1.floorKey(7)+",在表中所有<=7的数中,我离7最近");
        System.out.println(treeMap1.ceilingKey(7)+",在表中所有>=7的数中,我离7最近");
        treeMap1.remove(5);
        System.out.println(treeMap1.get(5)+",删了就没有了哦");
        System.out.println("===========6==========");
    }
}
运行结果:
true
false
true
cheng
null
null
===========1==========
true
false
false
===========2==========
true
true
1
1
true
true
2
2
false
false
===========3==========
true
false
A节点
null
true
true
A节点
B节点
===========4==========
错误信息:class class004.Code_HashAndTree$Node cannot be cast to class java.lang.Comparable (class004.Code_HashAndTree$Node is in unnamed module of loader 'app'; java.lang.Comparable is in module java.base of loader 'bootstrap')
这次节点都加入了
===========5==========
true
我是5
2,我最小
9,我最大
7,在表中所有<=8的数中,我离8最近
9,在表中所有>=8的数中,我离8最近
7,在表中所有<=7的数中,我离7最近
7,在表中所有>=7的数中,我离7最近
null,删了就没有了哦
===========6==========
4.单链表的节点结构
Class Node<V>{
    V value;
    Node next;
}
由以上结构的节点依次连接起来所形成的链叫单链表结构。
双链表的节点结构
Class Node<V>{
    V value;
    Node next;
    Node last;
}
由以上结构的节点依次连接起来所形成的链叫双链表结构。
单链表和双链表结构只需要给定一个头部节点head,就可以找到剩下的所有的节点。
5.反转单向和双向链表
【题目】分别实现反转单向链表和反转双向链表的函数
【要求】如果链表长度为N,时间复杂度要求为O(N),额外空间复杂度要求为O(1)
分析:反转单向链表的方法是逆序,node1->node2->node3,变成node3->node2-node1,双向链表同样如此。注意:如果反转操作会导致 head 改变,就需要把新的头节点返回。如果不需要返回任何结果,可以定义成 void。
流程图:
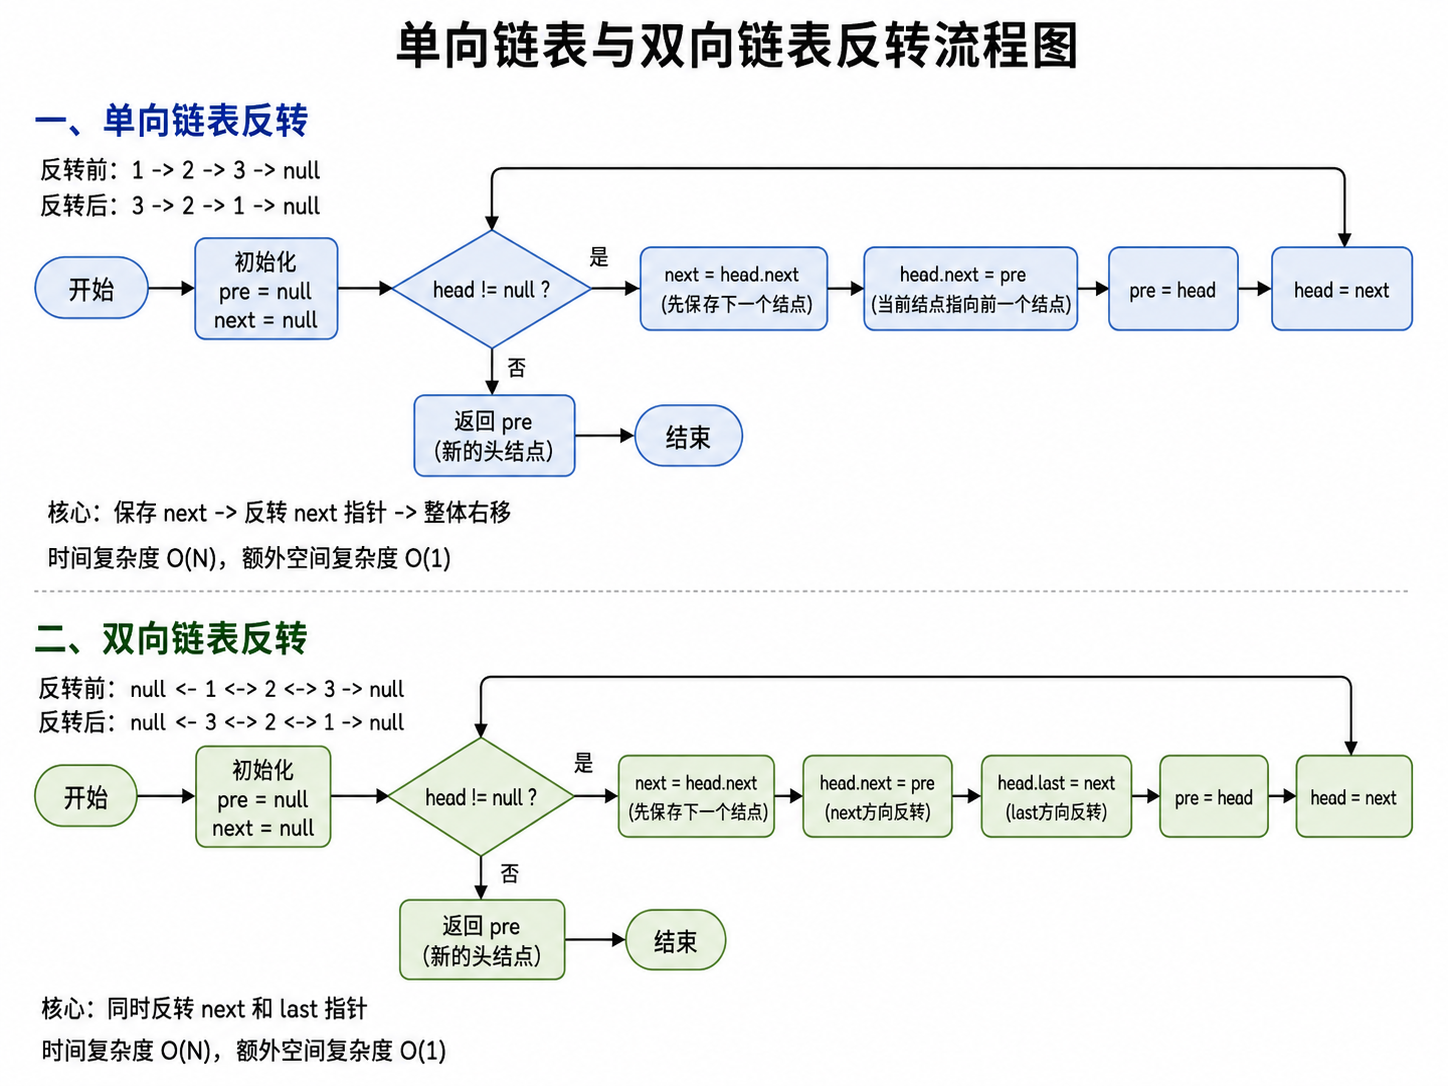
代码:
package class004;

public class Code_ReverseList {
    //=======================
    //单向链表节点
    //=======================
    public static class Node{
        public int value;
        public Node next;
        public Node(int value){
            this.value=value;
        }
    }
    //=======================
    //双向链表节点
    //=======================
    public static class DoubleNode{
        public int value;
        public DoubleNode next;
        public DoubleNode last;

        public DoubleNode(int value){
            this.value=value;
        }
    }
    //=========================
    //反转单向链表
    //=========================
    public static Node reverseLinkedList(Node head){
        Node pre=null;
        Node next=null;
        while(head!=null){
            //保存原来的下一个节点
            next=head.next;
            //当前节点指向前一个节点
            head.next=pre;
            //pre向后移动
            pre=head;
            //head向后移动
            head=next;
        }
        //返回新的头节点
        return pre;
    }
    //=========================
    //反转双向链表
    //=========================
    public static DoubleNode reverseDoubleList(DoubleNode head){
        DoubleNode pre=null;
        DoubleNode next=null;
        while(head!=null){
            //保存原来的下一个节点
            next=head.next;
            //next反向
            head.next=pre;
            //last反向
            head.last=next;
            //pre向后移动
            pre=head;
            //head向后移动
            head=next;
        }
        //返回新的头节点
        return pre;
    }
    //打印单向链表
    public static void printLinkedList(Node head){
        while(head!=null){
            System.out.print(head.value+" ");
            head=head.next;
        }
        System.out.println();
    }
    //打印双向链表
    public static void printDoubleList(DoubleNode head){
        while(head!=null){
            System.out.print(head.value+" ");
            head=head.next;
        }
        System.out.println();
    }
    public static void main(String [] args){
        //========================
        //测试单向链表
        //========================
        Node node1=new Node(1);
        Node node2=new Node(2);
        Node node3=new Node(3);

        node1.next=node2;
        node2.next=node3;
        System.out.println("单链表反转前:");
        printLinkedList(node1);

        Node newHead=reverseLinkedList(node1);
        System.out.println("单链表反转后:");
        printLinkedList(newHead);

        //========================
        //测试双向链表
        //========================
        DoubleNode d1=new DoubleNode(1);
        DoubleNode d2=new DoubleNode(2);
        DoubleNode d3=new DoubleNode(3);

        d1.next=d2;
        d2.last=d1;
        d2.next=d3;
        d3.last=d2;

        System.out.println("双链表反转前: ");
        printDoubleList(d1);
        DoubleNode newDoubleHead=reverseDoubleList(d1);

        System.out.println("双链表反转后: ");
        printDoubleList(newDoubleHead);
    }
}
运行结果:
单链表反转前:
1 2 3
单链表反转后:
3 2 1
双链表反转前:
1 2 3
双链表反转后:
3 2 1
6.打印两个有序链表的公共部分
【题目】给定两个有序链表的头指针head1和head2,打印两个链表的公共部分。
【要求】如果两个链表的长度之和为N,时间复杂度要求为O(N),额外空间复杂度要求为O(1)。
分析:
规则:a{i}和b{i}谁小谁先移动;相等时打印数字,打印完共同移动;越界后终止。
例如:{1->2->5-null}和{0->2->3->5-null},对应序列编号{1(a1)->2(a2)->5(a3)-null}和{0(b1)->2(b2)->3(b3)->5(b4)-null},分别设置两个指针p1,p2。初始化,p1指向a1,p2指向b1,a{i}和b{i}谁小谁先移动,由于a1>b1,p2右移动指向b2(2);接着,a1<b2,则p1向右移动指向a2(2);由于a2(2)=b2(2),打印数字2,且p1右移动指向a3(5),p2右移动指向b3(3);此时,由于b3<a3,p2右移动到b4(5);由于a3(5)=b4(5),打印数字5,且p1右移动指向null,p2右移动指向null,发生越界,终止。
代码:
package class004;

public class Code_PrintCommonPart {
    //单链表节点
    public static class Node{
        public int value;
        public Node next;
        public Node(int value){
            this.value=value;
        }
    }
    //打印两个有序链表的公共部分
    public static void printCommonPart(Node head1,Node head2){
        Node p1=head1;
        Node p2=head2;
        //只要两个指针都没有越界,就继续比较
        while(p1!=null && p2!=null){
            //p1的值小,p1向后移动
            if(p1.value<p2.value){
                p1=p1.next;
            }
            //p2的值小,p2向右移动
            else if(p1.value>p2.value){
                p2=p2.next;
            }
            //两个值相等
            else {
                System.out.println(p1.value+" ");
                //两个指针同时向后移动
                p1=p1.next;
                p2=p2.next;
            }
        }
        System.out.println();
    }
    public static void main(String [] args){
        //链表1:
        //1->2->5->null
        Node a1=new Node(1);
        Node a2=new Node(2);
        Node a3=new Node(5);
        a1.next=a2;
        a2.next=a3;
        //链表2:
        //0->2->3->5_null
        Node b1=new Node(0);
        Node b2=new Node(2);
        Node b3=new Node(3);
        Node b4=new Node(5);

        b1.next=b2;
        b2.next=b3;
        b3.next=b4;

        System.out.println("链表1:1->2->5->null");
        System.out.println("链表2:0->2->3->5_null");
        System.out.println("两个链表的公共部分: ");
        printCommonPart(a1,b1);
    }
}
运行结果:
链表1:1->2->5->null
链表2:0->2->3->5_null
两个链表的公共部分:
2
5
7.面试时链表解题的方法论
1)对于笔试,不用太在乎空间复杂度,一切为了时间复杂度
2)对于面试,时间复杂度依然放在第一位,但是一定要找到空间最省的方法
重要技巧:
1)额外数据结构记录(哈希表等)
2)快慢指针
(三)面试题
1.判断一个链表是否为回文结构
【题目】给定一个单链表的头节点head,请判断该链表是否为回文结构。(leetcode234,剑指offer27)
【例子】
1->2->1,返回true;
1->2->2->1,返回true;
15->6->15,返回true;
1->2->3,返回false。
【要求】如果链表长度为N,时间复杂度达到O(N),额外空间复杂度达到O(1)。
分析:
(1)方法一,O(N)的空间复杂度,只用给定的单链表,采用“括号匹配”的方法,全部压入栈,弹出的时候依次对应
(2)方法二,O(N/2)的空间复杂度,加入”快慢指针“,采用“括号匹配”的方法,将右半部分压入栈后弹出,左半部分依次比对,节省一半的栈空间。举例:对于一个链表,设置一个慢指针S,一次走一步,快指针F,一次走两步。当快指针走完的时候,慢指针走到终点的位置,这个时候,就可以把慢指针背后的结点放到栈里面去。细节处理:实现具体函数时,当链表结点是奇数时,慢指针要停在中点,当链表结点是偶数时,要确保慢指针停在对称轴左边第一个节点。特殊要求:如果测试用例非常小和刁钻,比如只有两个或三个节点,那么慢指针走到一半也许需要在第一个节点停下;题目条件可能会要求慢指针在中点前两个节点停下,例如{1,2,3,2,1}中S停在2处,{1,2,3,3,2,1}中停在2处。
(3)方法三(通常是面试时会考察的),O(1)的空间复杂度例,如链表{1->2->3->2->1},对应{a1,a2,a3,a4,a5},快慢指针S和F走完一轮后,慢指针S走到了3(a3)的位置并记录标志,快指针F走到了1(a5)位置,此时,将链表变成{1->2->3<-2<-1}。接着依次复制S走过的节点的值,让快指针F从a5位置往回走直到中点标志位(这里是a3)取走过结点的值进行对比。最后再返回true和false之前要把链表结构改回原样。
| 方法 | 思路 | 时间 | 额外空间 |
|---|---|---|---|
| 方法一 | 全部压栈 | O(N) | O(N) |
| 方法二 | 快慢指针,只压一半 | O(N) | O(N/2),即O(N) |
| 方法三 | 快慢指针 + 反转链表 | O(N) | O(1) |
方法一:

全链表
   ↓
全部压栈
   ↓
简单,但空间 O(N)


方法二:

快慢指针
   ↓
找到一半
   ↓
只压一半
   ↓
空间仍然 O(N),但省一半


方法三:

快慢指针
   ↓
找到中间
   ↓
原地反转后半部分
   ↓
两边比较
   ↓
恢复链表
   ↓
空间 O(1)
代码实现:
package class004;

import java.util.Stack;

public class Code_IsPalindromeList {
    //单链表节点
    public static class Node{
        public int value;
        public Node next;
        public Node(int value){
            this.value=value;
        }
    }
    //=======================
    //方法一:全部节点压入栈
    //时间O(N)
    //空间O(N)
    public static boolean isPalindrome1(Node head){
        if(head==null || head.next==null){
            return true;
        }
        Stack<Node>stack=new Stack<>();
        Node cur=head;
        //所有节点压栈
        while(cur!=null){
            stack.push(cur);
            cur=cur.next;
        }
        //从头开始,与栈顶依次比较
        cur=head;
        while (cur!=null){
            if (cur.value!=stack.pop().value){
                return false;
            }
            cur=cur.next;
        }
        return true;
    }
    //===========================
    //方法二:快速指针+把右半部分压栈
    //时间O(N)
    //空间O(N/2)
    public static boolean isPalindrome2(Node head){
        if (head==null||head.next==null){
            return true;
        }
        Node slow=head;
        Node fast=head;
        /*
         * slow最终来到中间位置附近
         *
         * 奇数:
         * 1 2 3 2 1
         *     ↑
         *    slow
         *
         * 偶数:
         * 1 2 2 1
         *     ↑
         *    slow
         */
        while (fast!=null&&fast.next!=null){
            slow=slow.next;
            fast=fast.next.next;
        }
        /*
         * 如果fast != null:
         * 说明链表长度为奇数
         * slow此时位于真正的中点
         *
         * 中点不用比较,所以从slow.next开始
         *
         * 如果fast == null:
         * 说明链表长度为偶数
         * slow就是右半部分第一个节点
         */
        Node right;
        if (fast!=null){
            right=slow.next;
        }else {
            right=slow;
        }
        Stack<Node>stack=new Stack<>();
        //右半部分压栈
        while (right!=null){
            stack.push(right);
            right=right.next;
        }
        Node cur=head;
        //左半部分与栈比较
        while(!stack.isEmpty()){
            if(cur.value!=stack.pop().value){
                return false;
            }
            cur=cur.next;
        }
        return true;
    }
    //============================
    //方法三:
    //快慢指针+反转后半部分
    //时间O(N)
    //空间O(1)
    //============================
    public static boolean isPalindrome3(Node head){
        if (head==null||head.next==null){
            return true;
        }
        //slow:慢指针
        Node slow=head;
        //fast:快指针
        Node fast=head;
        /*
         * 找中点
         *
         * 奇数:
         *
         * 1 -> 2 -> 3 -> 2 -> 1
         *           ↑
         *          slow
         *
         * 偶数:
         *
         * 1 -> 2 -> 2 -> 1
         *      ↑
         *     slow
         *
         * 偶数时slow停在左中点
         */
        while (fast.next!=null&&fast.next.next!=null){
            slow=slow.next;
            fast=fast.next.next;
        }
        //===========================
        //开始反转slow后面的链表
        //===========================
        Node cur=slow.next;
        //暂时把左半部分断开
        slow.next=null;
        Node next=null;
        /*
         * 此时slow相当于反转过程中的pre
         *
         * 例如:
         *
         * 1 -> 2 -> 3 -> 2 -> 1
         *
         * slow = 3
         *
         * 最后得到:
         *
         * 1 -> 2 -> 3 <- 2 <- 1
         */
        while (cur!=null){
            next=cur.next;
            cur.next=slow;
            slow=cur;
            cur=next;
        }
        /*
         * slow现在位于链表最右端
         *
         * 保存它,因为之后还需要恢复链表
         */
        Node rightHead=slow;
        //==============================
        //从左右两边开始比较
        //==============================
        Node left=head;
        Node right=rightHead;
        boolean result=true;
        while (left!=null&&right!=null){
            if(left.value!=right.value){
                result=false;
                break;
            }
            left=left.next;
            right=right.next;
        }
        //=============================
        //恢复链表
        //=============================
        cur=rightHead.next;
        rightHead.next=null;
        while(cur!=null){
            next=cur.next;
            cur.next=rightHead;
            rightHead=cur;
            cur=next;
        }
        return result;
    }
    //=================================
    //打印链表
    //=================================
    public static void printList(Node head){
        while(head!=null){
            System.out.println(head.value);
            if(head.next!=null){
                System.out.print("->");
            }
            head=head.next;
        }
        System.out.println();
    }
    public static void main(String[] args) {

        // =========================
        // 测试1:5个节点
        // 1 -> 2 -> 3 -> 2 -> 1
        // 回文
        // =========================
        Node n1 = new Node(1);
        Node n2 = new Node(2);
        Node n3 = new Node(3);
        Node n4 = new Node(2);
        Node n5 = new Node(1);

        n1.next = n2;
        n2.next = n3;
        n3.next = n4;
        n4.next = n5;

        System.out.println("====== 5个节点测试 ======");
        System.out.println("原链表:");
        printList(n1);

        System.out.println("方法一:" + isPalindrome1(n1));
        System.out.println("方法二:" + isPalindrome2(n1));
        System.out.println("方法三:" + isPalindrome3(n1));

        System.out.println("方法三执行后的链表:");
        printList(n1);


        // =========================
        // 测试2:2个节点
        // 1 -> 1
        // 回文
        // =========================
        Node a1 = new Node(1);
        Node a2 = new Node(1);

        a1.next = a2;

        System.out.println("====== 2个节点测试1 ======");
        System.out.println("原链表:");
        printList(a1);

        System.out.println("方法一:" + isPalindrome1(a1));
        System.out.println("方法二:" + isPalindrome2(a1));
        System.out.println("方法三:" + isPalindrome3(a1));

        System.out.println("方法三执行后的链表:");
        printList(a1);


        // =========================
        // 测试3:2个节点
        // 1 -> 2
        // 不是回文
        // =========================
        Node b1 = new Node(1);
        Node b2 = new Node(2);

        b1.next = b2;

        System.out.println("====== 2个节点测试2 ======");
        System.out.println("原链表:");
        printList(b1);

        System.out.println("方法一:" + isPalindrome1(b1));
        System.out.println("方法二:" + isPalindrome2(b1));
        System.out.println("方法三:" + isPalindrome3(b1));

        System.out.println("方法三执行后的链表:");
        printList(b1);


        // =========================
        // 测试4:3个节点
        // 1 -> 2 -> 1
        // 回文
        // =========================
        Node c1 = new Node(1);
        Node c2 = new Node(2);
        Node c3 = new Node(1);

        c1.next = c2;
        c2.next = c3;

        System.out.println("====== 3个节点测试1 ======");
        System.out.println("原链表:");
        printList(c1);

        System.out.println("方法一:" + isPalindrome1(c1));
        System.out.println("方法二:" + isPalindrome2(c1));
        System.out.println("方法三:" + isPalindrome3(c1));

        System.out.println("方法三执行后的链表:");
        printList(c1);


        // =========================
        // 测试5:3个节点
        // 1 -> 2 -> 3
        // 不是回文
        // =========================
        Node d1 = new Node(1);
        Node d2 = new Node(2);
        Node d3 = new Node(3);

        d1.next = d2;
        d2.next = d3;

        System.out.println("====== 3个节点测试2 ======");
        System.out.println("原链表:");
        printList(d1);

        System.out.println("方法一:" + isPalindrome1(d1));
        System.out.println("方法二:" + isPalindrome2(d1));
        System.out.println("方法三:" + isPalindrome3(d1));

        System.out.println("方法三执行后的链表:");
        printList(d1);
    }
}
运行结果:
====== 5个节点测试 ======
原链表:
1
->2
->3
->2
->1

方法一:true
方法二:true
方法三:true
方法三执行后的链表:
1
->2
->3
->2
->1

====== 2个节点测试1 ======
原链表:
1
->1

方法一:true
方法二:true
方法三:true
方法三执行后的链表:
1
->1

====== 2个节点测试2 ======
原链表:
1
->2

方法一:false
方法二:false
方法三:false
方法三执行后的链表:
1
->2

====== 3个节点测试1 ======
原链表:
1
->2
->1

方法一:true
方法二:true
方法三:true
方法三执行后的链表:
1
->2
->1

====== 3个节点测试2 ======
原链表:
1
->2
->3

方法一:false
方法二:false
方法三:false
方法三执行后的链表:
1
->2
->3
2.将单向链表按某值划分成左边小、中间相等、右边大的形式
【题目】给定一个单链表的头节点head,节点的值类型是整型,再给定一个整数pivot。实现一个调整链表的函数,将链表调整为左部分都是值小于pivot的节点,中间部分都是值等于pivot的节点,右部分都是值大于pivot的节点。
【进阶】在实现原问题功能的基础上增加如下的要求
【要求】调整后所有小于pivot的节点之间的相对顺序和调整前一样
【要求】调整后所有等于pivot的节点之间的相对顺序和调整前一样
【要求】调整后所有大于pivot的节点之间的相对顺序和调整前一样
【要求】时间复杂度请达到O(N),额外空间复杂度请达到O(1)。
(1)笔试方法:创建一个Node类型的数组,把单链表每个节点的值放到Node类型的数组中去,然后用partition,接着把每个node串起来。
(2)面试方法:首先初始化六个变量和一个指针,SH(小于部分的头)=null,ST(小于部分的尾)=null,EH(等于部分的头)=null,ET(等于部分的尾)=null,BH(大于部分的头)=null,BT(大于部分的尾)=null。以单链表{4->6->3->5->8->5->2}为例子:
| 轮次 | 指针位置 | SH | ST | EH | ET | BH | BT |
| 0 | SH=null | ST=null | EH=null | ET=null | BH=null | BT=null | |
| 1 | 4 | SH=4 | ST=4 | EH=null | ET=null | BH=null | BT=null |
| 2 | 6 | SH=4 | ST=4 | EH=null | ET=null | BH=6 | BT=6 |
| 3 | 3 | SH=4 | ST=3(SH->ST){4->3} | EH=null | ET=null | BH=6 | BT=6 |
| 4 | 5 | SH=4 | ST=3(SH->ST){4->3} | EH=5 | ET=5 | BH=6 | BT=6 |
| 5 | 8 | SH=4 | ST=3(SH->ST){4->3} | EH=5 | ET=5 | BH=6 | BT=8(BH->BT){6->8} |
| 6 | 5 | SH=4 | ST=3(SH->ST){4->3} | EH=5 | ET=5(EH->ET){5->5} | BH=6 | BT=8(BH->BT){6->8} |
| 7 | 2 | SH=4 | ST=2(SH->ST){4->3->2} | EH=5 | ET=5(EH->ET){5->5} | BH=6 | BT=8(BH->BT){6->8} |
得到小于区域(SH->ST){4->3->2},等于区域(EH->ET){5->5},大于区域(BH->BT){6->8}。
最后,将小于区域的尾连等于区域的头,等于区域的尾连大于区域的头。注意:实际情况要判断这些区域是否存在值,讨论边界条件,否则空指针会报错。
代码:
package class004;

public class Code_SmallerEqualBigger {
    public static class Node{
        public int value;
        public Node next;
        public Node(int data){
            this.value=data;
        }
    }
    public static Node listPartition1(Node head,int pivot){
        if(head==null){
            return head;
        }
        Node cur=head;
        int i=0;
        while (cur!=null){
            i++;
            cur=cur.next;
        }
        Node[] nodeArr=new Node[i];
        i=0;
        cur=head;
        for(i=0;i!=nodeArr.length;i++){
            nodeArr[i]=cur;
            cur=cur.next;
        }
        arrPartition(nodeArr,pivot);
        for(i=1;i!=nodeArr.length;i++){
            nodeArr[i-1].next=nodeArr[i];
        }
        nodeArr[i-1].next=null;
        return nodeArr[0];
    }

    public static void arrPartition(Node[] nodeArr,int pivot){
        int small=-1;
        int big=nodeArr.length;
        int index=0;
        while (index!=big){
            if(nodeArr[index].value<pivot){
                swap(nodeArr,++small,index++);
            }else if(nodeArr[index].value==pivot){
                index++;
            }else {
                swap(nodeArr,--big,index);
            }
        }
    }
    public static void swap(Node[] nodeArr,int a,int b){
        Node tmp=nodeArr[a];
        nodeArr[a]=nodeArr[b];
        nodeArr[b]=tmp;
    }

    public static Node listPartition2(Node head,int pivot){
        Node sH=null;//small head
        Node sT=null;//small tail
        Node eH=null;//equal head
        Node eT=null;//equal tail
        Node mH=null;//big head
        Node mT=null;//big tail
        Node next=null;//save next node
        //every node distributed to three lists
        while (head!=null){
            next=head.next;
            head.next=null;
            if(head.value<pivot){
                if(sH==null){
                    sH=head;
                    sT=head;
                }else {
                    sT.next=head;
                    sT=head;
                }
            }else if (head.value==pivot){
                if(eH==null){
                    eH=head;
                    eT=head;
                }else {
                    eT.next=head;
                    eT=head;
                }
            }else {
                if(mH==null){
                    mH=head;
                    mT=head;
                }else {
                    mT.next=head;
                    mT=head;
                }
            }
            head=next;
        }
        //small and equal reconnect
        if(sT !=null){//如果有小于区域
            sT.next=eH;
            eT=eT==null?sT:eT;//下一步,谁去连大于区域的头,谁就变成eT
        }
        //上面的if,不管跑了没有,et
        //all reconnect
        if (eT!=null){//如果小于区域和等于区域,不是都没有
            eT.next=mH;
        }
        return sH !=null?sH:(eH!=null?eH:mH);
    }
    public static void printLinkedList(Node node) {
        System.out.print("Linked List: ");
        while (node != null) {
            System.out.print(node.value);
            if (node.next != null) {
                System.out.print(" -> ");
            }
            // 非常重要
            node = node.next;
        }
        System.out.println();
    }
    // ========================================
    // 创建链表,方便测试
    // ========================================
    public static Node buildList(int[] arr) {
        if (arr == null || arr.length == 0) {
            return null;
        }
        Node head = new Node(arr[0]);
        Node cur = head;
        for (int i = 1; i < arr.length; i++) {

            cur.next = new Node(arr[i]);

            cur = cur.next;
        }
        return head;
    }

    public static void main(String[] args) {
        int pivot = 5;
        // ========================================
        // 测试1
        // 同时存在 <、=、> 三个区域
        // ========================================
        int[] arr1 = {4, 6, 3, 5, 8, 5, 2};
        Node head1 = buildList(arr1);
        System.out.println("====== 测试1:方法一 ======");
        System.out.println("pivot = " + pivot);
        System.out.println("调整前:");
        printLinkedList(head1);
        head1 = listPartition1(head1, pivot);
        System.out.println("调整后:");
        printLinkedList(head1);
        // ========================================
        // 方法二需要重新创建链表
        // 因为方法一已经改变了原链表结构
        // ========================================
        Node head2 = buildList(arr1);
        System.out.println();
        System.out.println("====== 测试1:方法二 ======");
        System.out.println("pivot = " + pivot);
        System.out.println("调整前:");
        printLinkedList(head2);
        head2 = listPartition2(head2, pivot);
        System.out.println("调整后:");
        printLinkedList(head2);
        // ========================================
        // 测试2:没有等于区域
        // ========================================
        int[] arr2 = {7, 3, 8, 2, 6, 1};
        Node head3 = buildList(arr2);
        System.out.println();
        System.out.println("====== 测试2:没有等于区域 ======");
        System.out.println("调整前:");
        printLinkedList(head3);
        head3 = listPartition2(head3, 5);
        System.out.println("调整后:");
        printLinkedList(head3);
        // ========================================
        // 测试3:只有小于区域
        // ========================================
        int[] arr3 = {1, 2, 3, 4};
        Node head4 = buildList(arr3);
        System.out.println();
        System.out.println("====== 测试3:只有小于区域 ======");
        System.out.println("调整前:");
        printLinkedList(head4);
        head4 = listPartition2(head4, 5);
        System.out.println("调整后:");
        printLinkedList(head4);
        // ========================================
        // 测试4:只有等于区域
        // ========================================
        int[] arr4 = {5, 5, 5, 5};
        Node head5 = buildList(arr4);
        System.out.println();
        System.out.println("====== 测试4:只有等于区域 ======");
        System.out.println("调整前:");
        printLinkedList(head5);
        head5 = listPartition2(head5, 5);
        System.out.println("调整后:");
        printLinkedList(head5);
        // ========================================
        // 测试5:只有大于区域
        // ========================================
        int[] arr5 = {8, 7, 9, 6};
        Node head6 = buildList(arr5);
        System.out.println();
        System.out.println("====== 测试5:只有大于区域 ======");
        System.out.println("调整前:");
        printLinkedList(head6);
        head6 = listPartition2(head6, 5);
        System.out.println("调整后:");
        printLinkedList(head6);
    }
}
运行结果:
====== 测试1:方法一 ======
pivot = 5
调整前:
Linked List: 4 -> 6 -> 3 -> 5 -> 8 -> 5 -> 2
调整后:
Linked List: 4 -> 2 -> 3 -> 5 -> 5 -> 8 -> 6

====== 测试1:方法二 ======
pivot = 5
调整前:
Linked List: 4 -> 6 -> 3 -> 5 -> 8 -> 5 -> 2
调整后:
Linked List: 4 -> 3 -> 2 -> 5 -> 5 -> 6 -> 8

====== 测试2:没有等于区域 ======
调整前:
Linked List: 7 -> 3 -> 8 -> 2 -> 6 -> 1
调整后:
Linked List: 3 -> 2 -> 1 -> 7 -> 8 -> 6

====== 测试3:只有小于区域 ======
调整前:
Linked List: 1 -> 2 -> 3 -> 4
调整后:
Linked List: 1 -> 2 -> 3 -> 4

====== 测试4:只有等于区域 ======
调整前:
Linked List: 5 -> 5 -> 5 -> 5
调整后:
Linked List: 5 -> 5 -> 5 -> 5

====== 测试5:只有大于区域 ======
调整前:
Linked List: 8 -> 7 -> 9 -> 6
调整后:
Linked List: 8 -> 7 -> 9 -> 6

Process finished with exit code 0
通过测试用例可知:
| 方法 | 时间复杂度 | 额外空间 | 稳定性 |
|---|---|---|---|
listPartition1 | O(N) | O(N) | 不稳定 |
listPartition2 | O(N) | O(1) | 稳定 |
3.复制含有随机指针节点的链表
【题目】一种特殊的单链表节点类描述如下(leetcode138,剑指35)
class Node {
    int value;
    Node next;
    Node rand;

    Node(int val) {
        value = val;
    }
}
rand指针是单链表节点结构中新增的指针,rand可能指向链表中的任意一个节点,也可能指向null。给定一个由Node节点类型组成的无环单链表的头节点head,请实现一个函数完成这个链表的复制,并返回复制的新链表的头节点。
【要求】时间复杂度O(N),额外空间复杂度O(1)。
分析:
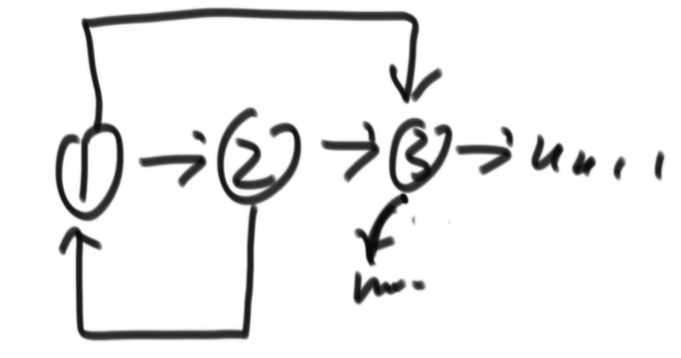
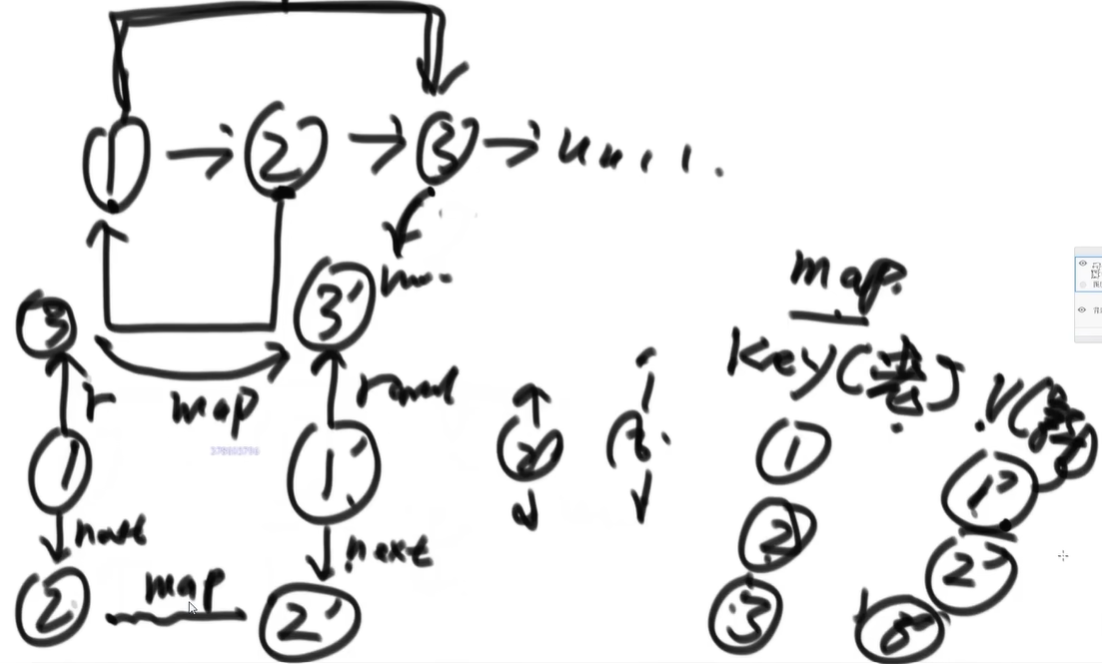
(1)用hashmap的方法:
第一步,不考虑新链表中新指针怎么连的问题,采用map的方式,把老链表中的节点和指针拷贝出来,放到一个新链表中去,其中包括key(老节点),value(新节点)。
第一回遍历,克隆老节点对应新节点的关系,得到表格
| map次数 | key(老) | value(新) |
| 1 | 1 | 1' |
| 2 | 2 | 2' |
| 3 | 3 | 3' |
第二回遍历,设置next和rand方向的指针。先确定next指针,{node1 next->node2},{node1' next->node2'},由表格可知{node2 next(map) node2'};接着确定rand方向的指针,{node1 rand->node3},{node1' rand->node3'},由表格可知{node3 map node3'},也就是说,来到每一个node i时,设置node的next和rand指针,最后把node i'返回。如图所示:
(2)不用hash表的写法:
首先构造:{node1 next->node1',node1' next->node2,node2 next->node2',node2' next->node3,node3 next->node3'},{node1 rand->node3},{node2 rand->node1},{node3 rand->null};接着遍历的时候一对一对拿,比如{node1 rand->node3},{node1' rand->node3'},必然可以得出{node3 next->node3'},这样每一个rand指针的克隆节点都可以设置好;最后在next指针的方向上把新老链表分离出来。核心思路:
第一步:
老1 -> 新1 -> 老2 -> 新2 -> 老3 -> 新3

第二步:
通过 老rand.next
找到对应的新rand

第三步:
把老链表和新链表拆开
代码:
package class004;

import java.util.HashMap;

public class Code_CopyListWithRandom {
    public static class Node{
        public int value;
        public Node next;
        public Node rand;
        public Node(int data){
            this.value=data;
        }
    }

    public  static Node copyListWithRand1(Node head){
        HashMap<Node,Node>map=new HashMap<Node,Node>();
        Node cur=head;
        while(cur!=null){
            //克隆节点挂到map里去
            map.put(cur,new Node(cur.value));
            cur=cur.next;
        }
        cur=head;
        while(cur!=null){
            //cur 老
            //map.get(cur)新,已经在上一个循环建立
            map.get(cur).next=map.get(cur.next);
            map.get(cur).rand=map.get(cur.rand);
            cur=cur.next;
        }
        return map.get(head);
    }

    public static Node copyListWithRand2(Node head){
        if(head==null){
            return null;
        }
        Node cur=head;
        Node next=null;
        //copy node and link to every node
        //1->2
        //1->1'->2
        while(cur!=null){
            //第一步,当前节点的下一个就放它的克隆节点,它的克隆节点就是next
            //克隆节点的再下一个,就是老的下一个
            next=cur.next;
            cur.next=new Node(cur.value);
            cur.next.next=next;
            cur=next;
        }
        cur=head;
        Node curCopy=null;
        //set copy node rand
        //1->1'->2->2'
        while (cur!=null){
            next=cur.next.next;
            curCopy=cur.next;
            //如果cur.rand不等于空,那么cur的克隆节点找到了,那么cur.rand的克隆节点是谁呢,
            //由于位置依赖,就是它的下一个节点;如果cur.rand等于空,那么cur的克隆节点就是空节点
            curCopy.rand=cur.rand !=null?cur.rand.next:null;
            cur=next;
        }
        Node res=head.next;
        cur=head;
        //split
        while(cur!=null){
            next=cur.next.next;
            curCopy=cur.next;
            cur.next=next;
            curCopy.next=next!=null?next.next:null;
            cur=next;
        }
        return res;
    }
    // ======================================
    // 打印链表
    //
    // 格式:
    //
    // 1(rand->3) -> 2(rand->1) -> 3(rand->null)
    // ======================================
    public static void printLinkedList(Node head) {
        while (head!=null){
            System.out.print(head.value);
            System.out.print("(rand->");
            if(head.rand!=null){
                System.out.print(head.rand.value);
            }else {
                System.out.print("null");
            }
            System.out.print(")");

            if(head.next!=null){
                System.out.print("->");
            }
            head=head.next;
        }
        System.out.println();
    }
    public static void main(String[] args) {
        // ======================================
        // 测试1:
        //
        // next:
        // 1 -> 2 -> 3
        //
        // rand:
        // 1 -> 3
        // 2 -> 1
        // 3 -> null
        // ======================================
        Node n1 = new Node(1);
        Node n2 = new Node(2);
        Node n3 = new Node(3);

        n1.next = n2;
        n2.next = n3;

        n1.rand = n3;
        n2.rand = n1;
        n3.rand = null;
        System.out.println("====== 原链表 ======");
        printLinkedList(n1);
        // ======================================
        // 测试方法一
        // ======================================
        Node copy1 = copyListWithRand1(n1);
        System.out.println();
        System.out.println("====== 方法一:HashMap复制 ======");
        printLinkedList(copy1);
        // ======================================
        // 测试方法二
        // ======================================
        Node copy2 = copyListWithRand2(n1);
        System.out.println();
        System.out.println("====== 方法二:O(1)额外空间复制 ======");
        printLinkedList(copy2);
        // ======================================
        // 检查原链表是否恢复
        // ======================================
        System.out.println();
        System.out.println("====== 方法二执行后的原链表 ======");
        printLinkedList(n1);
        // ======================================
        // 检查是否是真正的深拷贝
        // ======================================
        System.out.println();
        System.out.println("====== 检查是否为不同对象 ======");
        System.out.println("原head == 方法一copy?" + (n1 == copy1));
        System.out.println("原head == 方法二copy?" + (n1 == copy2));
        // ======================================
        // 测试2:只有一个节点
        //
        // 5.rand -> 5
        // ======================================
        Node single = new Node(5);
        single.rand = single;
        System.out.println();
        System.out.println("====== 单节点测试 ======");
        System.out.println("原链表:");
        printLinkedList(single);
        Node singleCopy = copyListWithRand2(single);
        System.out.println("复制链表:");
        printLinkedList(singleCopy);
        // ======================================
        // 测试3:空链表
        // ======================================
        System.out.println();
        System.out.println("====== 空链表测试 ======");
        Node nullCopy = copyListWithRand2(null);
        System.out.println(nullCopy == null ? "复制结果:null" : "复制失败");
    }
}
运行结果:
====== 原链表 ======
1(rand->3)->2(rand->1)->3(rand->null)

====== 方法一:HashMap复制 ======
1(rand->3)->2(rand->1)->3(rand->null)

====== 方法二:O(1)额外空间复制 ======
1(rand->3)->2(rand->1)->3(rand->null)

====== 方法二执行后的原链表 ======
1(rand->3)->2(rand->1)->3(rand->null)

====== 检查是否为不同对象 ======
原head == 方法一copy?false
原head == 方法二copy?false

====== 单节点测试 ======
原链表:
5(rand->5)
复制链表:
5(rand->5)

====== 空链表测试 ======
复制结果:null
| 方法 | 核心思路 | 时间 | 额外空间 |
|---|---|---|---|
| HashMap | 老节点 -> 新节点 映射 | O(N) | O(N) |
| 穿插复制 | 老节点.next = 新节点 代替Map | O(N) | O(1) |
4.两个单链表相交的一系列问题
leetcode160
【题目】给定两个可能有环也可能无环的单链表,头节点head1和head2。请实现一个函数,如果两个链表相交,请返回相交的第一个节点。如果不相交,返回null。
【要求】如果两个链表长度之和为N,时间复杂度请达到O(N),额外空间复杂度请达到O(1)。
分析:
首先明白相交是什么意思,比如第一个链表的序列是{a1->a2->a3->a4},第二个链表的序列是{b1->b2->b3},其中a3和b2是同一个节点(内存地址相同,而不是值相同),那么{a3,b2}称为第一个相交节点;接着判断一个链表有环和无环是什么意思,对于一个链表序列{a1->a2->a3->a4->a5->a3},那么a3是第一个入环节点,{a3->a4->a5->a3}构成一个环。
说明由于单链表的设定(只有一个next指针),只能出现有环的{a->b->c->d->e->c}或无环的结构{a->b->c->d->e},不可能出现{a->b->c->d->e->c->f->g}的结构,这样就有两个next指针了,所以不行。
思路1,hashmap实现:
例如,一个有环单链表{a->b->c->d->e->c},设定一个集合Set,初始化为空集合
| 执行次数 | 指针位置 | 元素i是否在set内? | 操作 | Set |
| 0 | null | 无 | {} | |
| 1 | a | 不在 | a入Set | {a} |
| 2 | b | 不在 | b入Set | {a,b} |
| 3 | c | 不在 | c入Set | {a,b,c} |
| 4 | d | 不在 | d入Set | {a,b,c,d} |
| 5 | e | 不在 | e入Set | {a,b,c,d,e} |
| 6 | c | 在 | c是第一个节点 |
具体可以采用快慢指针实现。对于链表{a->b->c->d->e->f->g->h->I->f},环是{f->g->h->I->f},设置快指针F和慢指针S,F和S的起点都在a。首先,如果F走到最后发现是空节点,那么这个链表肯定没有环。如果这个链表有环的话,快指针和慢指针肯定会在这个环的节点相遇。
第一轮:
| 轮次 | 慢指针S位置 | 快指针F位置 | next指针方向节点>2? | 快指针F是否回越过相交节点? | F和S是否相遇? |
| 0 | a | a | 是 | 否 | |
| 1 | b | c | 是 | 否 | |
| 2 | c | e | 是 | 否 | |
| 3 | d | g | 是 | 否 | |
| 4 | e | I | 否 | 否 | |
| 5 | f | g | 是 | 是 | |
| 6 | g | I | 否 | 否 | |
| 7 | h | g | 是 | 是 | |
| 8 | I | I | 否 | 否 | 相遇 |
这个时候,令快指针F回到开头a,慢指针留在原地I。接下来,规定每个指针一次都只能走一步,两个指针同时按照next方向走,快指针的路线{a->b->c->d->e->f},走了五步,到达f;慢指针的路线{I->f->g->h->I->f},走了五步。于是快指针和慢指针再次相遇,不过这个相遇节点是环的开始节点。
结论:m是外节点数,n是环节点数,S一共走了2m+n-n%m步,在环上走了m+n-n%m步,一定是n的倍数,一定回到环的头。证明略,见leetcode142,leetcode LCR023。
接下来,就可以讨论两个链表相交的问题了。
head1一次循环后,得到第一个入环节点是loop1;head2一次循环后,得到第一个入环节点是loop2。
(1)loop1==null,loop2==null,有两种情况:
(a)如果两个单链表不相交的话,图像是两条平行线段。
(b)如果两个单链表相交的话,图像是交汇的Y型结构,Y型的下半部分都共有。
这两种情况下,先从head1开始遍历单链表1的各个节点,直到最后一个节点,记为end1,同时记录链表长度为len1;先从head2开始遍历单链表2的各个节点,直到最后一个节点,记为end2,同时记录链表长度为len2。此时,判断end1和end2节点的内存地址是不是同一个,如果不是,那么链表1和链表2不可能相交;如果是,那么链表1和链表2存在相交节点(Y型的下半部分),此时比较len1和len2的差值,记为d,假设len1大于len2,那么让链表1的指针先走d步,接着链表2的指针开始走,最后这两个指针必然能够在相交节点相遇。
(2)loop1和loop2一个为空,一个不为空,这种情况,链表1和链表2不可能相交
(3)loop1和loop2都有环,有三种情况,如图所示
(a)如果两个单链表不相交的话,图像是两个6型图案。
(b)如果两个单链表相交的话,图像是交汇的Y型结构且Y型的下半部分呈现一个6型,且入环节点相同。
(c)如果两个单链表相交的话,图像是交汇的Y型结构且Y型的下半部分呈现一个6型,且入环节点不相同,类似于天线宝宝的头。
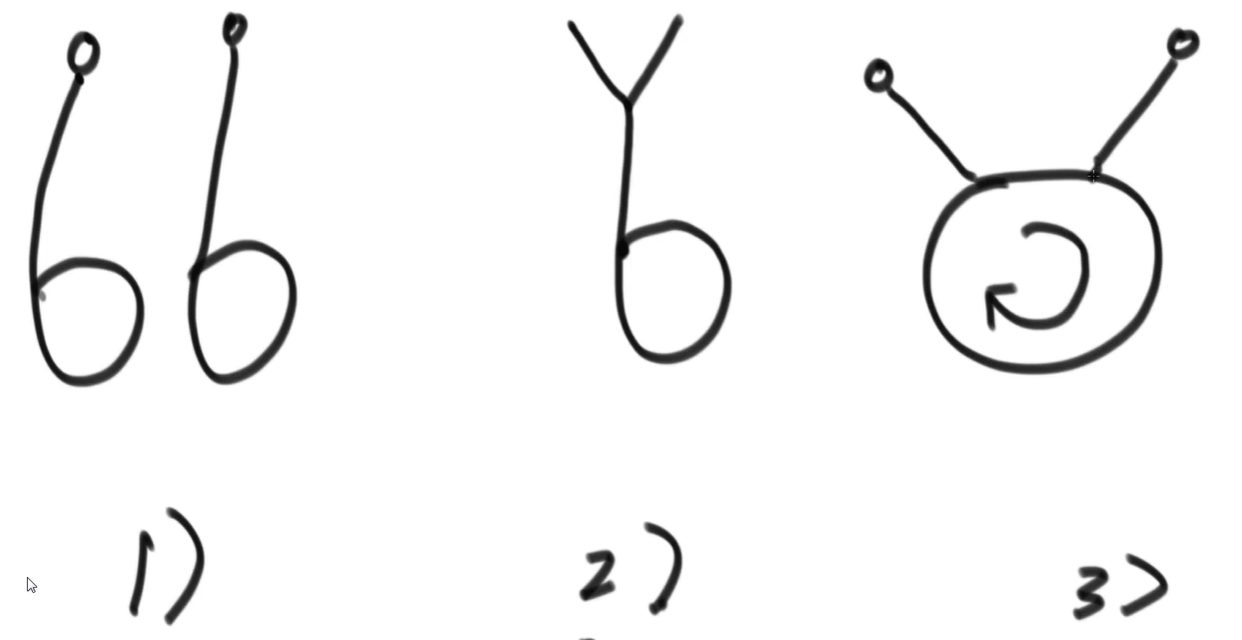
情况区分思路:情况(a),链表走到结尾后,如同情况(1)(a)那样讨论loop1和loop2的内存地址是否相同,复用代码思路。情况(b),链表走到有环交汇节点时,将图像切割成Y型和O型两个部分,像(1)(b)那样讨论Y型结构。情况(a)和(c)的区分,流程是让loop1继续往下走,如果在转回自己的过程中能够遇到loop2,就是情况(c),此时返回两个相交节点;如果在转回自己的过程中没遇到loop2,就是情况(a),此时没有相交节点。
综合判断流程:
                head1、head2
                     |
              分别找入环节点
                     |
               loop1、loop2
                     |
        ┌────────────┼────────────┐
        ↓            ↓            ↓
      都null       一个null      都不null
        |            |            |
      都无环       不可能相交      都有环
        |                         |
     noLoop()               loop1 == loop2 ?
                               /       \
                              是        否
                              |          |
                      环外按无环处理    loop1绕环
                              |          |
                       找第一个交点    能遇到loop2?
                                         /  \
                                        是   否
                                        |     |
                                      相交   不相交
实现代码:
package class004;

public class Code_FindFirstIntersectNode {
    public static class Node{
        public int value;
        public Node next;
        public Node(int data){
            this.value=data;
        }
    }
    public static Node getIntersectNode(Node head1,Node head2){
        if(head1==null||head2==null){
            return null;
        }
        Node loop1=getLoopNode(head1);
        Node loop2=getLoopNode(head2);
        if(loop1==null&&loop2==null){
            return noLoop(head1,head2);
        }
        if(loop1!=null&&loop2!=null){
            return bothLoop(head1,loop1,head2,loop2);
        }
        return null;
    }

    //找到链表第一个入环节点,如果无环,返回null
    public static Node getLoopNode(Node head){
        if (head==null||head.next==null||head.next.next==null){
            return null;
        }
        Node n1=head.next;//n1->slow
        Node n2=head.next.next;//n2->fast
        while(n1!=n2){
            if(n2.next==null||n2.next.next==null){
                return null;
            }
            n2=n2.next.next;
            n1=n1.next;
        }
        n2=head;//n2->walk again from head
        while(n1!=n2){
            n1=n1.next;
            n2=n2.next;
        }
        return n1;
    }
    //如果两个链表都无环,返回第一个相交节点,如果不相交,返回null
    public static Node noLoop(Node head1,Node head2){
        if (head1==null||head2==null){
            return null;
        }
        Node cur1=head1;
        Node cur2=head2;
        int n=0;//两个长度变量优化成一个来做,n++和n--叠加就是长度差值
        while(cur1.next!=null){
            n++;
            cur1=cur1.next;
        }
        while(cur2.next!=null){
            n--;
            cur2=cur2.next;
        }
        //判断内存地址是否相同
        if(cur1!=cur2){
            return null;
        }
        //内存地址交换,进行重定位
        cur1=n>0?head1:head2;//谁长,谁的头变成cur1
        cur2=cur1==head1?head2:head1;//谁短谁的头变成cur2
        n=Math.abs(n);
        //长链表先走差值部分,短链表再走
        while (n!=0){
            n--;
            cur1=cur1.next;
        }
        while (cur1!=cur2){
            cur1=cur1.next;
            cur2=cur2.next;
        }
        //第一个相交的节点
        return cur1;
    }
    //两个有环链表,返回第一个相交节点,如果不相交返回null
    public static Node bothLoop(Node head1,Node loop1,Node head2,Node loop2){
        Node cur1=null;
        Node cur2=null;
        //情况二
        if(loop1==loop2){
            cur1=head1;
            cur2=head2;
            int n=0;
            while (cur1!=loop1){
                n++;
                cur1=cur1.next;
            }
            while (cur2!=loop2){
                n--;
                cur2=cur2.next;
            }
            //重定位
            cur1=n>0?head1:head2;
            cur2=cur1==head1?head2:head1;
            n=Math.abs(n);
            while (n!=0){
                n--;
                cur1=cur1.next;
            }
            while (cur1!=cur2){
                cur1=cur1.next;
                cur2=cur2.next;
            }
            return cur1;
        }else {
            cur1=loop1.next;
            while (cur1!=loop1){
                if(cur1==loop2){
                    return loop1;
                }
                cur1=cur1.next;
            }
            return null;
        }
    }
    public static void main(String[] args) {

        // =====================================================
        // 测试1:两个无环链表相交
        //
        // head1:
        // 1 -> 2 -> 3 \
        //               6 -> 7
        // 4 -> 5 ------/
        // head2:
        //
        // 第一个相交节点:6
        // =====================================================

        Node common1 = new Node(6);
        Node common2 = new Node(7);

        common1.next = common2;

        Node a1 = new Node(1);
        Node a2 = new Node(2);
        Node a3 = new Node(3);

        a1.next = a2;
        a2.next = a3;
        a3.next = common1;

        Node b1 = new Node(4);
        Node b2 = new Node(5);

        b1.next = b2;
        b2.next = common1;

        System.out.println("====== 测试1:两个无环链表相交 ======");

        Node ans1 = getIntersectNode(a1, b1);

        System.out.println(
                ans1 != null
                        ? "第一个相交节点:" + ans1.value
                        : "不相交"
        );


        // =====================================================
        // 测试2:两个无环链表不相交
        //
        // 1 -> 2 -> 3
        //
        // 4 -> 5 -> 6
        //
        // 结果:null
        // =====================================================

        Node c1 = new Node(1);
        Node c2 = new Node(2);
        Node c3 = new Node(3);

        c1.next = c2;
        c2.next = c3;

        Node d1 = new Node(4);
        Node d2 = new Node(5);
        Node d3 = new Node(6);

        d1.next = d2;
        d2.next = d3;

        System.out.println();
        System.out.println("====== 测试2:两个无环链表不相交 ======");

        Node ans2 = getIntersectNode(c1, d1);

        System.out.println(
                ans2 != null
                        ? "第一个相交节点:" + ans2.value
                        : "不相交"
        );


        // =====================================================
        // 测试3:一个有环,一个无环
        //
        // 无环:
        // 1 -> 2 -> 3
        //
        // 有环:
        // 4 -> 5 -> 6
        //      ↑    |
        //      └────┘
        //
        // 不可能相交
        // =====================================================

        Node e1 = new Node(1);
        Node e2 = new Node(2);
        Node e3 = new Node(3);

        e1.next = e2;
        e2.next = e3;

        Node f1 = new Node(4);
        Node f2 = new Node(5);
        Node f3 = new Node(6);

        f1.next = f2;
        f2.next = f3;
        f3.next = f2;

        System.out.println();
        System.out.println("====== 测试3:一个有环,一个无环 ======");

        Node ans3 = getIntersectNode(e1, f1);

        System.out.println(
                ans3 != null
                        ? "第一个相交节点:" + ans3.value
                        : "不相交"
        );


        // =====================================================
        // 测试4:两个有环链表
        // 入环节点相同,并且在入环之前已经相交
        //
        // head1:
        // 1 -> 2 \
        //          5 -> 6 -> 7 -> 8
        // 3 -> 4 /      ↑         |
        // head2:         └─────────┘
        //
        // 第一个相交节点:5
        // 入环节点:6
        // =====================================================

        Node g5 = new Node(5);
        Node g6 = new Node(6);
        Node g7 = new Node(7);
        Node g8 = new Node(8);

        g5.next = g6;
        g6.next = g7;
        g7.next = g8;
        g8.next = g6; // 入环点6

        Node g1 = new Node(1);
        Node g2 = new Node(2);

        g1.next = g2;
        g2.next = g5;

        Node h1 = new Node(3);
        Node h2 = new Node(4);

        h1.next = h2;
        h2.next = g5;

        System.out.println();
        System.out.println("====== 测试4:同一入环点,环前相交 ======");

        System.out.println(
                "head1入环节点:" + getLoopNode(g1).value
        );

        System.out.println(
                "head2入环节点:" + getLoopNode(h1).value
        );

        Node ans4 = getIntersectNode(g1, h1);

        System.out.println(
                ans4 != null
                        ? "第一个相交节点:" + ans4.value
                        : "不相交"
        );


        // =====================================================
        // 测试5:两个有环链表
        // 入环节点相同,在入环节点才第一次相交
        //
        // 1 -> 2 ----\
        //              6 -> 7 -> 8
        // 3 -> 4 -> 5 /
        //              ↑         |
        //              └─────────┘
        //
        // 第一个相交节点:6
        // =====================================================

        Node loop6 = new Node(6);
        Node loop7 = new Node(7);
        Node loop8 = new Node(8);

        loop6.next = loop7;
        loop7.next = loop8;
        loop8.next = loop6;

        Node i1 = new Node(1);
        Node i2 = new Node(2);

        i1.next = i2;
        i2.next = loop6;

        Node j1 = new Node(3);
        Node j2 = new Node(4);
        Node j3 = new Node(5);

        j1.next = j2;
        j2.next = j3;
        j3.next = loop6;

        System.out.println();
        System.out.println("====== 测试5:同一入环点,在入环点相交 ======");

        Node ans5 = getIntersectNode(i1, j1);

        System.out.println(
                ans5 != null
                        ? "第一个相交节点:" + ans5.value
                        : "不相交"
        );


        // =====================================================
        // 测试6:两个有环链表
        // 属于同一个环,但是入环节点不同
        //
        //             6 -> 7
        //            ↑     ↓
        // head1 -> 6       8
        //            ↑     ↓
        //            9 <- 8
        //
        // head1从6入环
        // head2从8入环
        //
        // loop1 != loop2
        // 但是两个入口属于同一个环
        //
        // 返回loop1或loop2都可以
        // 当前代码返回loop1
        // =====================================================

        Node k6 = new Node(6);
        Node k7 = new Node(7);
        Node k8 = new Node(8);
        Node k9 = new Node(9);

        k6.next = k7;
        k7.next = k8;
        k8.next = k9;
        k9.next = k6;

        Node k1 = new Node(1);
        Node k2 = new Node(2);

        k1.next = k2;
        k2.next = k6; // head1从6入环

        Node l1 = new Node(3);
        Node l2 = new Node(4);

        l1.next = l2;
        l2.next = k8; // head2从8入环

        System.out.println();
        System.out.println("====== 测试6:同一环,不同入环节点 ======");

        Node loopNode1 = getLoopNode(k1);
        Node loopNode2 = getLoopNode(l1);

        System.out.println(
                "head1入环节点:" + loopNode1.value
        );

        System.out.println(
                "head2入环节点:" + loopNode2.value
        );

        Node ans6 = getIntersectNode(k1, l1);

        System.out.println(
                ans6 != null
                        ? "返回的相交节点:" + ans6.value
                        : "不相交"
        );


        // =====================================================
        // 测试7:两个有环链表,但属于两个独立的环
        //
        // 链表1:
        // 1 -> 2 -> 3 -> 4
        //           ↑      |
        //           └──────┘
        //
        // 链表2:
        // 5 -> 6 -> 7 -> 8
        //           ↑      |
        //           └──────┘
        //
        // 结果:不相交
        // =====================================================

        Node m1 = new Node(1);
        Node m2 = new Node(2);
        Node m3 = new Node(3);
        Node m4 = new Node(4);

        m1.next = m2;
        m2.next = m3;
        m3.next = m4;
        m4.next = m3;

        Node n1 = new Node(5);
        Node n2 = new Node(6);
        Node n3 = new Node(7);
        Node n4 = new Node(8);

        n1.next = n2;
        n2.next = n3;
        n3.next = n4;
        n4.next = n3;

        System.out.println();
        System.out.println("====== 测试7:两个独立的环 ======");

        Node ans7 = getIntersectNode(m1, n1);

        System.out.println(
                ans7 != null
                        ? "第一个相交节点:" + ans7.value
                        : "不相交"
        );


        // =====================================================
        // 测试8:空链表
        // =====================================================

        System.out.println();
        System.out.println("====== 测试8:空链表 ======");

        Node ans8 = getIntersectNode(null, a1);

        System.out.println(
                ans8 == null
                        ? "结果:null"
                        : "错误"
        );
    }
}
运行结果:
====== 测试1:两个无环链表相交 ======
第一个相交节点:6

====== 测试2:两个无环链表不相交 ======
不相交

====== 测试3:一个有环,一个无环 ======
不相交

====== 测试4:同一入环点,环前相交 ======
head1入环节点:6
head2入环节点:6
第一个相交节点:5

====== 测试5:同一入环点,在入环点相交 ======
第一个相交节点:6

====== 测试6:同一环,不同入环节点 ======
head1入环节点:6
head2入环节点:8
返回的相交节点:6

====== 测试7:两个独立的环 ======
不相交

====== 测试8:空链表 ======
结果:null

 962


 扫一扫


 被折叠的 条评论
为什么被折叠?
 到【灌水乐园】发言


