


# 一、redo log block
设计InnoDB时为了更好的进行系统奔溃恢复,将通过mtr生成的redo日志放在大小为512字节的页中。为了和表空间中的页做区别,于是把用来存储redo日志的页称为block。一个redo log block的示意图如下:
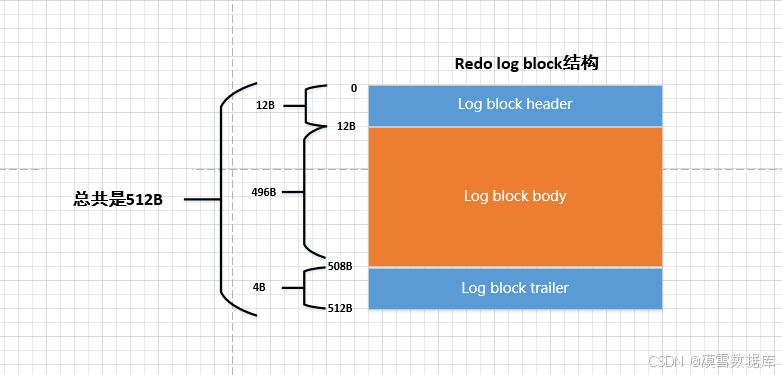
真正的redo日志都是存储到占用496字节大小的log block body中。另外,log block header占12个字节,log block trailer占4个字节,存储的是一些管理信息。
其中,log block header中包含以下属性字段:
LOG_BLOCK_HDR_NO(4B):每一个block都有一个大于0的唯一标号,该属性就表示该标号值。LOG_BLOCK_HDR_DATA_LEN(2B):表示block中已经使用了多少字节,初始值为12。随着往block中写入的redo日志越来也多,该值也跟着增长。如果log block body已经被全部写满,那么值被设置为512。LOG_BLOCK_FIRST_REC_GROUP(2B):一条redo日志也可以称之为一条redo日志记录,一个mtr会生产多条redo日志记录,这些redo日志记录被称之为一个redo日志记录组(redo log record group)。LOG_BLOCK_FIRST_REC_GROUP就代表该block中第一个mtr生成的redo日志记录组的偏移量,即这个block里第一个mtr生成的第一条redo日志的偏移量。LOG_BLOCK_CHECKPOINT_NO(4B):表示checkpoint的序号。
log block trailer中包含的属性字段为:
LOG_BLOCK_CHECKSUM(4B):表示block的校验值,用于正确性校验。
二、redo日志缓冲区
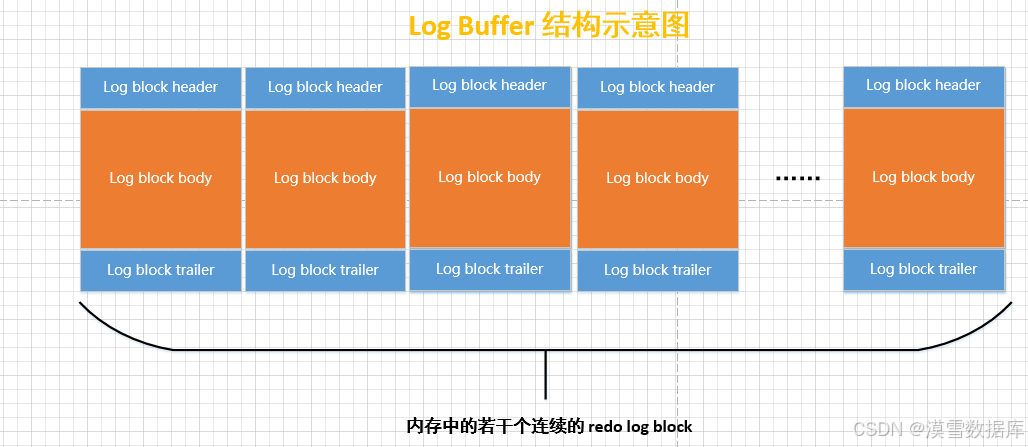
与为了解决磁盘速度过慢的问题而引入了Buffer Pool的思想类似,写入redo日志时也不能直接直接写到磁盘上。实际上在服务器启动时就向操作系统申请了一大⽚称之为redo log buffer的连续内存空间,即redo日志缓冲区,也可以简称为log buffer。这⽚内存空间被划分成若干个连续的redo log block,如图所示:
三、redo日志写入log buffer
向log buffer中写入redo日志的过程是顺序的,也就是先往前边的block中写,当该block的空闲空间用完之后再往下一个block中写。因此,当往log buffer中写入redo日志时,第一个遇到的问题就是应该写在哪个block的哪个偏移量处,所以InnoDB的特意提供了一个称之为buf_free的全局变量,该变量指明后续写入的redo日志应该写入到log buffer中的哪个位置。
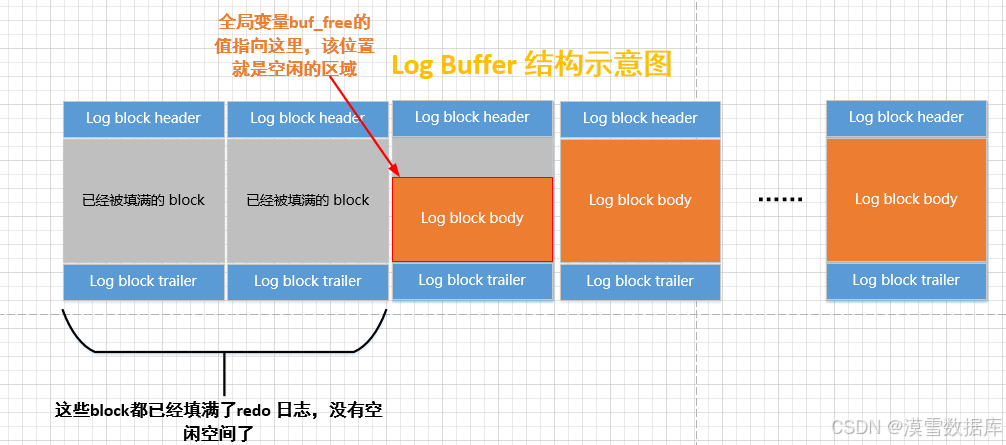
由于一个mtr执行过程中可能产生若干条redo日志,这些redo日志是一个不可分割的组,所以其实并不是每生成一条redo日志,就将其插入到log buffer中,而是每个mtr运行过程中产生的日志先暂时存到一个地方,当该mtr结束的时候,将过程中产生的一组redo日志再全部复制到log buffer中。
四、源码解析
4.1 log buffer结构体
/** Redo log buffer */
struct log_t{
	char		pad1[CACHE_LINE_SIZE];
					/*!< Padding to prevent other memory
					update hotspots from residing on the
					same memory cache line */
	lsn_t		lsn;		/*!< log sequence number */
	ulint		buf_free;	/*!< first free offset within the log
					buffer in use */
	byte*		buf_ptr;	/*!< unaligned log buffer, which should
					be of double of buf_size */
	byte*		buf;		/*!< log buffer currently in use;
					this could point to either the first
					half of the aligned(buf_ptr) or the
					second half in turns, so that log
					write/flush to disk don't block
					concurrent mtrs which will write
					log to this buffer */
	bool		first_in_use;	/*!< true if buf points to the first
					half of the aligned(buf_ptr), false
					if the second half */
	ulint		buf_size;	/*!< log buffer size of each in bytes */
	ulint		max_buf_free;	/*!< recommended maximum value of
					buf_free for the buffer in use, after
					which the buffer is flushed */
	bool		check_flush_or_checkpoint;
					/*!< this is set when there may
					be need to flush the log buffer, or
					preflush buffer pool pages, or make
					a checkpoint; this MUST be TRUE when
					lsn - last_checkpoint_lsn >
					max_checkpoint_age; this flag is
					peeked at by log_free_check(), which
					does not reserve the log mutex */
	UT_LIST_BASE_NODE_T(log_group_t)
			log_groups;	/*!< log groups */

#ifndef UNIV_HOTBACKUP
	/** The fields involved in the log buffer flush @{ */

	ulint		buf_next_to_write;/*!< first offset in the log buffer
					where the byte content may not exist
					written to file, e.g., the start
					offset of a log record catenated
					later; this is advanced when a flush
					operation is completed to all the log
					groups */
	volatile bool	is_extending;	/*!< this is set to true during extend
					the log buffer size */
	lsn_t		write_lsn;	/*!< last written lsn */
	lsn_t		current_flush_lsn;/*!< end lsn for the current running
					write + flush operation */
	lsn_t		flushed_to_disk_lsn;
					/*!< how far we have written the log
					AND flushed to disk */
	ulint		n_pending_flushes;/*!< number of currently
					pending flushes; incrementing is
					protected by the log mutex;
					may be decremented between
					resetting and setting flush_event */
	os_event_t	flush_event;	/*!< this event is in the reset state
					when a flush is running; a thread
					should wait for this without
					owning the log mutex, but NOTE that
					to set this event, the
					thread MUST own the log mutex! */
	ulint		n_log_ios;	/*!< number of log i/os initiated thus
					far */
	ulint		n_log_ios_old;	/*!< number of log i/o's at the
					previous printout */
	time_t		last_printout_time;/*!< when log_print was last time
					called */
	/* @} */

	/** Fields involved in checkpoints @{ */
	lsn_t		log_group_capacity; /*!< capacity of the log group; if
					the checkpoint age exceeds this, it is
					a serious error because it is possible
					we will then overwrite log and spoil
					crash recovery */
	lsn_t		max_modified_age_async;
					/*!< when this recommended
					value for lsn -
					buf_pool_get_oldest_modification()
					is exceeded, we start an
					asynchronous preflush of pool pages */
	lsn_t		max_modified_age_sync;
					/*!< when this recommended
					value for lsn -
					buf_pool_get_oldest_modification()
					is exceeded, we start a
					synchronous preflush of pool pages */
	lsn_t		max_checkpoint_age_async;
					/*!< when this checkpoint age
					is exceeded we start an
					asynchronous writing of a new
					checkpoint */
	lsn_t		max_checkpoint_age;
					/*!< this is the maximum allowed value
					for lsn - last_checkpoint_lsn when a
					new query step is started */
	ib_uint64_t	next_checkpoint_no;
					/*!< next checkpoint number */
	lsn_t		last_checkpoint_lsn;
					/*!< latest checkpoint lsn */
	lsn_t		next_checkpoint_lsn;
					/*!< next checkpoint lsn */
	mtr_buf_t*	append_on_checkpoint;
					/*!< extra redo log records to write
					during a checkpoint, or NULL if none.
					The pointer is protected by
					log_sys->mutex, and the data must
					remain constant as long as this
					pointer is not NULL. */
	ulint		n_pending_checkpoint_writes;
					/*!< number of currently pending
					checkpoint writes */
	rw_lock_t	checkpoint_lock;/*!< this latch is x-locked when a
					checkpoint write is running; a thread
					should wait for this without owning
					the log mutex */
#endif /* !UNIV_HOTBACKUP */
	byte*		checkpoint_buf_ptr;/* unaligned checkpoint header */
	byte*		checkpoint_buf;	/*!< checkpoint header is read to this
					buffer */
	/* @} */
};
其中,比较重要的几个字段如下:
lsn_t lsn: 日志序列号ulint buf_free: 日志缓冲区中可以使用的第一个空闲偏移量byte* buf_ptr: 未对齐的日志缓冲区指针byte* buf: 当前正在使用的日志缓冲区bool first_in_use: true : buf指针指向前半个buf
false: buf指针指向后半个bufulint buf_next_to_write: 尚未写入文件的日志在缓冲区中的起始偏移量lsn_t write_lsn: 被写入操作系统缓冲区但未刷新到磁盘的起始日志的lsnlsn_t flushed_to_disk_lsn: 被刷新到磁盘的日志lsn
4.2 redo日志写入log buffer的过程
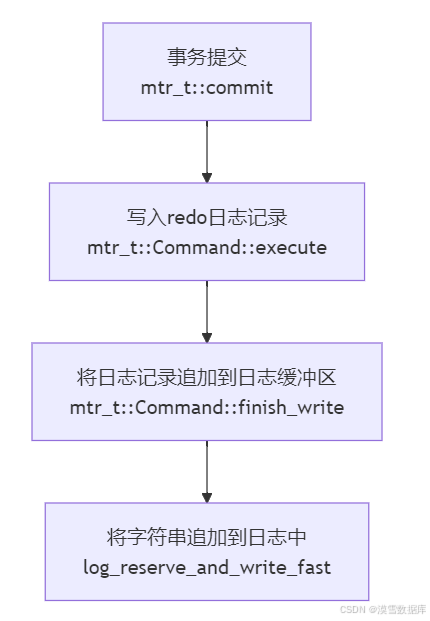
4.2.1、整体流程
4.2.2、源码解析
- 1、由于redo日志写入
log buffer中要先进行事务的提交,因此首先会调用mtr_t::commit()函数。
/** Commit a mini-transaction. */
void
mtr_t::commit()
{
   ut_ad(is_active());
   ut_ad(!is_inside_ibuf());
   ut_ad(m_impl.m_magic_n == MTR_MAGIC_N);
   m_impl.m_state = MTR_STATE_COMMITTING;

   /* This is a dirty read, for debugging. */
   ut_ad(!recv_no_log_write);

   Command	cmd(this);

   if (m_impl.m_modifications
       && (m_impl.m_n_log_recs > 0
   	|| m_impl.m_log_mode == MTR_LOG_NO_REDO)) {

   	ut_ad(!srv_read_only_mode
   	      || m_impl.m_log_mode == MTR_LOG_NO_REDO);

   	cmd.execute();
   } else {
   	cmd.release_all();
   	cmd.release_resources();
   }
}
(1)断言检查
	ut_ad(is_active());  // 确保当前事务是活跃的
	ut_ad(!is_inside_ibuf());  // 确保事务不在插入缓冲区内部执行
	ut_ad(m_impl.m_magic_n == MTR_MAGIC_N);  // 验证事务内部结构的完整性
	m_impl.m_state = MTR_STATE_COMMITTING;   // 将事务状态设置为正在提交

	ut_ad(!recv_no_log_write);  // 确保没有设置禁止日志写入的标志
(2)创建命令对象
Command cmd(this);
(3)根据条件执行或释放资源
	if (m_impl.m_modifications
	    && (m_impl.m_n_log_recs > 0
		|| m_impl.m_log_mode == MTR_LOG_NO_REDO)) {

		ut_ad(!srv_read_only_mode
		      || m_impl.m_log_mode == MTR_LOG_NO_REDO);

		cmd.execute();
	} else {
		cmd.release_all();
		cmd.release_resources();
	}
- 判断条件:事务有修改且要么有日志记录,要么设置为不重做日志模式;
- 确保不在只读模式下,或者日志模式是不重做;
- 调用写入redo日志记录的函数
execute();- 如果没有修改或不需要持久化日志记录,则释放所有锁和资源。
- 2、在
mtr_t::commit中调用execute()函数执行一系列与事务相关的操作,包括写入重做日志记录、将脏页添加到刷新列表,并释放相关资源。
/** Write the redo log record, add dirty pages to the flush list and release
the resources. */
void mtr_t::Command::execute() {
  ut_ad(m_impl->m_log_mode != MTR_LOG_NONE);

  if (const ulint len = prepare_write()) {
    finish_write(len);
  }

  if (m_impl->m_made_dirty) {
    log_flush_order_mutex_enter();
  }

  /* It is now safe to release the log mutex because the
  flush_order mutex will ensure that we are the first one
  to insert into the flush list. */
  log_mutex_exit();

  m_impl->m_mtr->m_commit_lsn = m_end_lsn;

  release_blocks();

  if (m_impl->m_made_dirty) {
    log_flush_order_mutex_exit();
  }

  release_all();

  release_resources();
}
(1)检查前置条件
ut_ad(m_impl->m_log_mode != MTR_LOG_NONE);
- 使用
ut_ad调试宏,用于在开发过程中捕获逻辑错误。- 这里用于检查日志模式是否是
MTR_LOG_NONE,确保在尝试写入日志之前,日志模式是有效的。
(2)准备写入日志
if (const ulint len = prepare_write()) {
    finish_write(len);
  }
- 首先调用
prepare_write函数准备写入日志,并获取要写入的日志长度。- 如果返回长度不为0,则表示有日志需要写入,调用
finish_write函数完成日志的写入。
(3)处理脏页
if (m_impl->m_made_dirty) {
    log_flush_order_mutex_enter();
  }
- 如果事务过程中产生了脏页,则需要进入
log_flush_order_mutex互斥锁。- 这个锁用于确保在将脏页添加到刷新列表时,没有其他线程同时修改这个列表。
(4)释放日志互斥锁
release_blocks();
- 在确保脏页将被安全处理后,可以释放log_mutex。
(5)更新提交日志序列号
m_impl->m_mtr->m_commit_lsn = m_end_lsn;
- 更新事务的提交日志序列号(LSN)为当前操作的结束LSN。
(6)释放资源并退出锁
  release_blocks();  // 释放数据块

  if (m_impl->m_made_dirty) {
    log_flush_order_mutex_exit();   // 退出互斥锁
  }

  release_all();   // 释放所有资源

  release_resources();  // 释放额外资源
- 3、在函数
mtr_t::Command::execute中调用finish_write函数完成日志的写入。
/** Append the redo log records to the redo log buffer
@param[in] len	number of bytes to write */
void
mtr_t::Command::finish_write(
	ulint	len)
{
	ut_ad(m_impl->m_log_mode == MTR_LOG_ALL);
	ut_ad(log_mutex_own());
	ut_ad(m_impl->m_log.size() == len);
	ut_ad(len > 0);

	if (m_impl->m_log.is_small()) {
		const mtr_buf_t::block_t*	front = m_impl->m_log.front();
		ut_ad(len <= front->used());

		m_end_lsn = log_reserve_and_write_fast(
			front->begin(), len, &m_start_lsn);

		if (m_end_lsn > 0) {
			return;
		}
	}

	/* Open the database log for log_write_low */
	m_start_lsn = log_reserve_and_open(len);

	mtr_write_log_t	write_log;
	m_impl->m_log.for_each_block(write_log);

	m_end_lsn = log_close();
}
(1)断言检查
    ut_ad(m_impl->m_log_mode == MTR_LOG_ALL);  // 确保当前的日志模式是记录所有更改
	ut_ad(log_mutex_own());  // 确保当前线程持有日志互斥锁
	ut_ad(m_impl->m_log.size() == len);  // 确保redo日志缓冲区中的日志记录大小与要写入的大小相同
	ut_ad(len > 0);  // 确保要写入的长度大于0
(2)快速写入检查
if (m_impl->m_log.is_small()) {
		const mtr_buf_t::block_t*	front = m_impl->m_log.front();
		ut_ad(len <= front->used());

		m_end_lsn = log_reserve_and_write_fast(
			front->begin(), len, &m_start_lsn);

		if (m_end_lsn > 0) {
			return;
		}
	}
- 如果redo日志缓冲区中的日志记录较小,则使用快速写入路径。
- 获取缓冲区的前端块(
front),并检查要写入的长度是否小于或等于该块已使用的空间。- 调用
log_reserve_and_write_fast函数尝试快速写入。成功则直接返回。
(3)常规写入路径
    m_start_lsn = log_reserve_and_open(len);

	mtr_write_log_t	write_log;
	m_impl->m_log.for_each_block(write_log);

	m_end_lsn = log_close();
- 如果快速写入失败或不适用于当前情况,则进入常规写入路径。
- 调用
log_reserve_and_open函数为日志写入预留空间,并获取起始日志序列号。- 使用
m_impl->m_log.for_each_block(write_log);遍历redo日志缓冲区中的每个块,并准备将它们写入到日志文件中。- 调用
log_close函数完成日志写入,并获取结束日志序列号。
- 4、在函数
mtr_t::Command::finish_write中的关键核心函数为log_reserve_and_write_fast,该函数用于在日志系统中快速保留空间并写入一个字符串。
/** Append a string to the log.
@param[in]	str		string
@param[in]	len		string length
@param[out]	start_lsn	start LSN of the log record
@return end lsn of the log record, zero if did not succeed */
UNIV_INLINE
lsn_t
log_reserve_and_write_fast(
	const void*	str,
	ulint		len,
	lsn_t*		start_lsn)
{
	ut_ad(log_mutex_own());
	ut_ad(len > 0);

	const ulint	data_len = len
		+ log_sys->buf_free % OS_FILE_LOG_BLOCK_SIZE;

	if (data_len >= OS_FILE_LOG_BLOCK_SIZE - LOG_BLOCK_TRL_SIZE) {

		/* The string does not fit within the current log block
		or the log block would become full */

		return(0);
	}

	*start_lsn = log_sys->lsn;

	memcpy(log_sys->buf + log_sys->buf_free, str, len);

	log_block_set_data_len(
                reinterpret_cast<byte*>(ut_align_down(
                        log_sys->buf + log_sys->buf_free,
                        OS_FILE_LOG_BLOCK_SIZE)),
                data_len);

	log_sys->buf_free += len;

	ut_ad(log_sys->buf_free <= log_sys->buf_size);

	log_sys->lsn += len;

	MONITOR_SET(MONITOR_LSN_CHECKPOINT_AGE,
		    log_sys->lsn - log_sys->last_checkpoint_lsn);

	return(log_sys->lsn);
}
(1)断言检查
ut_ad(log_mutex_own());  // 确保当前线程持有日志系统的互斥锁
ut_ad(len > 0);  // 确保字符串长度大于0
(2)计算并检查数据长度
const ulint	data_len = len
	+ log_sys->buf_free % OS_FILE_LOG_BLOCK_SIZE;  // 计算包括字符串长度和日志缓冲区当前空闲空间的对齐填充在内的总数据长度

if (data_len >= OS_FILE_LOG_BLOCK_SIZE - LOG_BLOCK_TRL_SIZE) {

	/* 如果data_len大于或等于日志块大小减去日志块尾部大小,则字符串无法在当前日志块中容纳,或者会使日志块变满,函数返回0 */

	return(0);
}
(3)写入字符串
*start_lsn = log_sys->lsn;  // 将当前日志序列号保存到start_lsn指向的变量中

memcpy(log_sys->buf + log_sys->buf_free, str, len);  // 将当前日志序列号保存到start_lsn指向的变量中
(4)更新相关数据
log_block_set_data_len(
			reinterpret_cast<byte*>(ut_align_down(
					log_sys->buf + log_sys->buf_free,
					OS_FILE_LOG_BLOCK_SIZE)),
			data_len);

log_sys->buf_free += len;

ut_ad(log_sys->buf_free <= log_sys->buf_size);

log_sys->lsn += len;
- 调用log_block_set_data_len函数,根据写入的数据长度更新日志块的数据长度;
- 更新日志缓冲区的空闲位置,并更新日志序列号,以反映新写入的字符串长度;
- 确保日志缓冲区的空闲位置不会超过其大小。
(5)结束操作
MONITOR_SET(MONITOR_LSN_CHECKPOINT_AGE,
		log_sys->lsn - log_sys->last_checkpoint_lsn);  // 更新监控指标,反映当前LSN与最后一个检查点LSN之间的差值

return(log_sys->lsn);  // 返回写入操作结束时的LSN
 449


 扫一扫


 被折叠的 条评论
为什么被折叠?
 到【灌水乐园】发言


